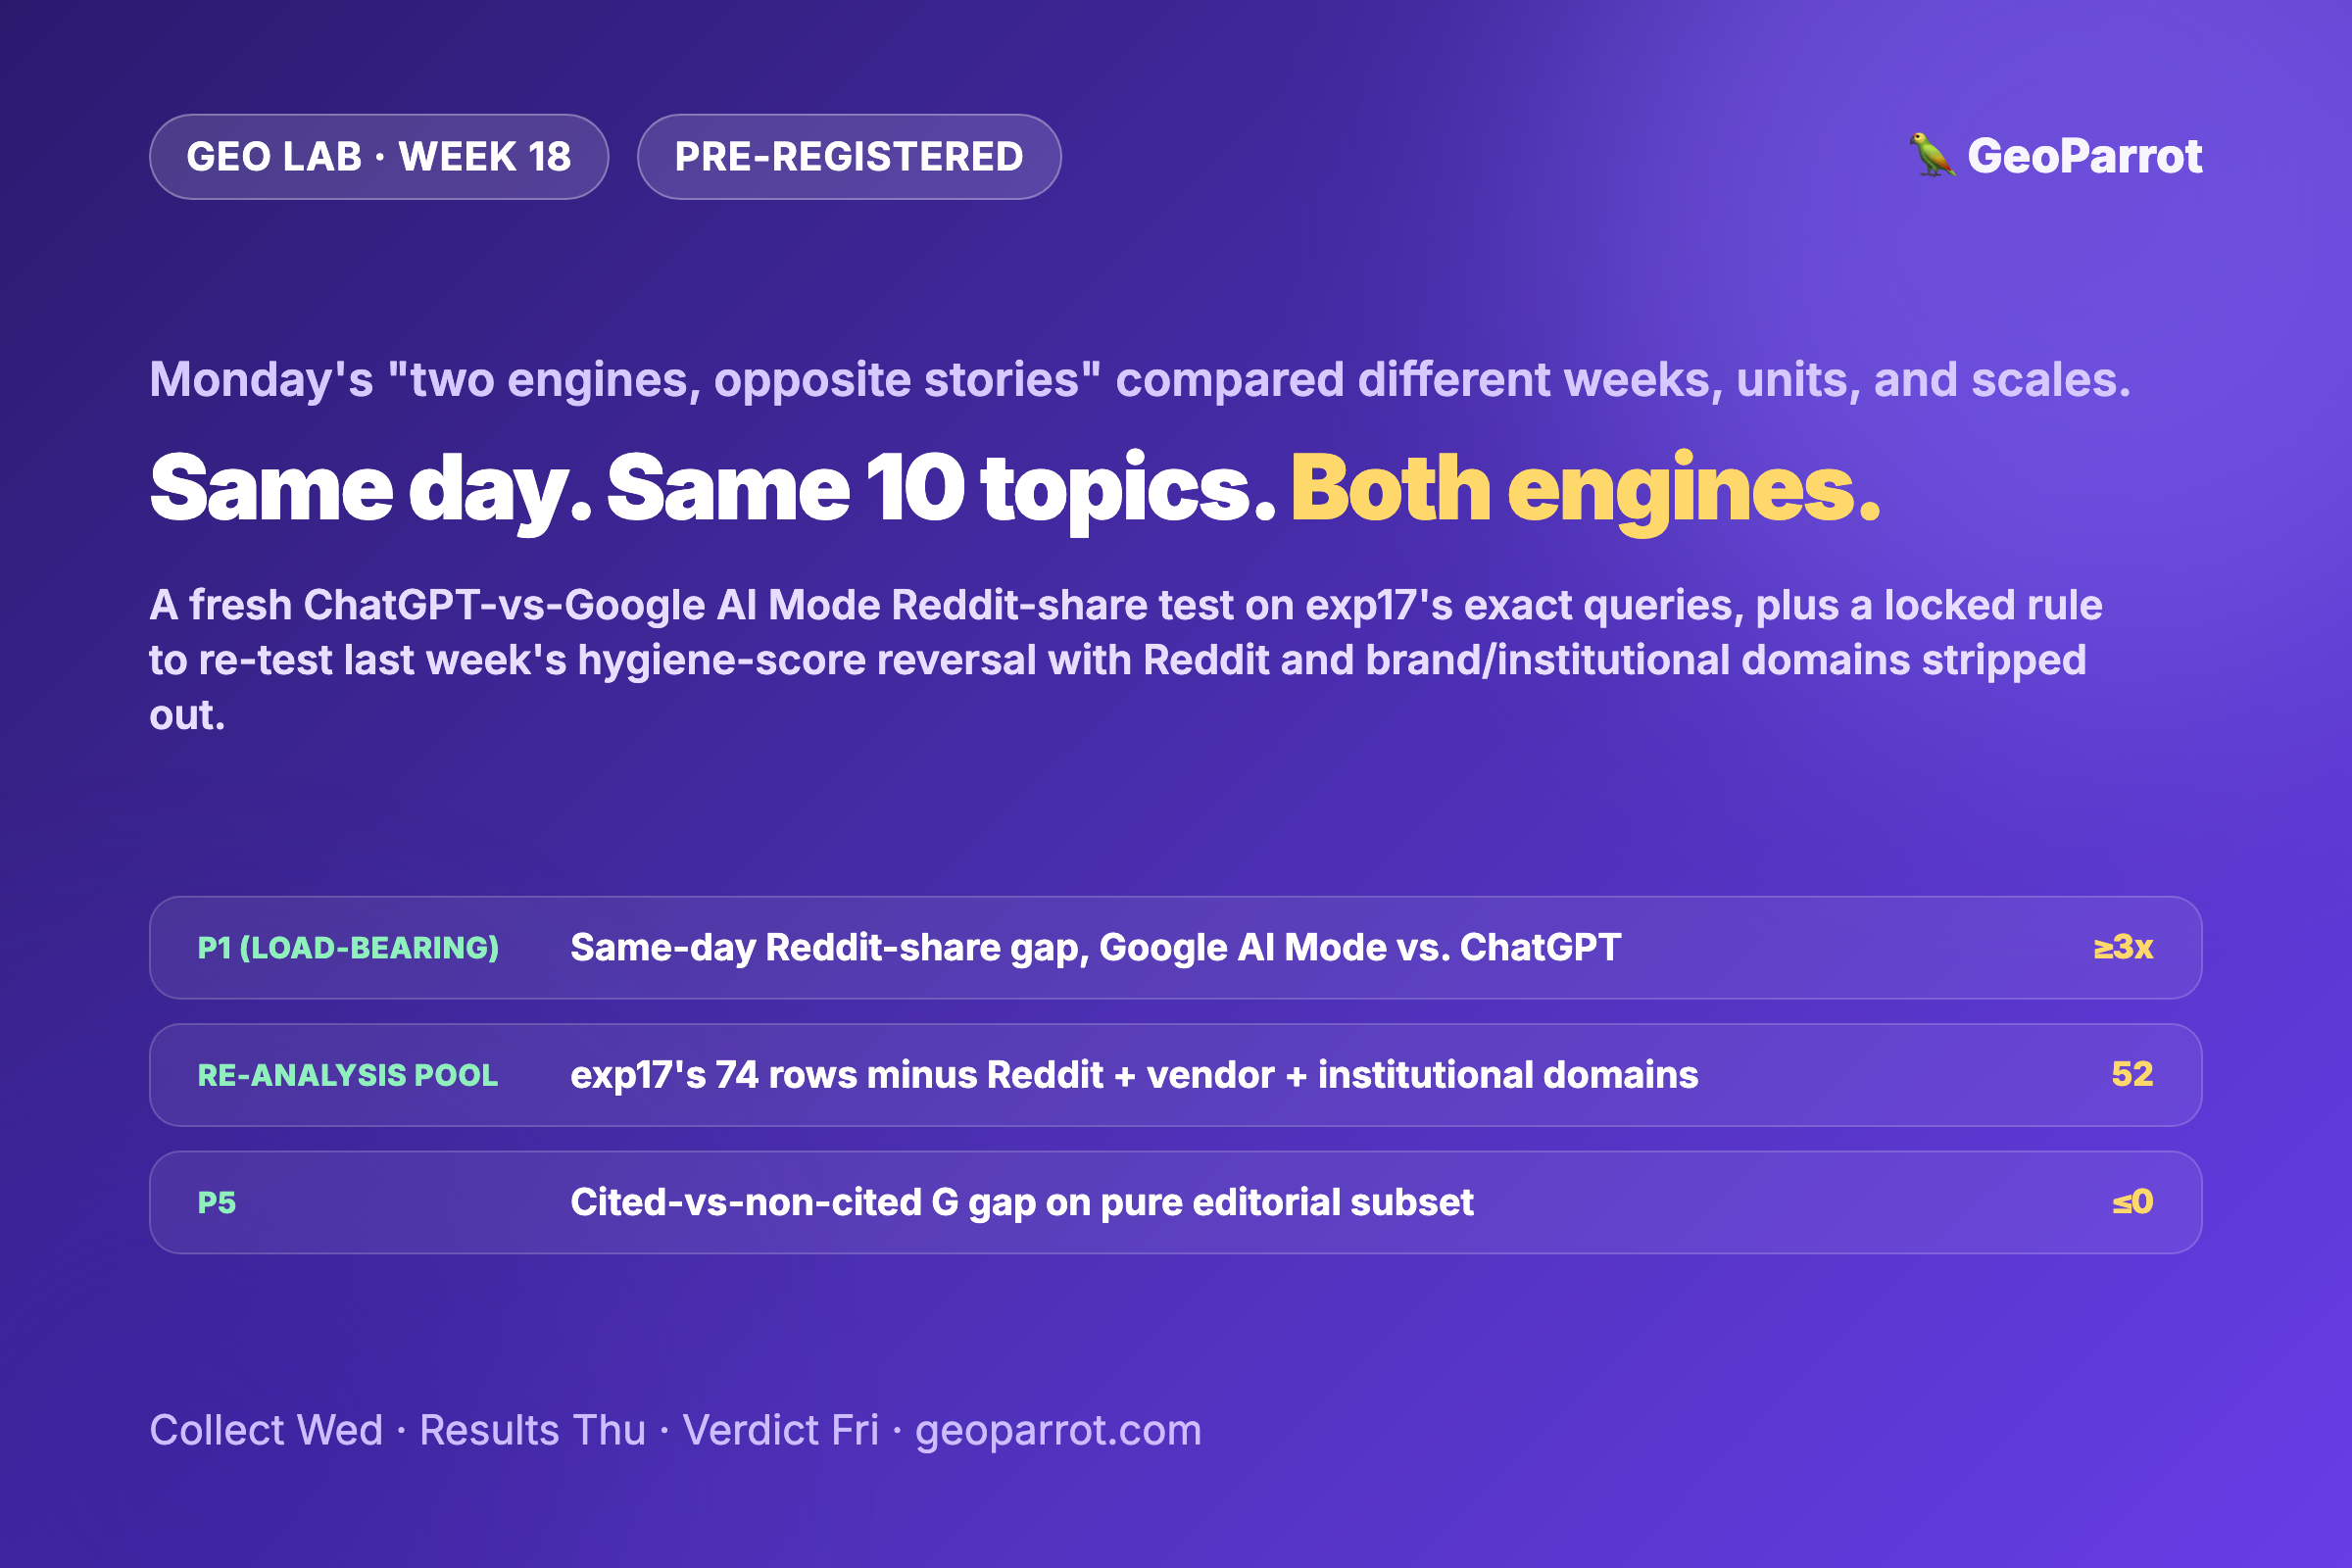
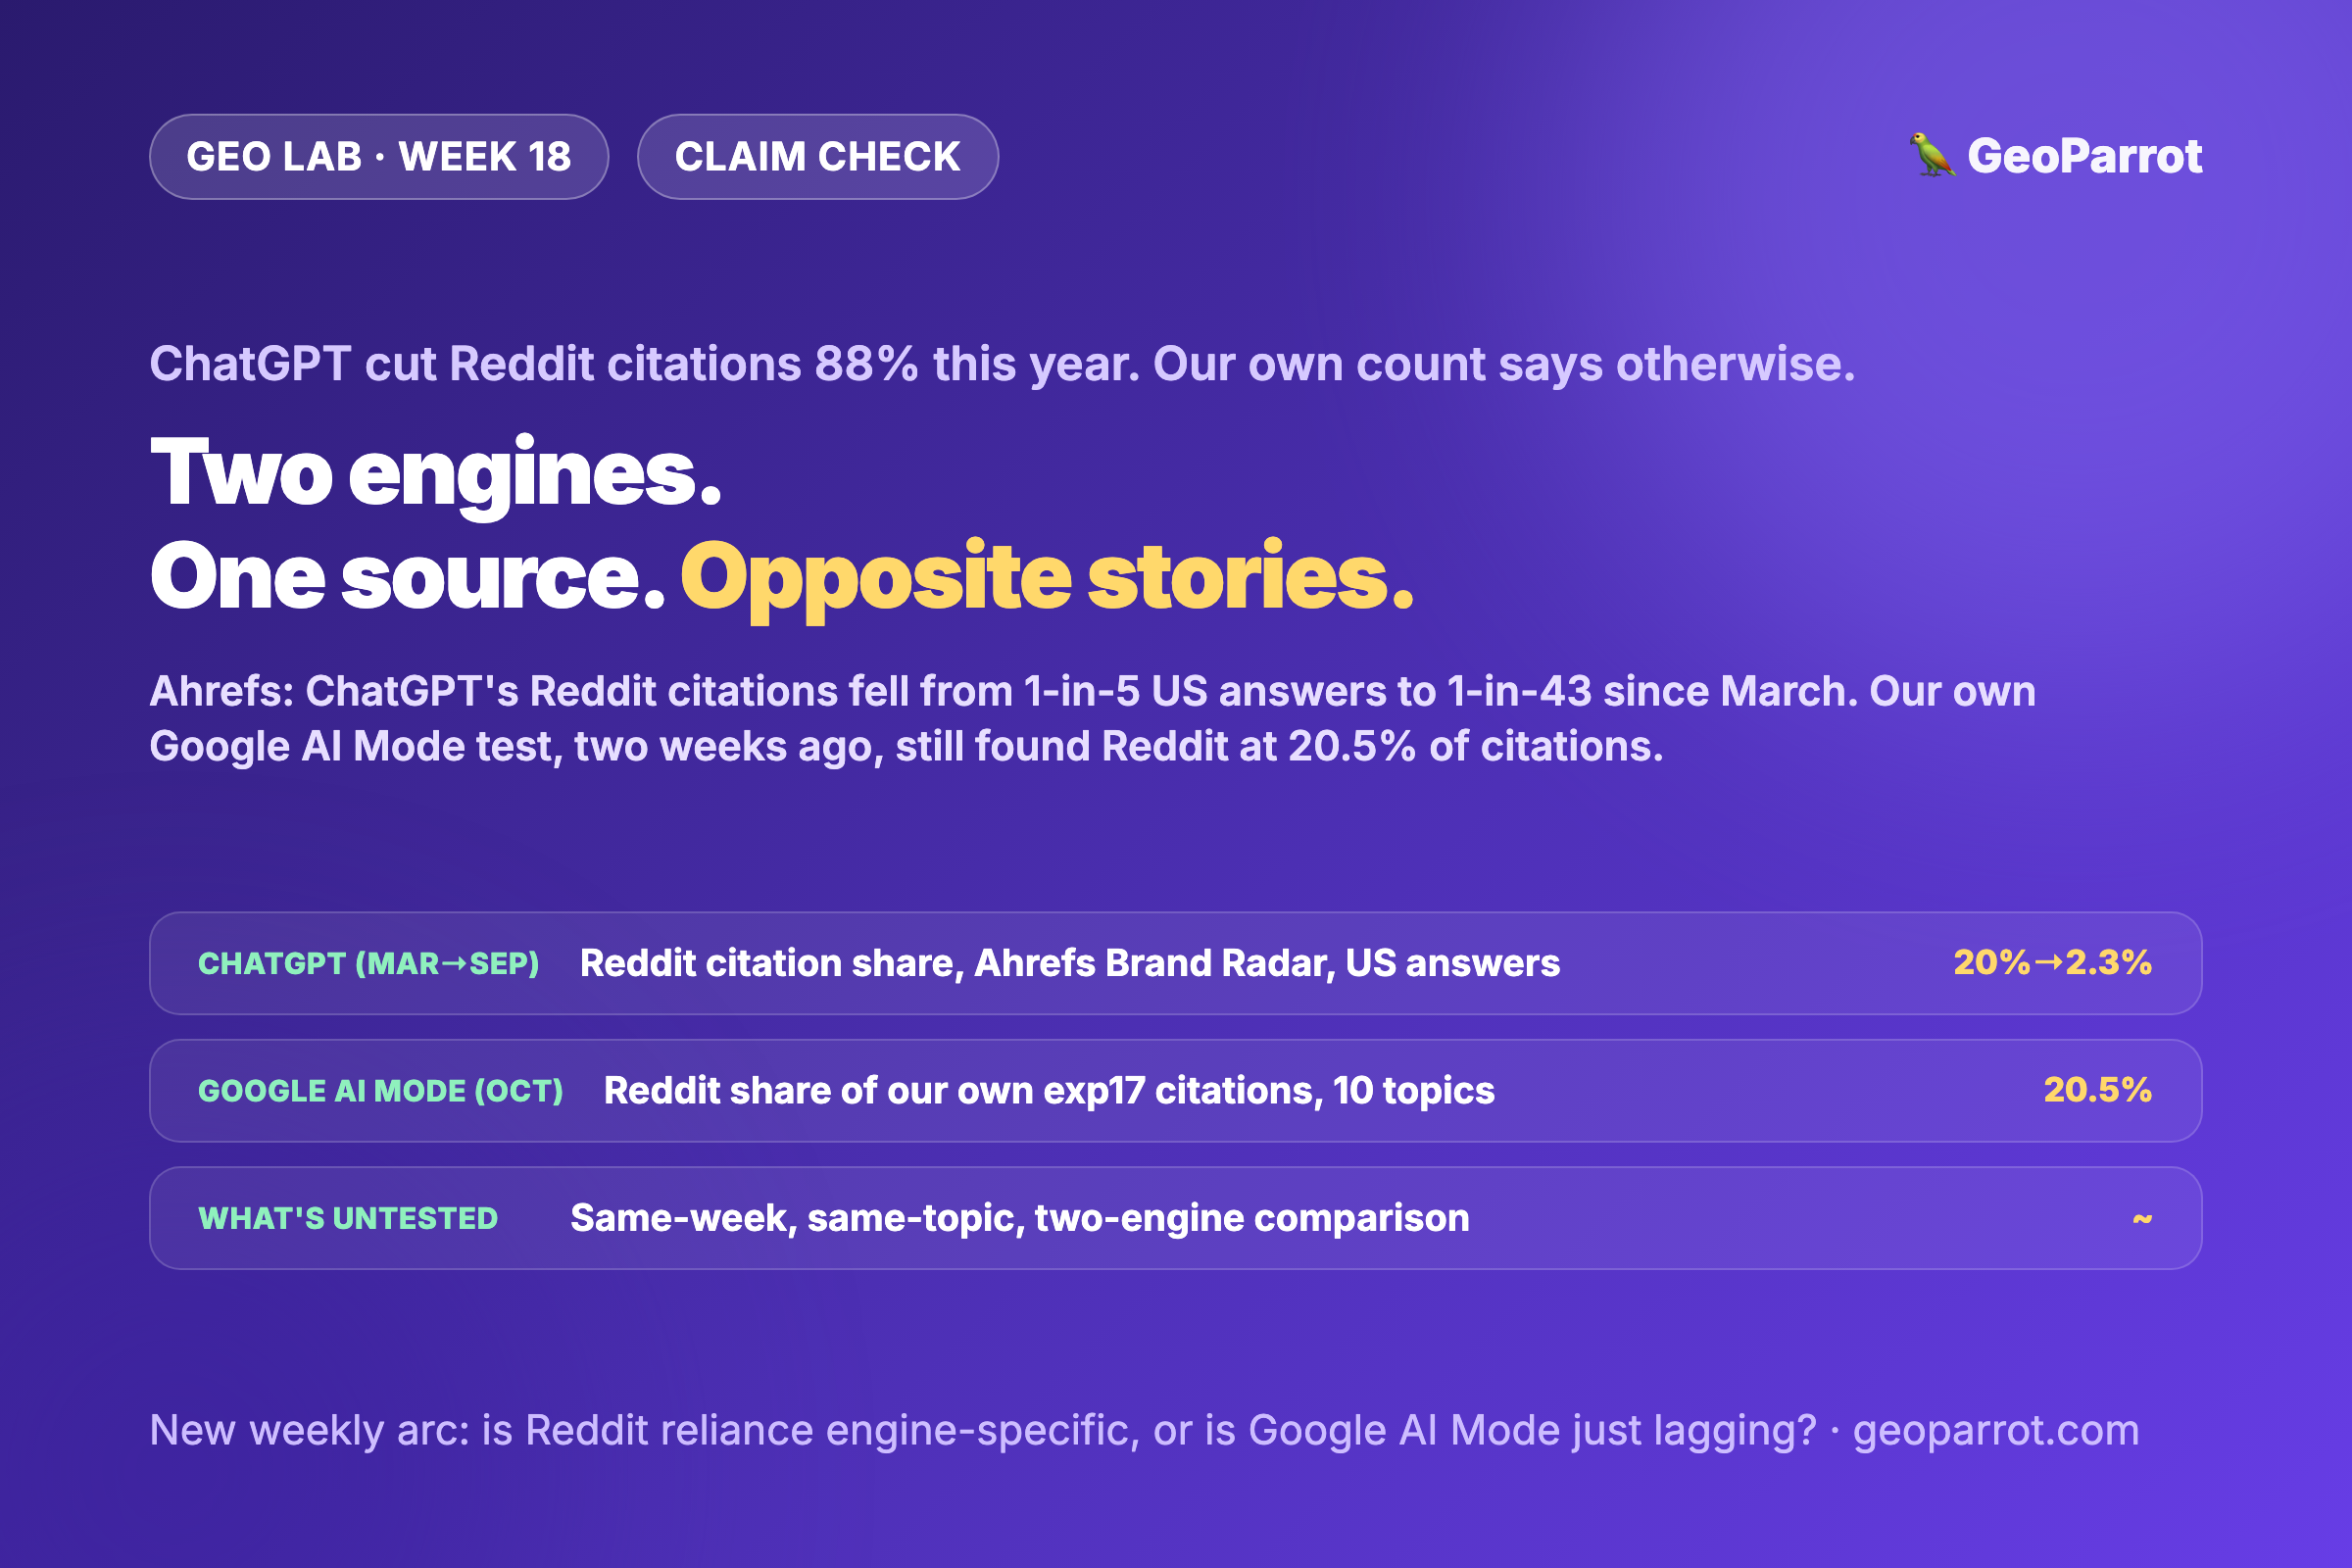
Quick answer: Monday we laid 20.5% (our own Google AI Mode exp17 figure) next to ChatGPT’s 2.3% (Ahrefs’ September reading) and found four reasons the two numbers can’t be compared as stated — different engine, different unit, different scale, no trend data on our side. This week closes those gaps two ways. First, a fresh same-day collection: the identical 10 topics from exp17, run on both ChatGPT (web search) and Google AI Mode today, with Reddit’s share computed the same way (share of actual citations) for both engines — the apples-to-apples comparison neither Monday’s post nor the original sources had. Second, a locked, mechanical rule for re-testing last week’s hygiene-score reversal (cited pages scored lower hygiene than non-cited ones) with Reddit and brand/institutional domains removed — the confound Friday’s verdict flagged but didn’t test. Five predictions, numbered and falsifiable, locked below before either number exists.
Experiment design — published October 20, 2026, in the GEO Lab. This is a pre-registration: topics, rules, and predictions go out now; we collect and score later this week. Monday’s post opened this week’s arc by checking whether ChatGPT’s reported 88% Reddit-citation collapse and our own 20.5% are actually in tension, or just measuring different things. Today we build the two tests that can tell us which.
What exactly are we testing this week?
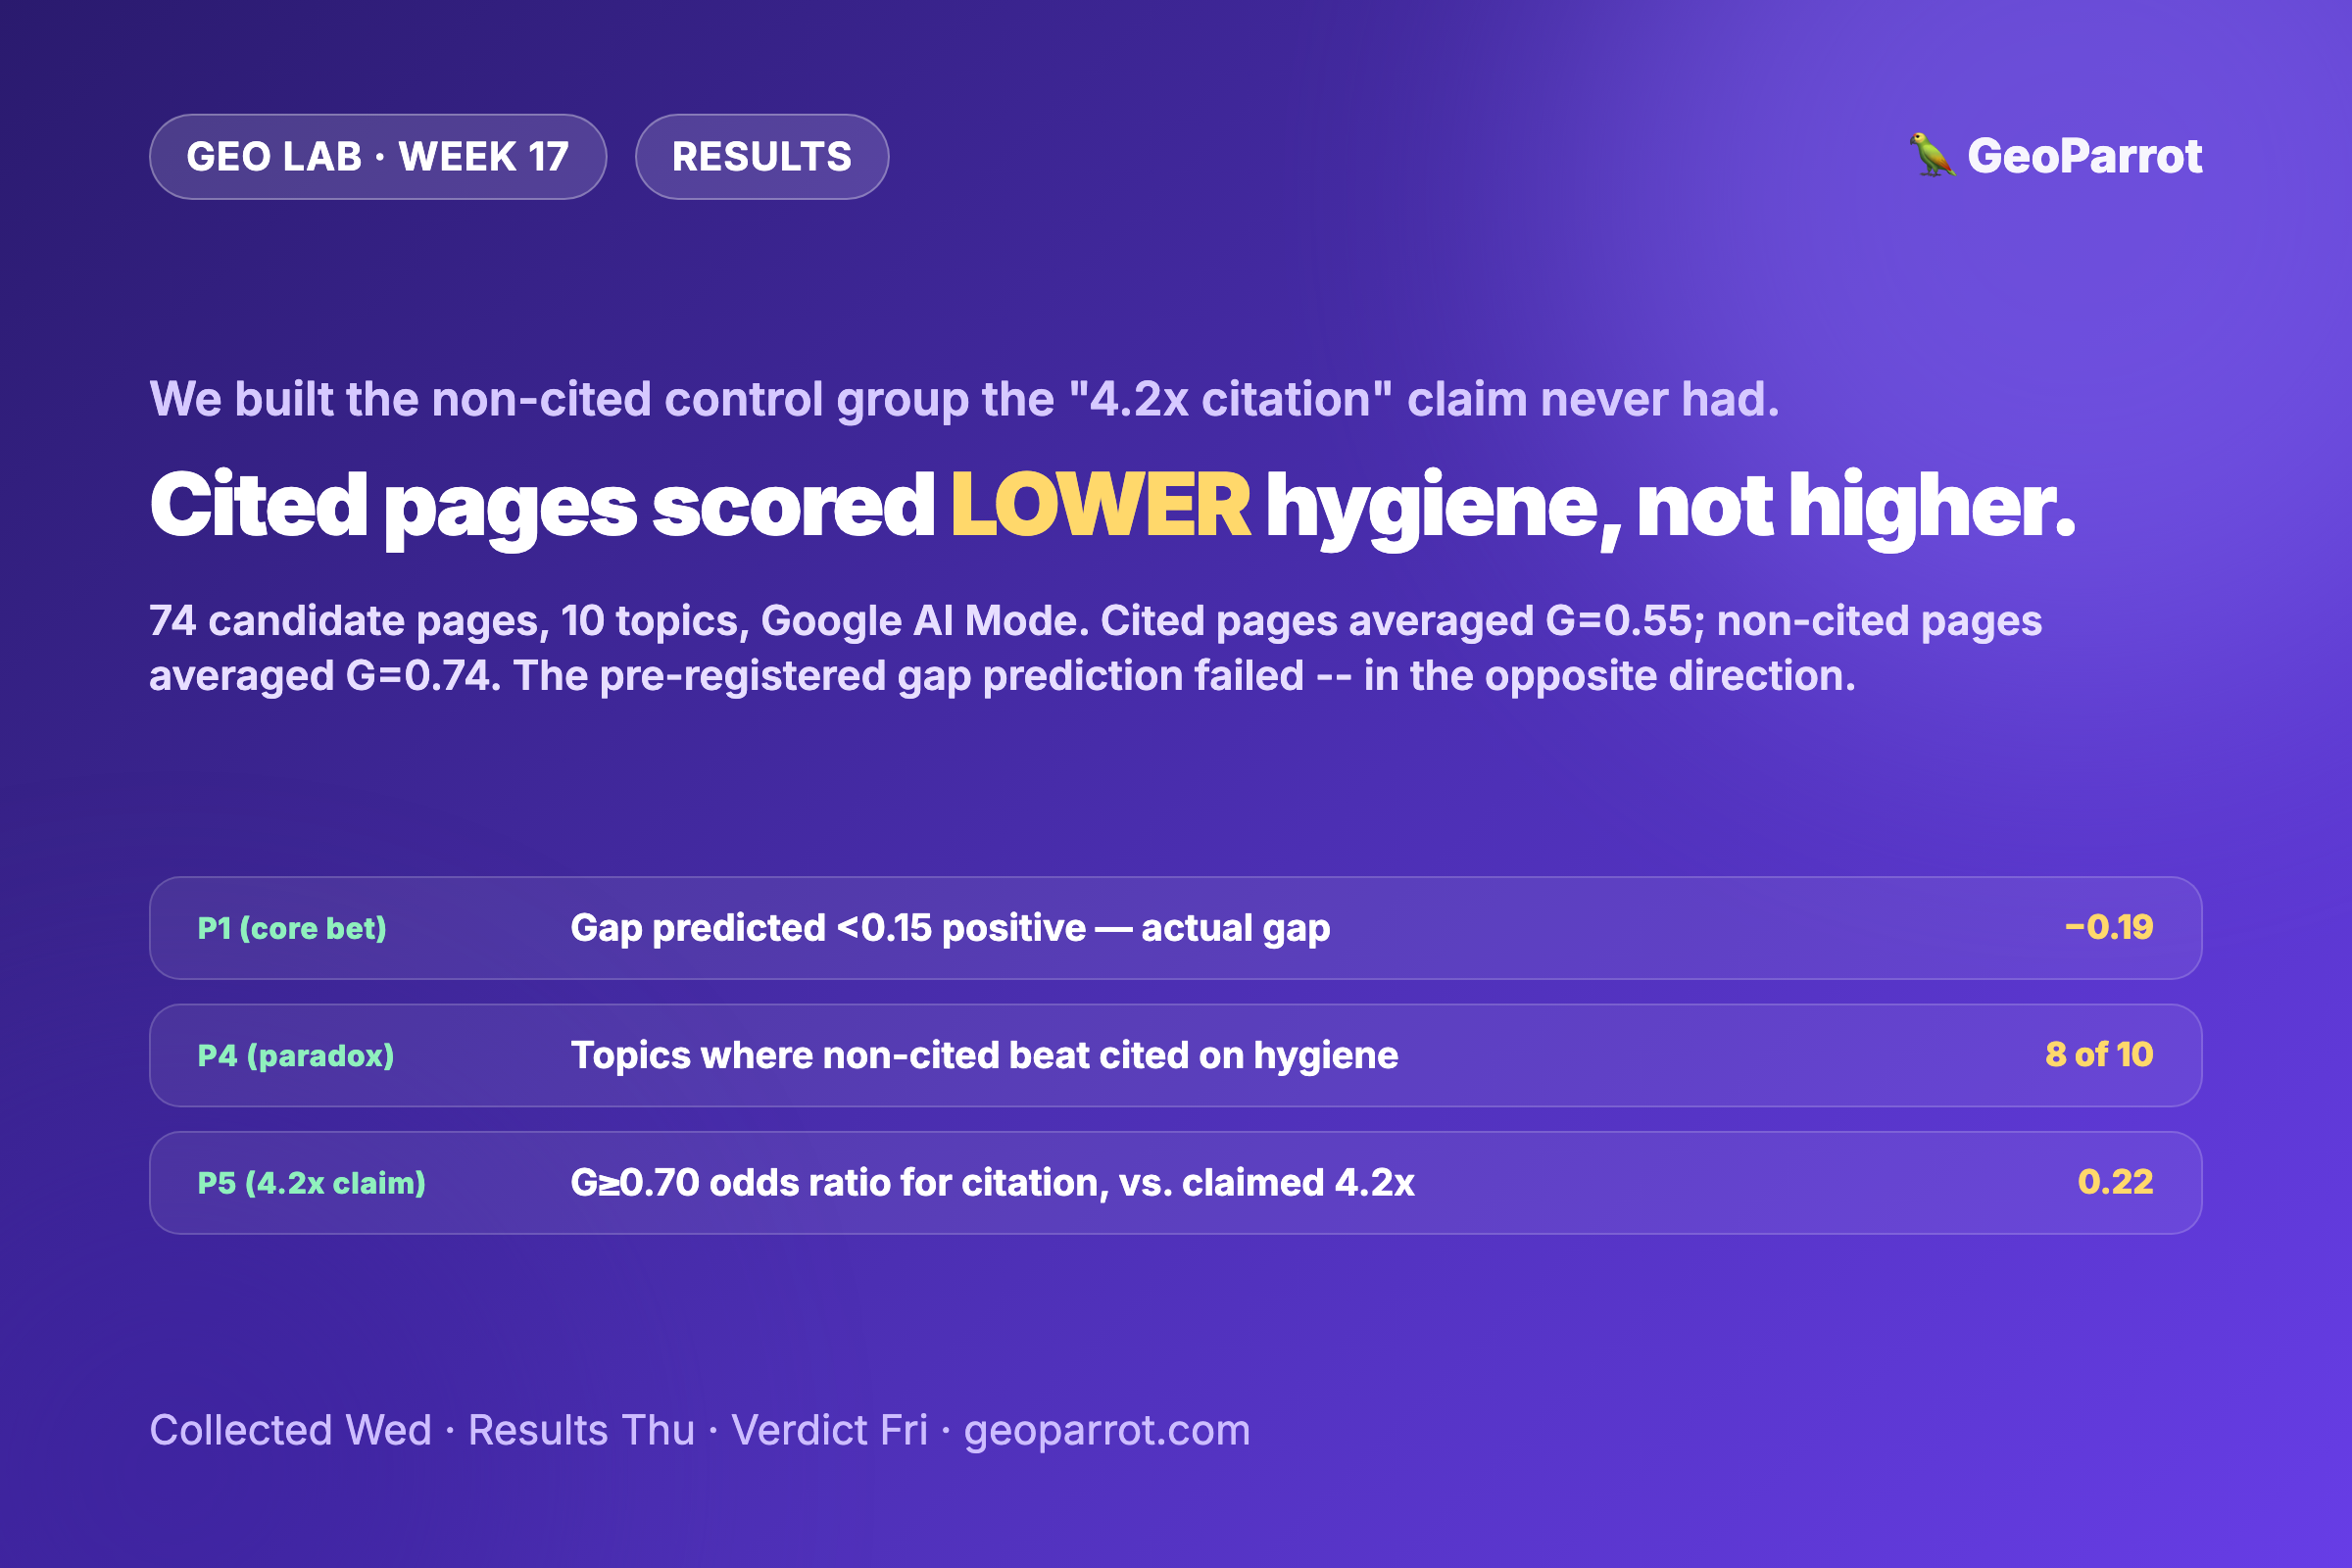
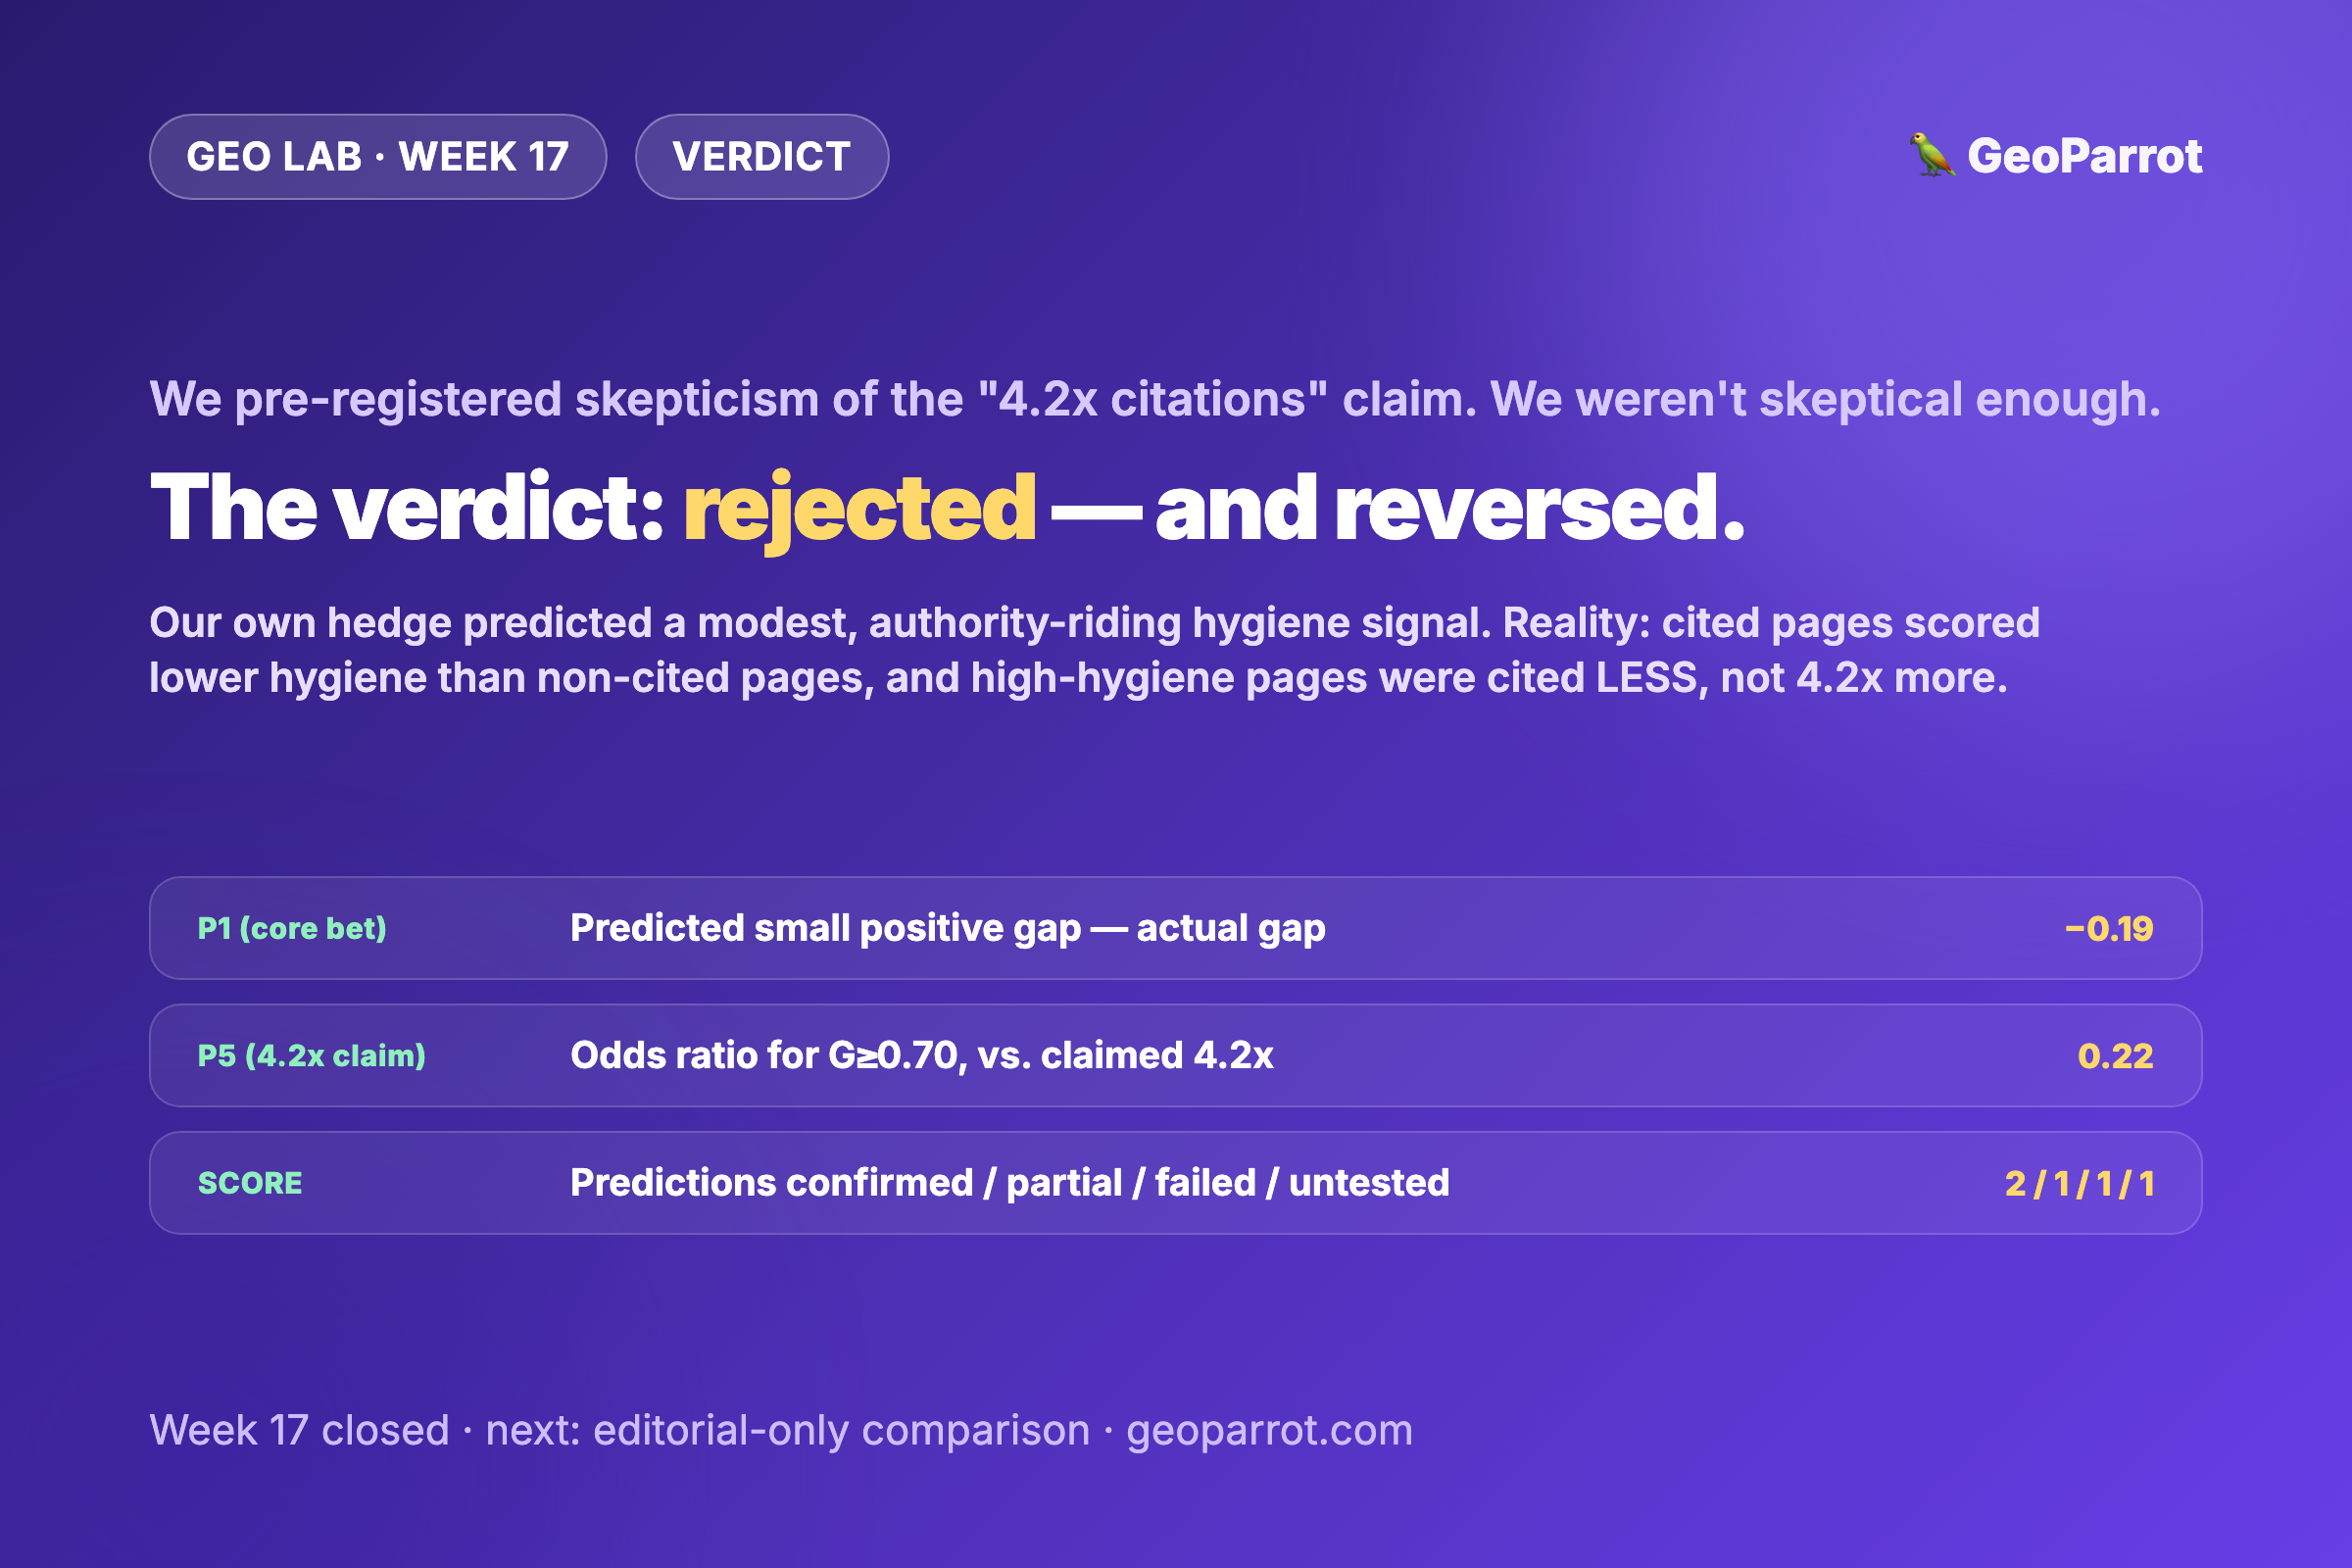
Two separate but related questions, run in parallel. Question one: when ChatGPT and Google AI Mode are measured on the identical topics, the identical day, with the identical definition of “share,” does Google AI Mode actually lean on Reddit more than ChatGPT does right now — or does the gap shrink once the comparison stops mixing timeframes and denominators? Question two: last week we found that pages Google AI Mode cited scored lower average hygiene (G=0.55) than pages sitting in the same candidate pool that weren’t cited (G=0.74) — a result so far from the industry’s “higher quality, more citations” claim that Friday’s verdict flagged Reddit and authority-tier brands as the likely cause, without testing it. This week we strip both out of the existing exp17 data using a rule locked today, and see what’s left.
Thread one: the same-day, two-engine collection — what gets measured?
We reuse the exact 10 queries from exp17 — six product-intent, four informational/how-to — so this week’s sample is directly comparable to our own two-week-old data, not just to Ahrefs’:
| # | Topic | Intent | Query |
|---|---|---|---|
| Q1 | Project management software | Product | “best project management software for remote teams” |
| Q2 | Robot vacuum | Product | “best robot vacuum for pet hair” |
| Q3 | CRM | Product | “best crm for small business” |
| Q4 | Noise-cancelling headphones | Product | “best noise cancelling headphones for travel” |
| Q5 | Budgeting app | Product | “best budgeting app for couples” |
| Q6 | Password manager | Product | “best password manager for families” |
| Q7 | Intermittent fasting | Informational | “how does intermittent fasting affect metabolism” |
| Q8 | Apartment rent negotiation | How-to | “how to negotiate a lower apartment rent” |
| Q9 | Inflation causes | Informational | “what causes inflation to rise” |
| Q10 | Marathon training | How-to | “how to train for a first marathon” |
For each topic we run ChatGPT (web search) and Google AI Mode, logged out, single snapshot, and capture every cited source URL — not a top-10 organic pool this time, since this thread only needs the citation set itself. Reddit share, for both engines, is defined identically: (citations where the registrable domain is reddit.com) ÷ (total citations across all 10 topics for that engine). That single, shared definition is the fix for the second confound Monday flagged — Ahrefs measures Reddit’s share of all answers (including ones that cite nothing from Reddit), we measure share of citations that happened. Using the same denominator for both engines this week at least makes the two engines comparable to each other, even though the result still won’t be directly comparable to Ahrefs’ own millions-of-answers number.
Thread two: re-testing the hygiene reversal — what’s the locked exclusion rule?
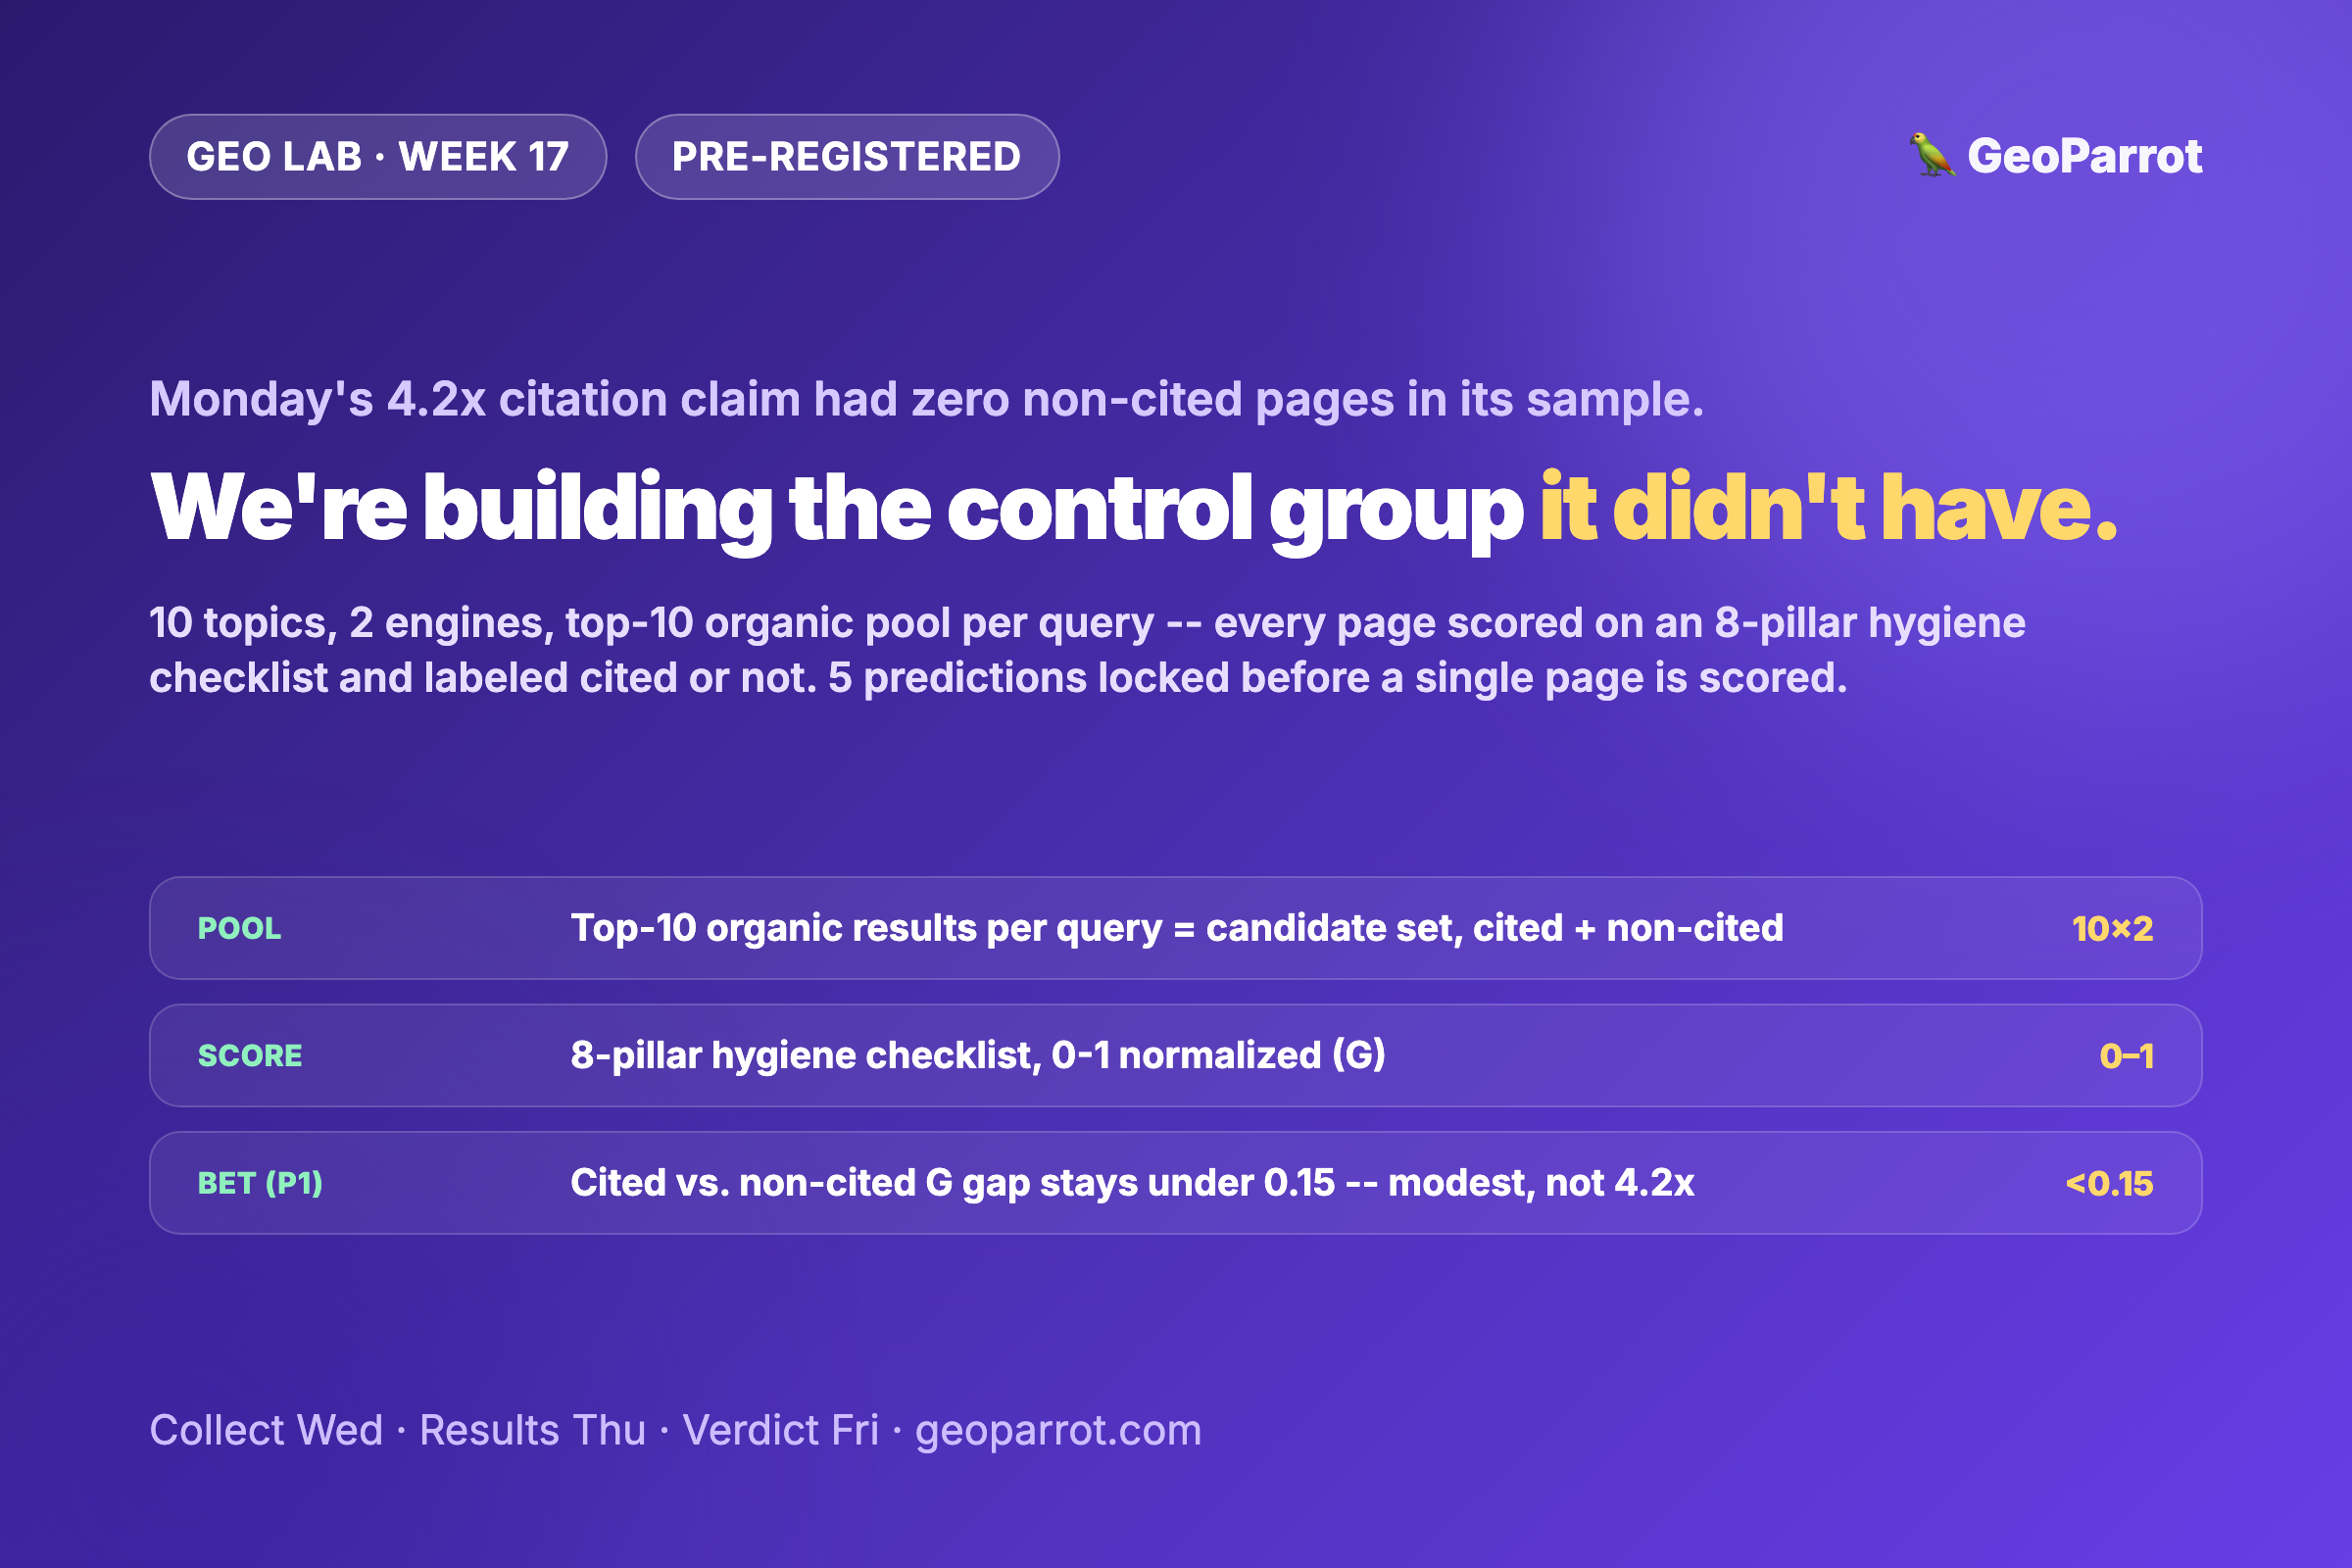
No new collection here — we reuse exp17’s existing 74-page candidate pool (10 topics, Google AI Mode, already scored on our 8-pillar hygiene checklist) and apply one rule, locked today so it can’t be tuned after we see the number:
- Reddit — any reddit.com URL. 8 of the pool’s 39 citations.
- Vendor self-citation — a domain owned by the company whose own product is the literal subject of a Product-intent query (a CRM vendor’s homepage showing up for “best CRM,” a password manager’s own site for “best password manager”). This is the pattern Monday’s Ahrefs data frames as ChatGPT’s broader shift toward “
site:searches aimed at an official brand domain” — the same mechanism, tested on Google AI Mode’s citations instead. - Institutional domains — .gov, .edu, or a regulated financial/membership institution (a bank, credit union, federal reserve branch, or chamber of commerce). These carry an authority signal that has nothing to do with content hygiene, the same logic as the vendor-domain exclusion above.
Applying that rule mechanically to the existing 74-row pool removes 22 rows (9 Reddit, 5 vendor, 8 institutional), leaving 52 rows: 18 cited, 34 non-cited. That’s the “pure editorial” subset — pages that are neither forum threads, nor a brand talking about itself, nor an institution with credibility ChatGPT and Google AI Mode both already over-trust. We’re publishing the post-exclusion sample size today, before computing the actual G-gap on it, specifically so Thursday’s number can’t be read as cherry-picked after the fact.
What five predictions are we locking before collection?
Numbered, falsifiable, split across both threads. If the data contradicts one, Thursday’s post says so in plain language.
- P1 — The same-day engine gap is real and large (load-bearing). On the identical 10-topic sample, collected the same day, Google AI Mode’s Reddit citation share is at least 3x ChatGPT’s Reddit citation share. This is deliberately a lower bar than the roughly 9x gap implied by naively comparing 20.5% to 2.3% — if even a 3x gap doesn’t hold once timeframe and denominator are controlled, the “engines have diverged” story was mostly a measurement artifact.
- P2 — ChatGPT’s fresh number lands near Ahrefs’ reading, not its own old baseline. ChatGPT’s Reddit share on our 10 fresh topics comes in at or below 8% — consistent with Ahrefs’ ~2.3% September figure, not a reversion toward the ~20% ChatGPT itself showed back in March.
- P3 — Google AI Mode’s number replicates, it isn’t a one-off. Google AI Mode’s Reddit share on the same topics, two weeks later, stays at or above 15% — close to exp17’s 20.5%, showing this is a stable pattern for that engine rather than noise from one week’s topic mix.
- P4 — Stripping Reddit and brand/institutional domains meaningfully narrows last week’s hygiene gap. On the 52-row “pure editorial” subset (18 cited, 34 non-cited), the cited-vs-non-cited mean G gap narrows by at least half from the original full-sample −0.19, moving to ≥−0.095.
- P5 — Even narrowed, the gap does not flip positive. On that same 52-row subset, mean G for cited pages still does not exceed mean G for non-cited pages — hygiene continues to fail as a citation predictor even in the cleanest lane we can build for it, extending last week’s skepticism rather than reversing it.
Together these describe one shape: the cross-engine Reddit gap is mostly real once measured fairly (P1–P3), and the hygiene-score reversal from last week survives having its two biggest confounds removed, even if the removal softens the headline number (P4–P5). If P1 fails and the gap collapses once timeframe and denominator are controlled, Monday’s “two engines, opposite stories” framing was mostly an artifact of a bad comparison, not a real split. If P5 fails and the gap flips positive on pure editorial content, that’s real, qualified good news for the content-hygiene checklist this whole arc has been testing against itself.
What could make this experiment misleading — and how do we stay honest?
Four limits, named in advance. One: our “share of citations” still isn’t Ahrefs’ “share of all answers.” Making both engines use the same denominator this week fixes the cross-engine comparison, but the resulting numbers still won’t be directly stackable against Ahrefs’ millions-of-answers tracking — that comparison stays qualitative, not a shared statistic. Two: 10 topics is still a small sample for a share-of-citations metric, the same limitation exp17 carried; a single Reddit-heavy or Reddit-free topic can move either engine’s number by several points. Three: the vendor/institutional exclusion rule involves some judgment — “is this domain’s own product the subject of the query” is mostly unambiguous for our 10 topics (a CRM vendor’s site for a CRM query), but we’re locking the specific domain list today precisely so there’s no room to redraw the line after seeing the G-gap. Four: one logged-out snapshot per engine, the standing caveat on every GEO Lab test — citation sets drift and vary, and two snapshots two weeks apart describe a trend direction, not a verified trajectory.
We’re pre-registering this the same way we did last week’s control-group design and the citation-stats audit before it — predictions locked in public, before either number exists, so neither “the engines really did converge” nor “hygiene really doesn’t matter at all” can get quietly redefined after the fact. Wednesday we collect both threads; Thursday we publish the numbers; Friday we score all five predictions.
Frequently asked questions
What is this week’s experiment actually testing?
Two things in parallel: whether ChatGPT and Google AI Mode really diverge on Reddit citation share when measured the same way, the same day, on the same 10 topics; and whether last week’s finding that hygiene score predicts citation backwards survives once Reddit and brand/institutional domains are removed from the comparison.
Why reuse exp17’s exact 10 topics instead of picking new ones?
So the fresh collection is comparable to our own two-week-old data, not just to Ahrefs’. A new topic set would introduce a third variable (different queries) on top of the two we’re already trying to isolate (different engine, different week).
What counts as a “vendor self-citation” or “institutional domain” for the exclusion rule?
Vendor self-citation: a domain owned by the company whose product is the literal subject of a Product-intent query — for example, a CRM vendor’s own homepage cited for “best crm for small business.” Institutional: .gov, .edu, or a regulated financial/membership institution such as a bank, credit union, Federal Reserve branch, or chamber of commerce. Applied to exp17’s 74-row pool, this removes 22 rows (9 Reddit, the rest vendor or institutional), leaving 52.
Why is P1 set at 3x instead of the roughly 9x implied by last week’s numbers?
Because the ~9x gap (20.5% vs. 2.3%) came from comparing different engines, different denominators, and different months — exactly the comparison Monday’s post flagged as unreliable. 3x is a deliberately conservative bar: if a real same-day, same-topic, same-denominator test can’t clear even a third of the naive gap, most of what looked like an engine split was measurement noise.
When are the results published?
We collect both threads Wednesday and publish the numbers Thursday, then a verdict Friday that scores all five predictions and closes the loop this week’s arc opened Monday. Nothing in this post changes once the data is in.
Sources
- ChatGPT’s Reddit Citations Collapsed 88% This Year. Our Own Google AI Mode Data Still Shows 21%. — Monday’s claim check that opened this week’s arc and the four comparability gaps this post’s design is built to close.
- We Built the Missing Control Group — exp17’s full 74-page per-topic data, the source of both the 20.5% Reddit figure and the 52-row re-analysis pool.
- The Verdict: A “4.2x More AI Citations” Quality-Score Claim Pointed Backwards — last week’s closing judgment that flagged Reddit and authority-tier brands as the likely cause, without testing it.
- Cited vs. Never Cited: Our Pre-Registered Test — the pre-registration-before-collection discipline this week’s design follows again.
- Do 15 domains control AI citations? — the authority-concentration data behind why vendor/institutional domains get excluded as their own category here.
- Did Reddit Block ChatGPT? and ChatGPT Just Cut YouTube Citations by 91% — earlier ChatGPT-only monthly volatility stories; this week’s question is the cross-engine, same-week comparison those two didn’t run.
- A Vendor Just Measured Cross-Engine Citation Disagreement at 27%. Our Own Count Puts It Near 99%. — an earlier case of two real numbers measuring different things, the same pattern this week’s P1–P3 are built to test cleanly instead of just flag.
- Counted vs. inferred GEO metrics — why a same-day, matched-denominator count beats stacking two differently-measured percentages.
GeoParrot is a GEO Lab: we test what AI search actually cites and recommends, then publish the method and the misses — including our own. This is a Tuesday pre-registration in a four-part weekly arc. Monday opened the question; Wednesday we collect; Thursday the data; Friday the verdict.
Leave a Reply