Author: GeoParrot Team
-
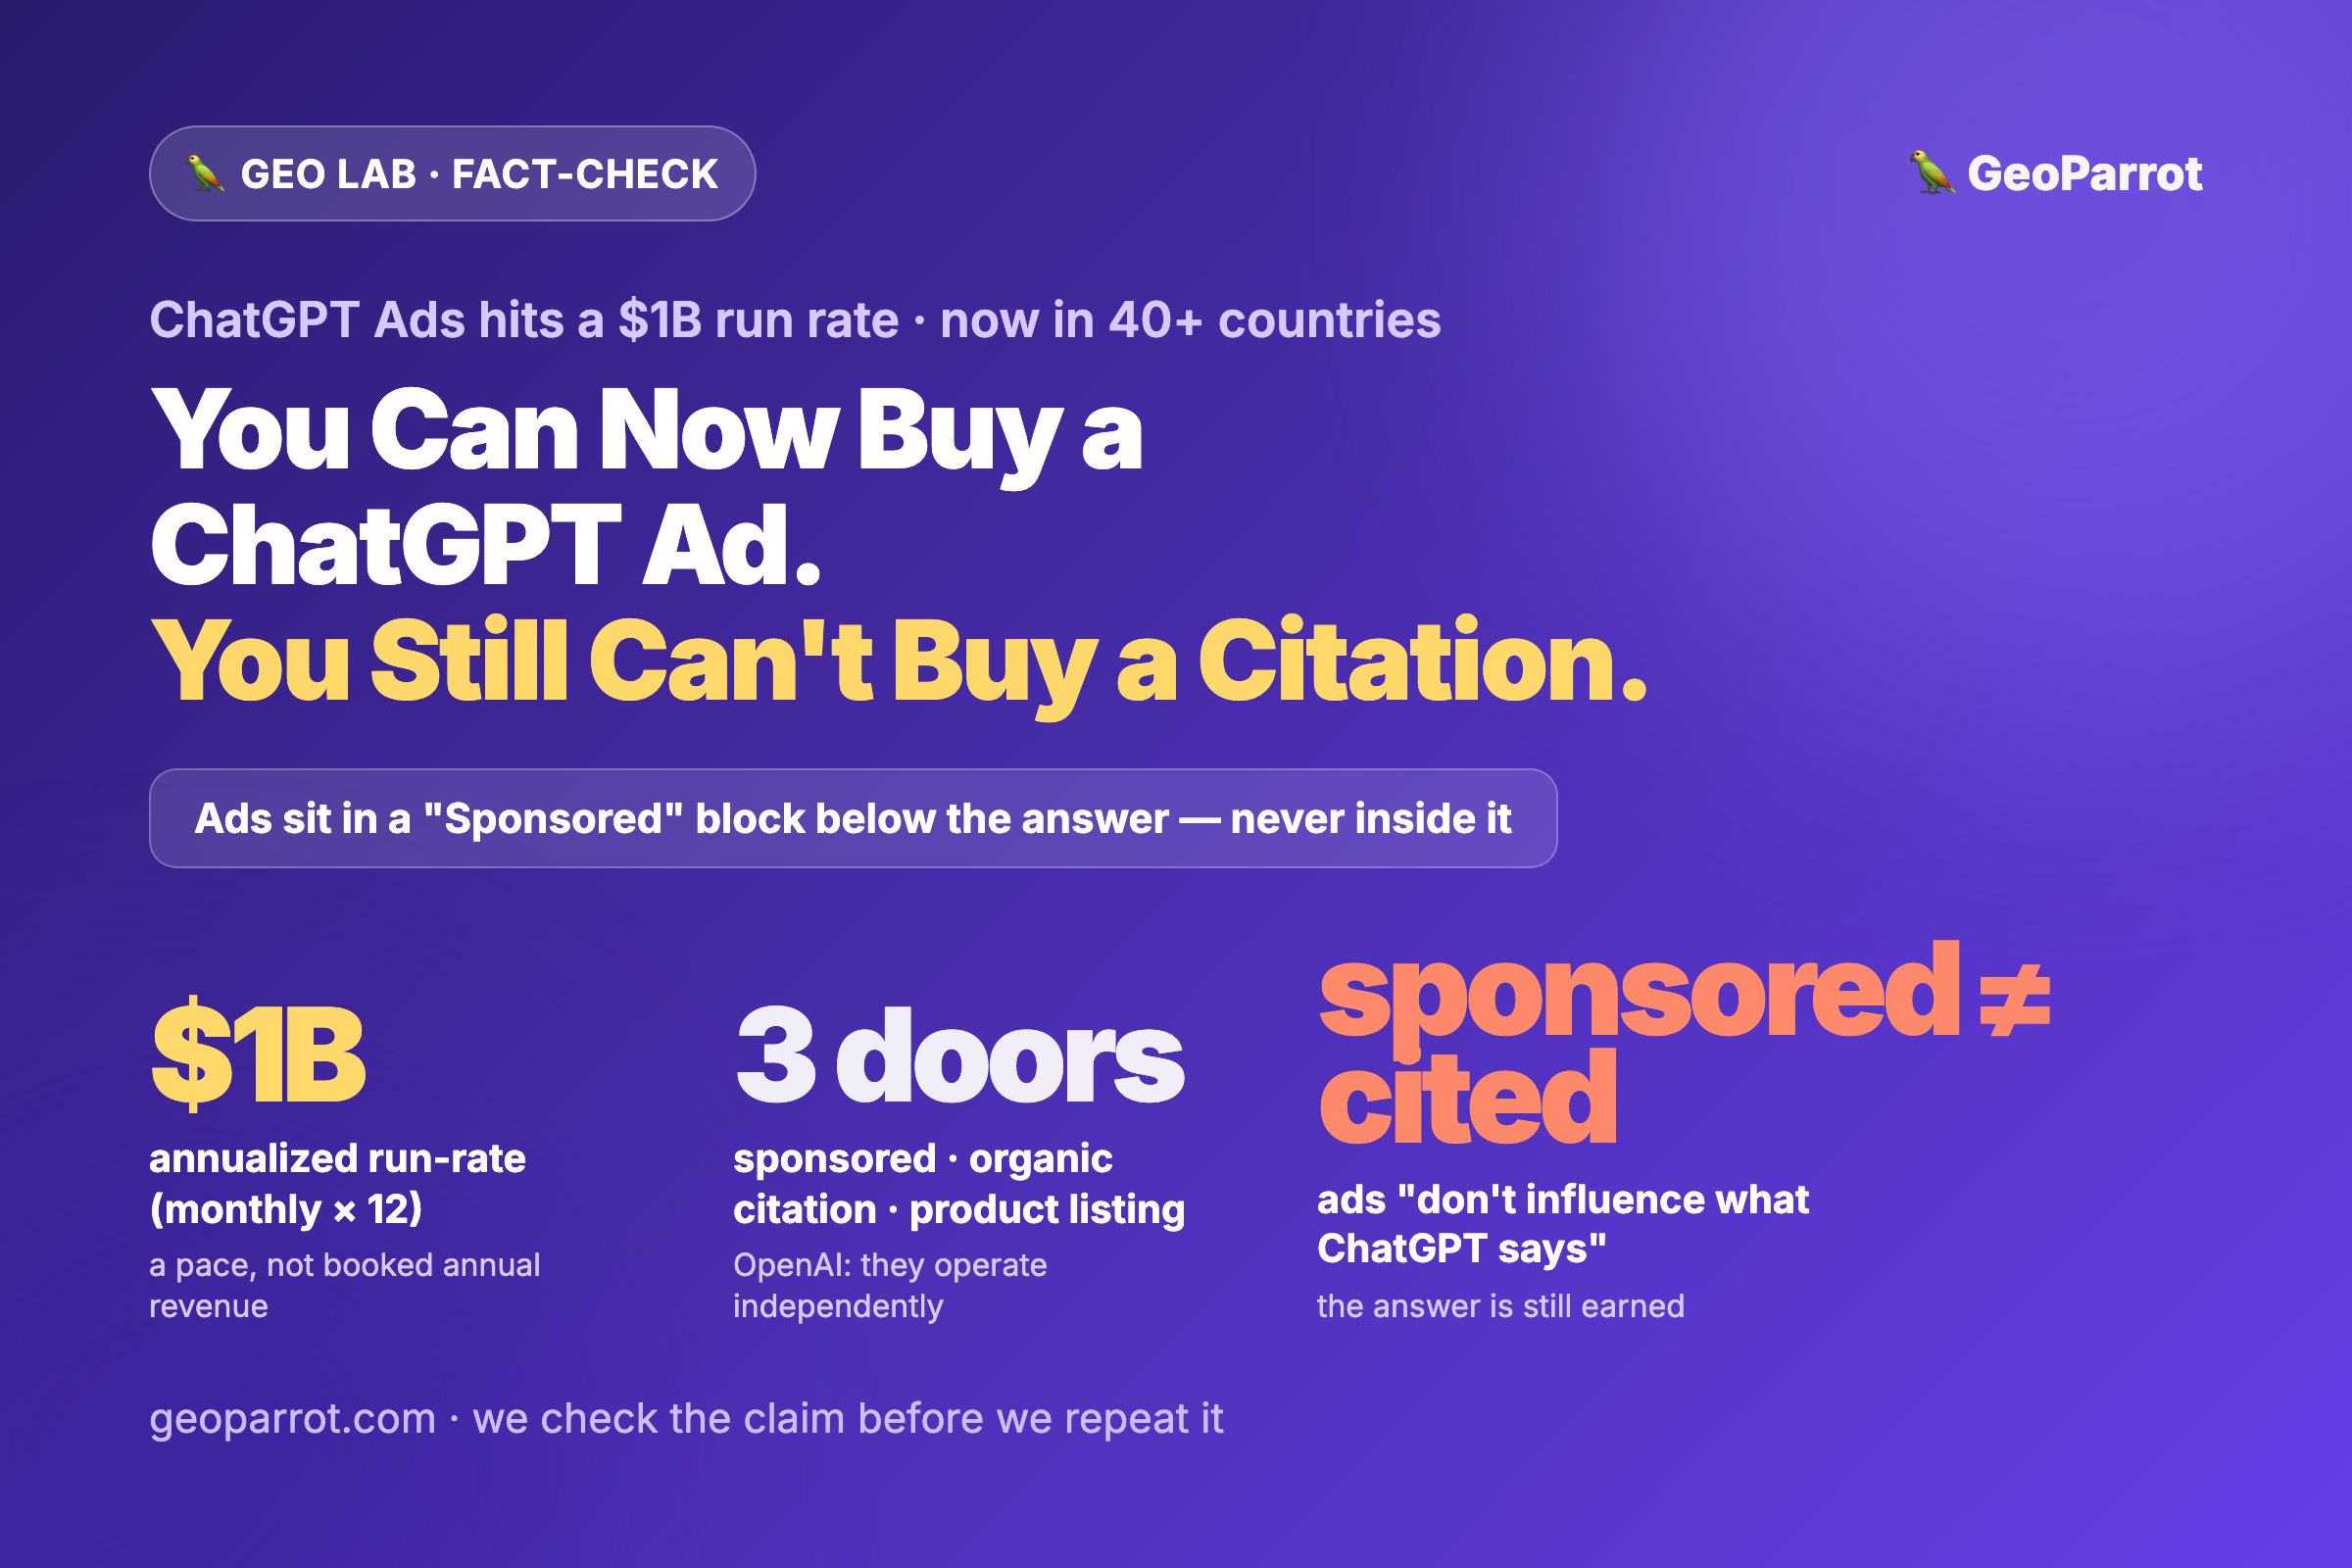
ChatGPT Ads Just Hit a $1B Run Rate — But You Still Can’t Buy a Citation
OpenAI says ChatGPT Ads has reached a $1 billion annualized run rate and is now buyable in 40+ countries. That’s a real structural shift in the biggest AI answer engine — but it doesn’t change the one thing GEO actually chases. OpenAI’s own design keeps ads in a labeled “Sponsored” block below the answer, and…
-
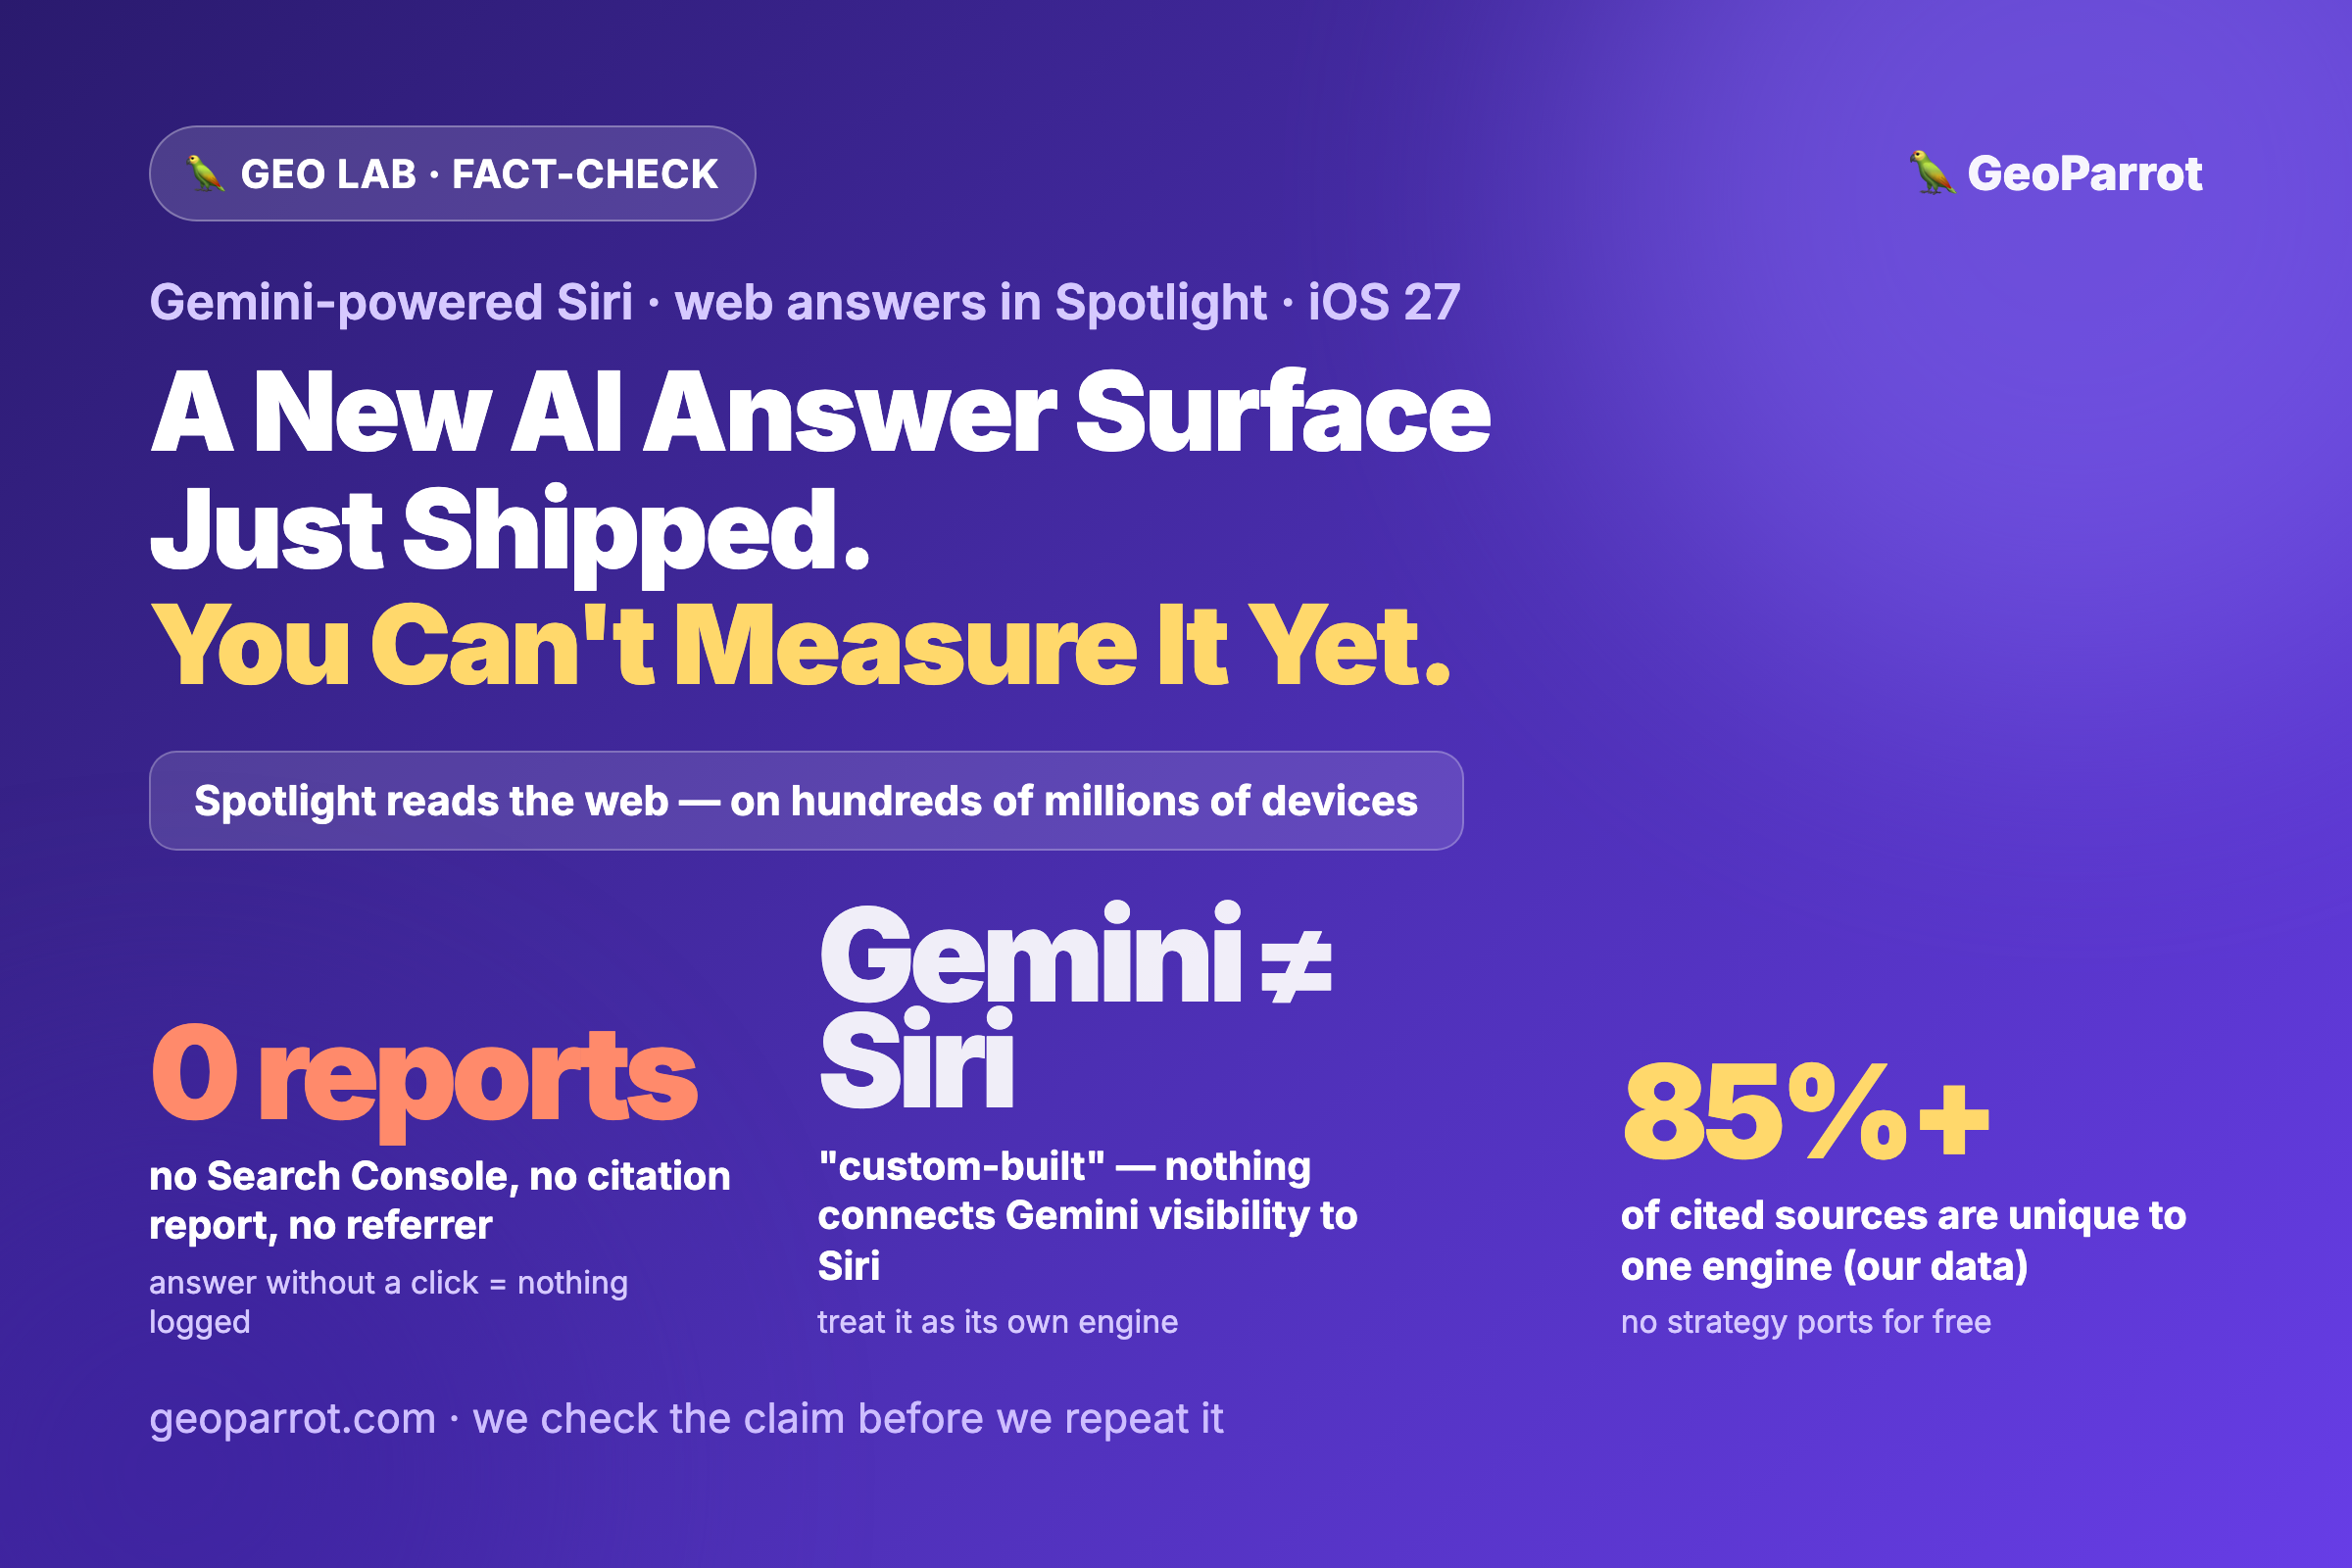
Gemini-Powered Siri Is a New AI Answer Surface — With Zero Citation Reporting
Apple’s rebuilt, Gemini-powered Siri ships with iOS 27 this month, and it reads the web to answer questions right inside Spotlight — a brand-new AI answer surface on hundreds of millions of devices. Two things make it different for GEO: Apple hasn’t shipped any measurement surface (no Search Console equivalent, no citation report, no referrer),…
-
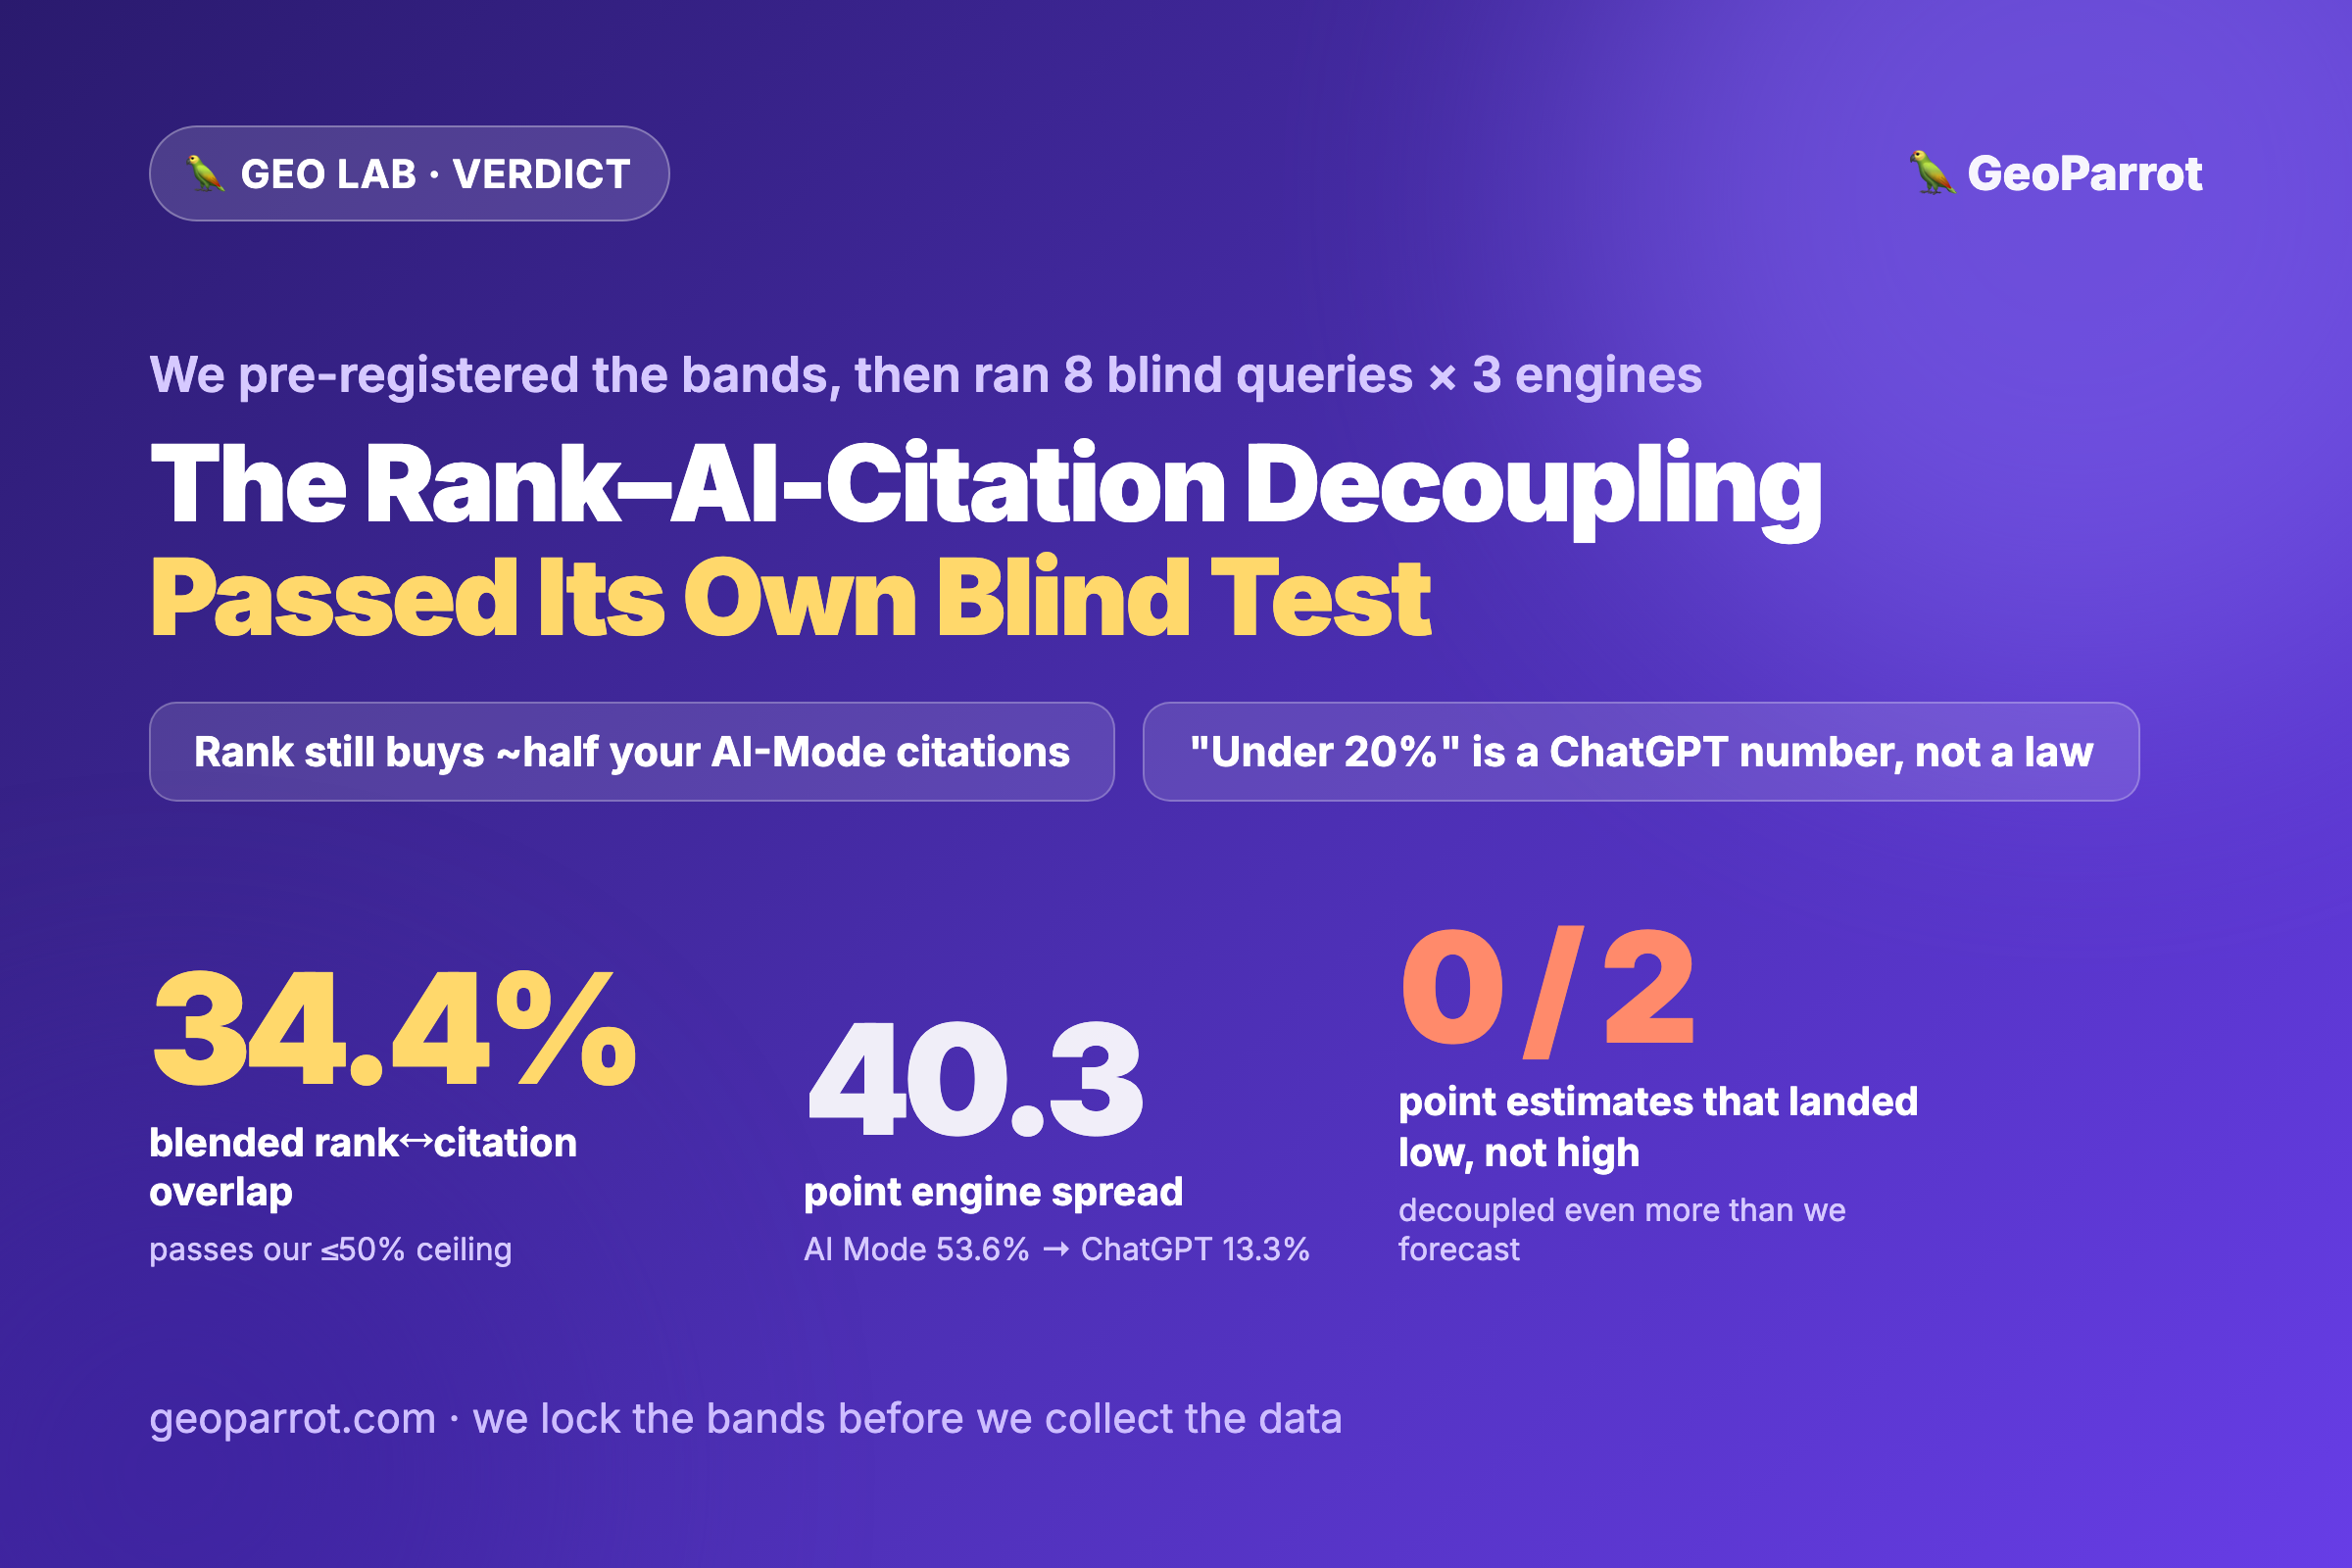
Verdict: The Rank-to-AI-Citation Decoupling Passed Our Blind Test — 34% Blended Overlap, a 40-Point Engine Spread, and Why “Under 20%” Is a ChatGPT Number, Not a Law
On Tuesday we locked five overlap bands before collecting a single query. This week we ran 8 buyer-intent “best X” searches across Google AI Mode, Perplexity, and ChatGPT and scored the citations blind against Google’s top-10 organic. The verdict: the rank-decoupled thesis passes on both load-bearing criteria — blended overlap 34.4% (ceiling was ≤50%) and…
-
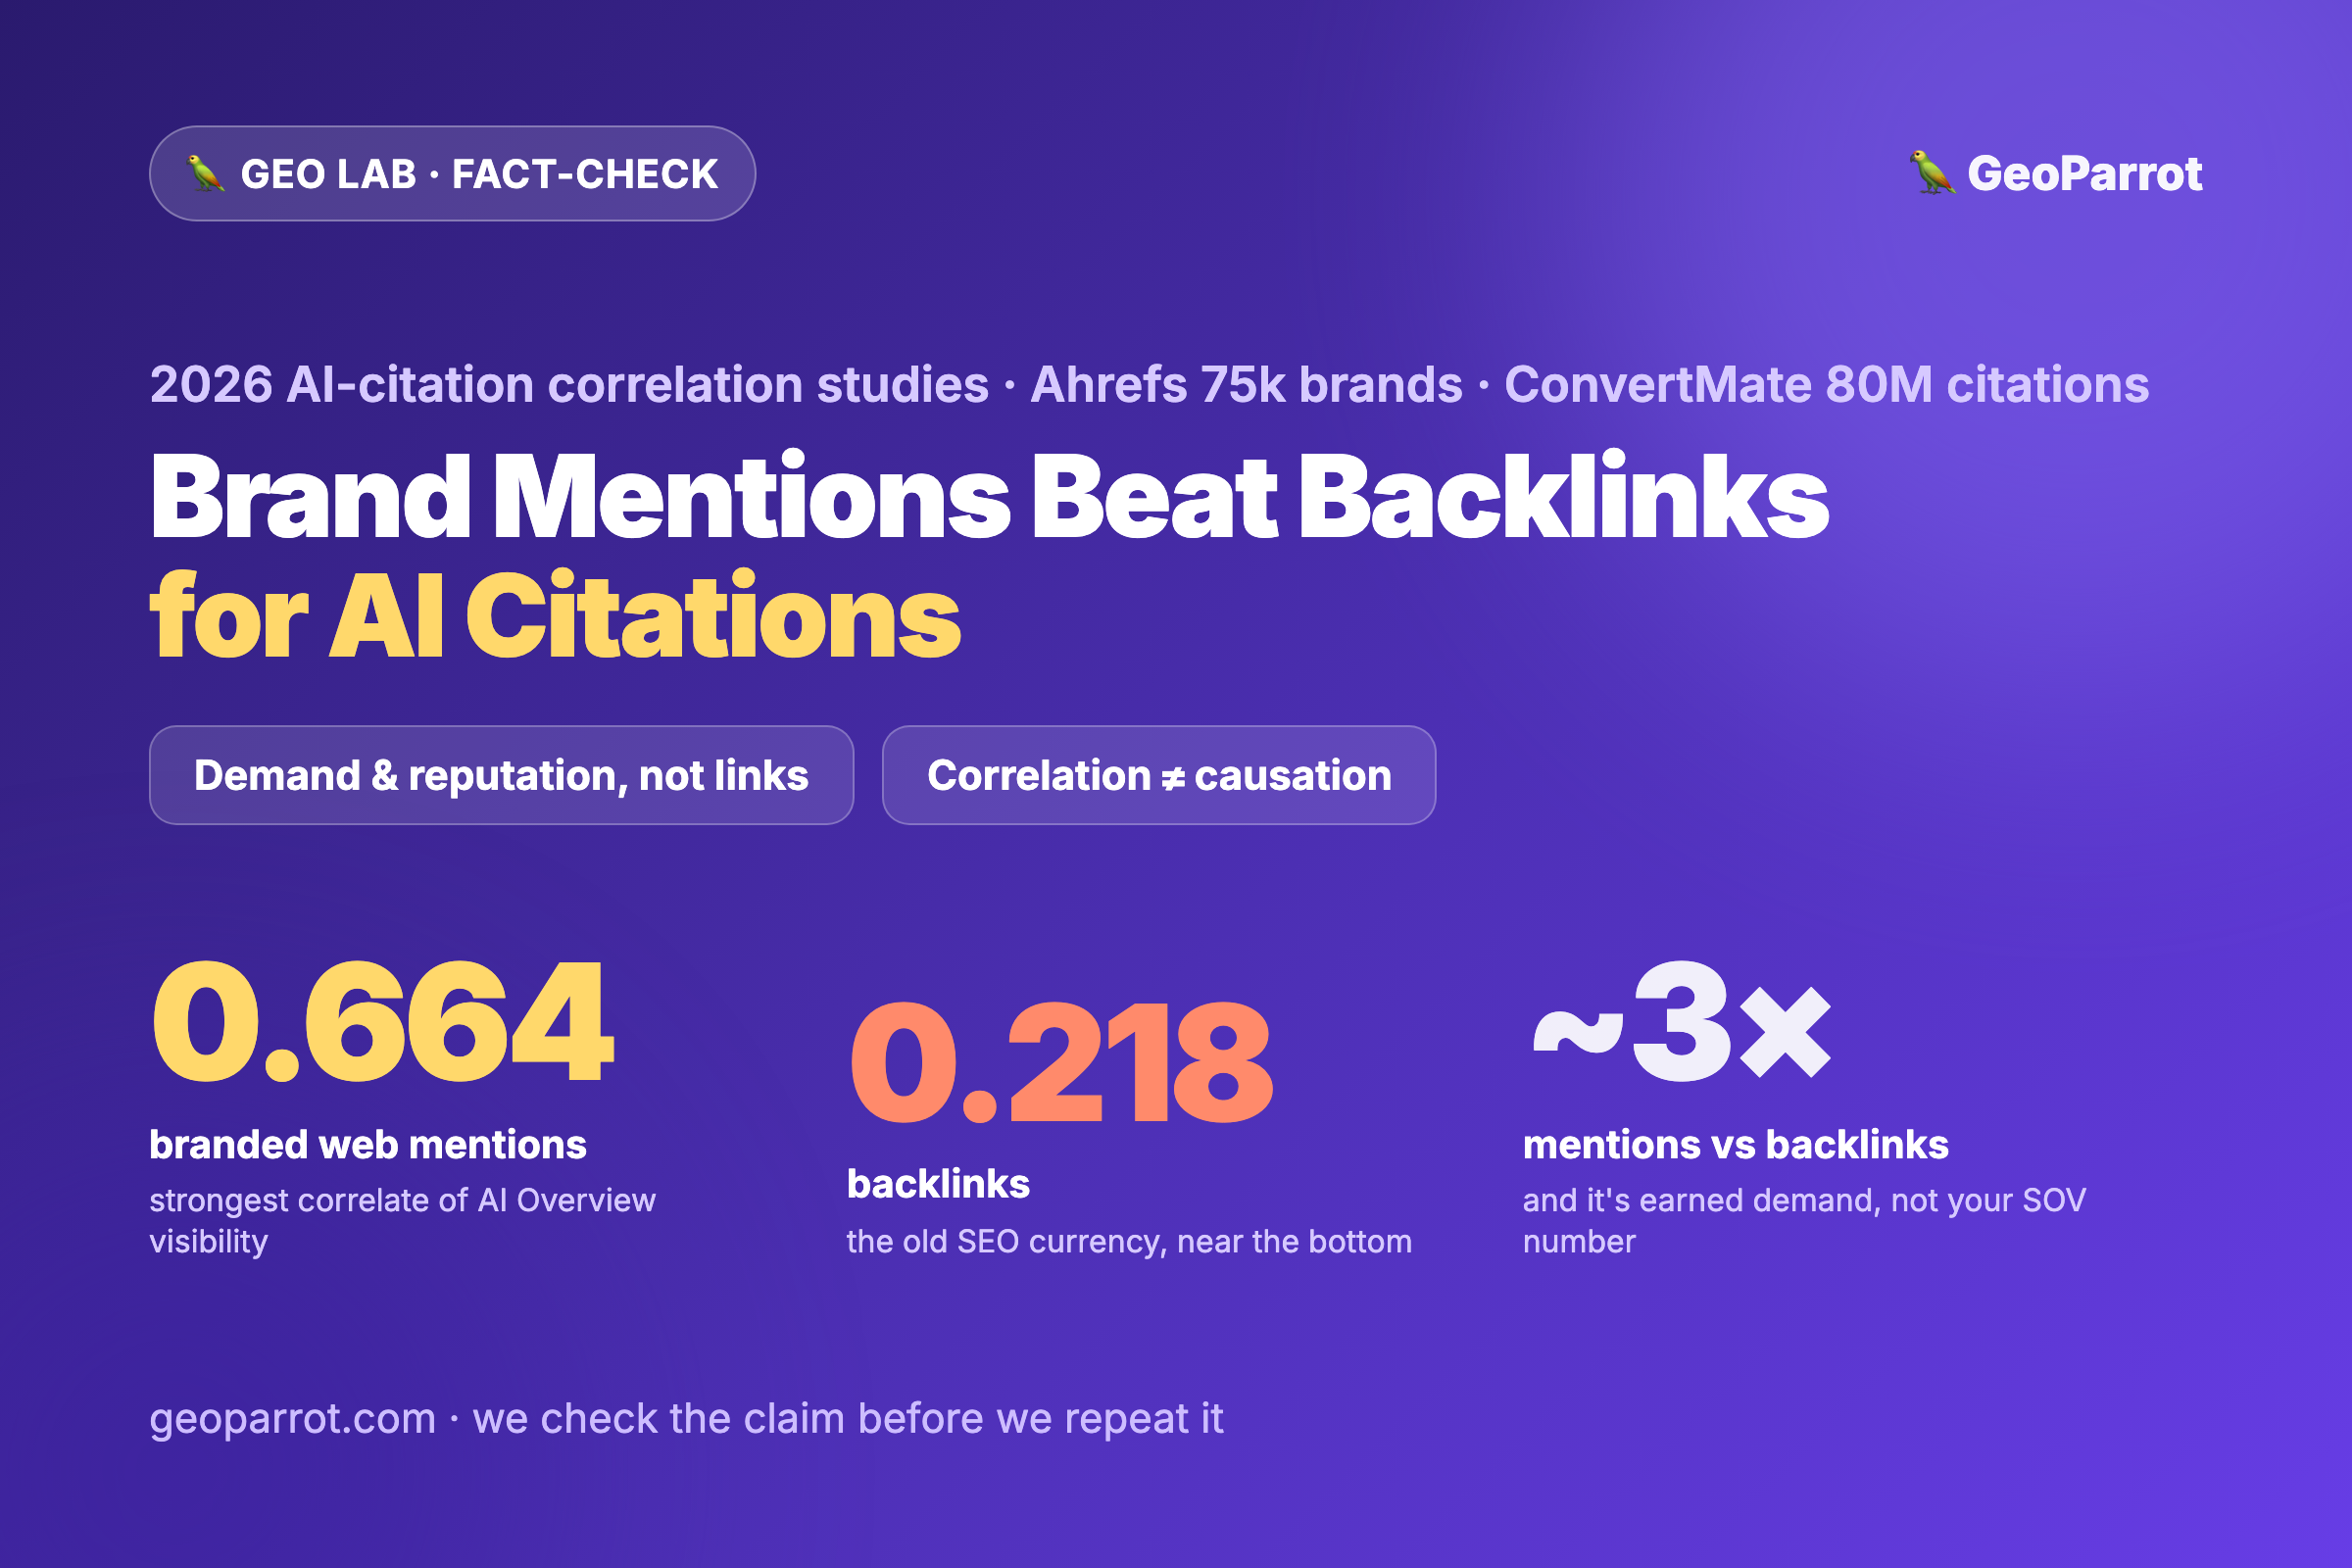
Brand Mentions Beat Backlinks for AI Citations — What the 2026 Studies Actually Show
Three large 2026 studies now agree: brand mentions and brand demand — not backlinks — are the strongest correlate of getting cited in AI answers. Ahrefs’ 75,000-brand study puts branded web mentions at r=0.664 versus 0.218 for backlinks; ConvertMate’s 80-million-citation study found branded search volume the single strongest variable. Here’s what the data really says,…
-
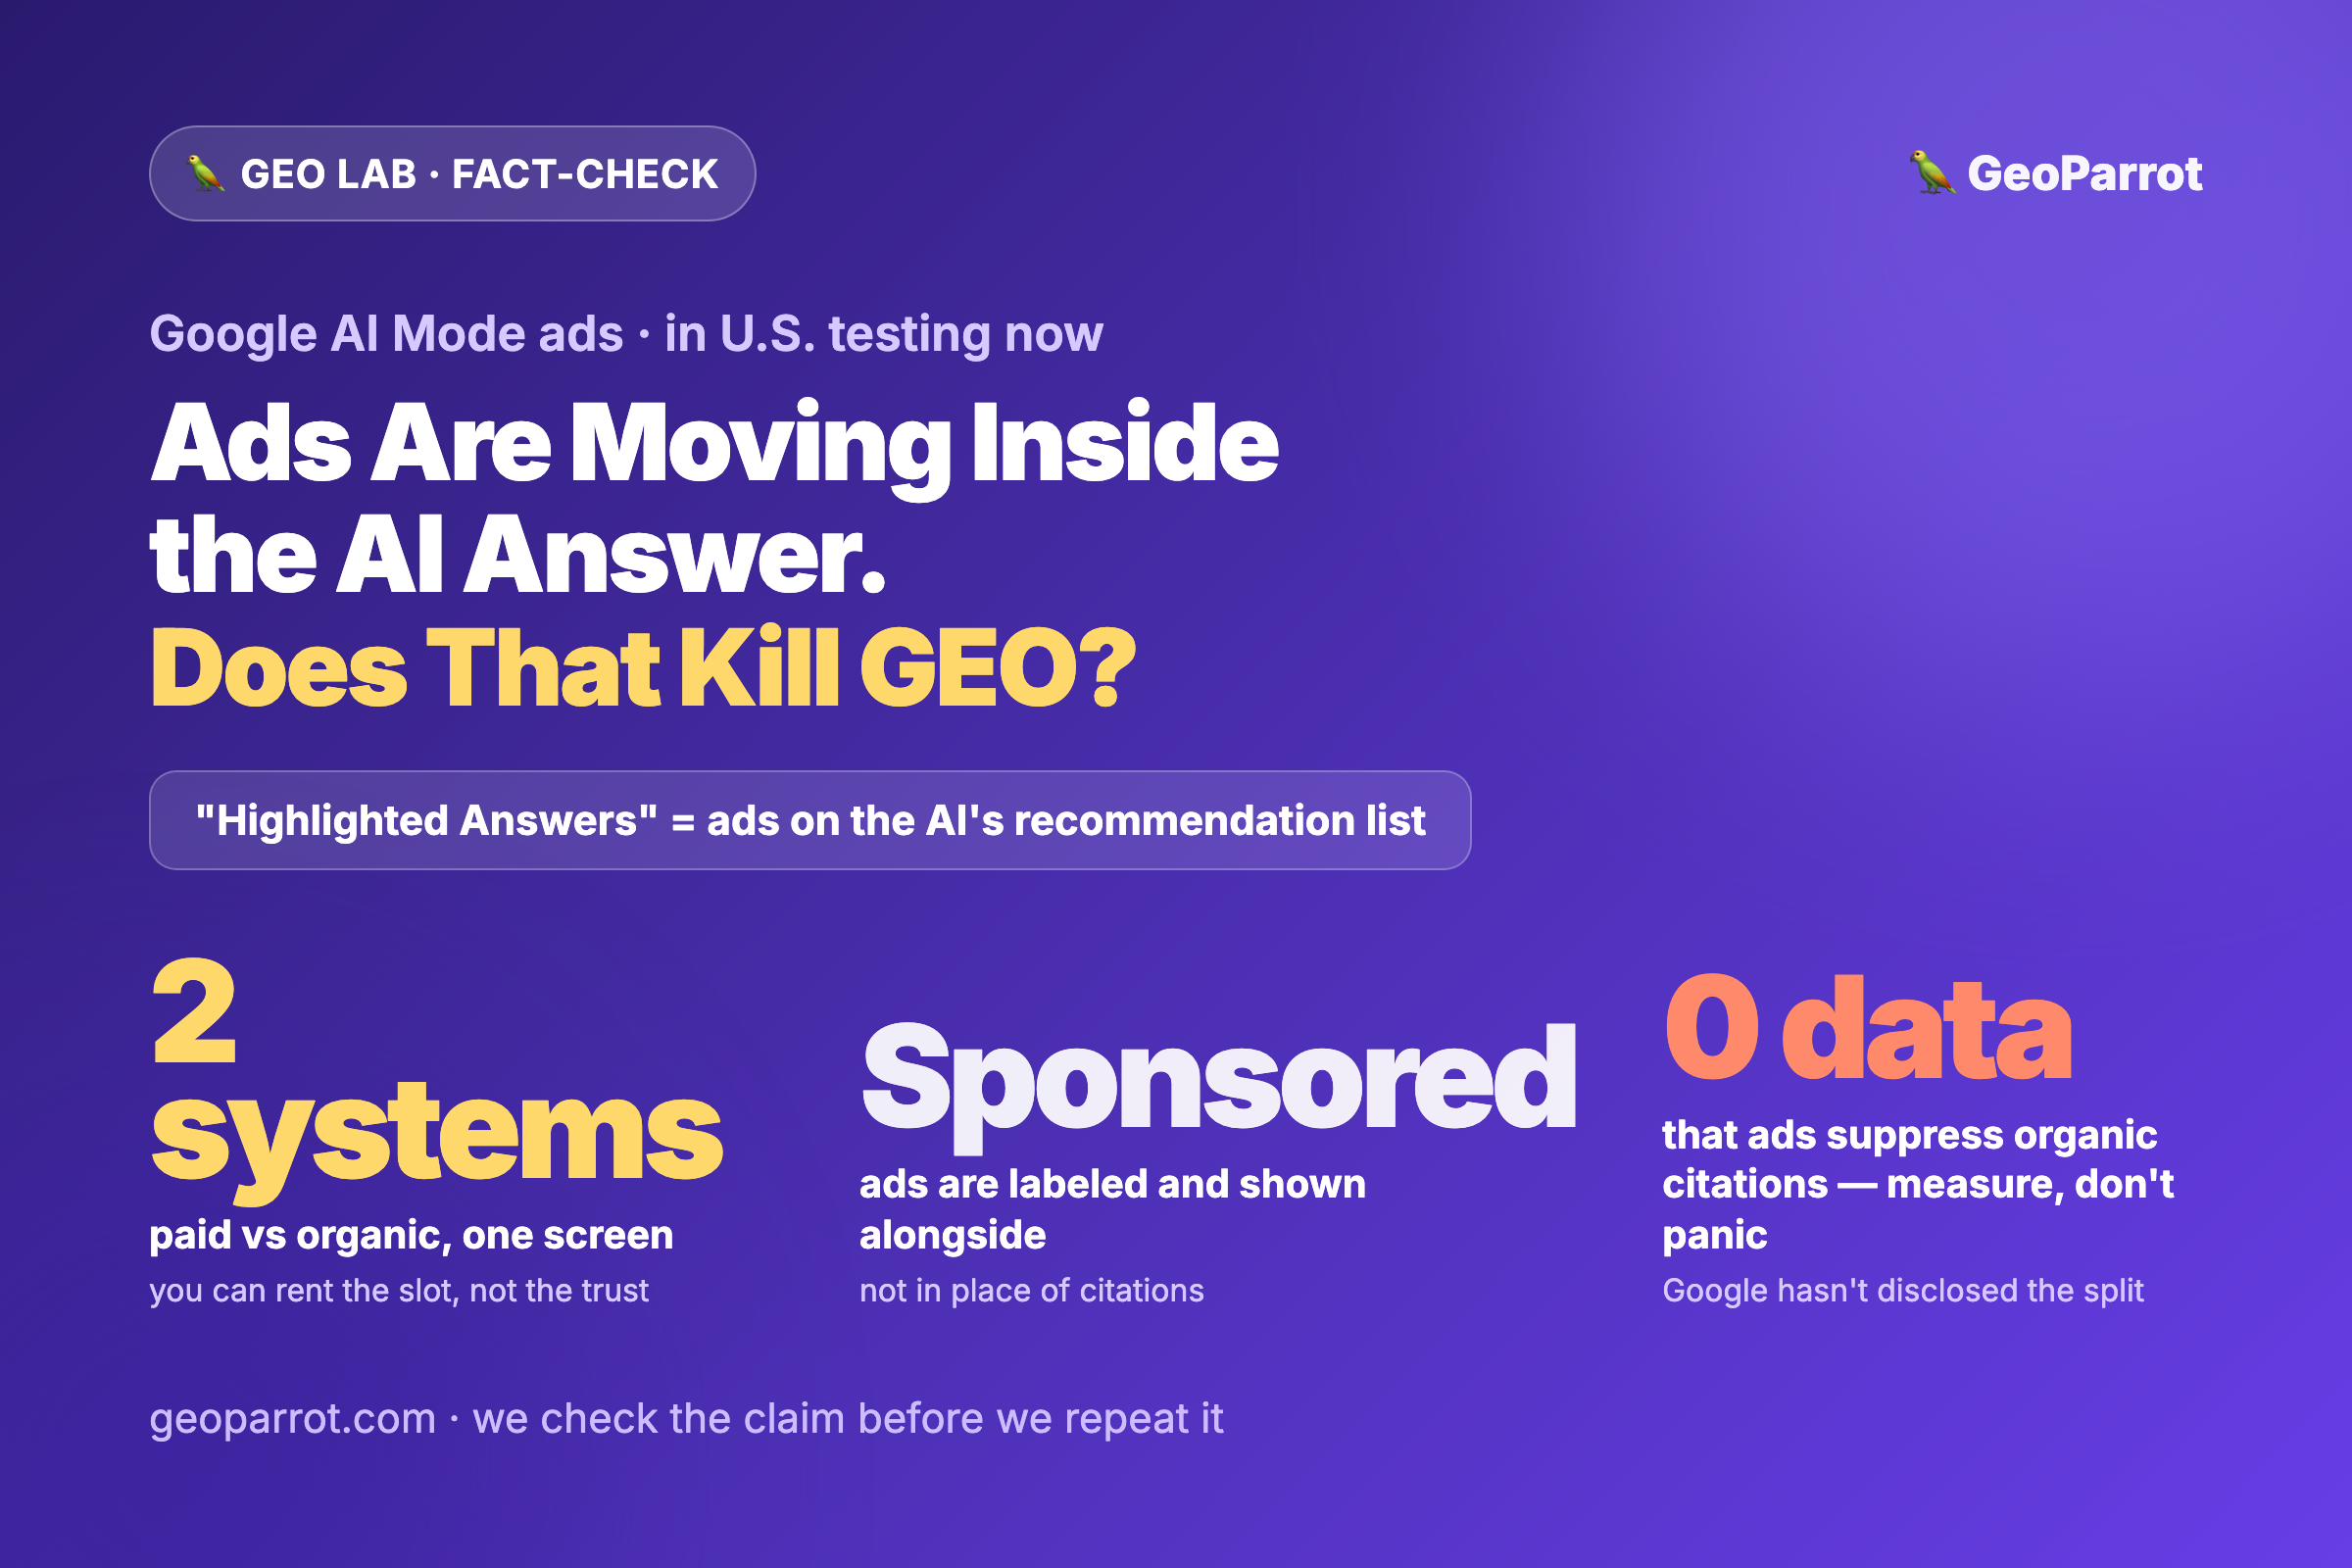
Google Is Putting Ads Inside AI Answers — What “Highlighted Answers” Mean for GEO
Google’s new Gemini-powered ad formats — Conversational Discovery ads, Highlighted Answers, and AI-powered Shopping ads — are being tested inside AI Mode responses right now, including ads that appear on the AI’s own recommendation list. That’s the exact surface GEO works to earn into. But paid placement and organic citation are two separate systems: buying…
-
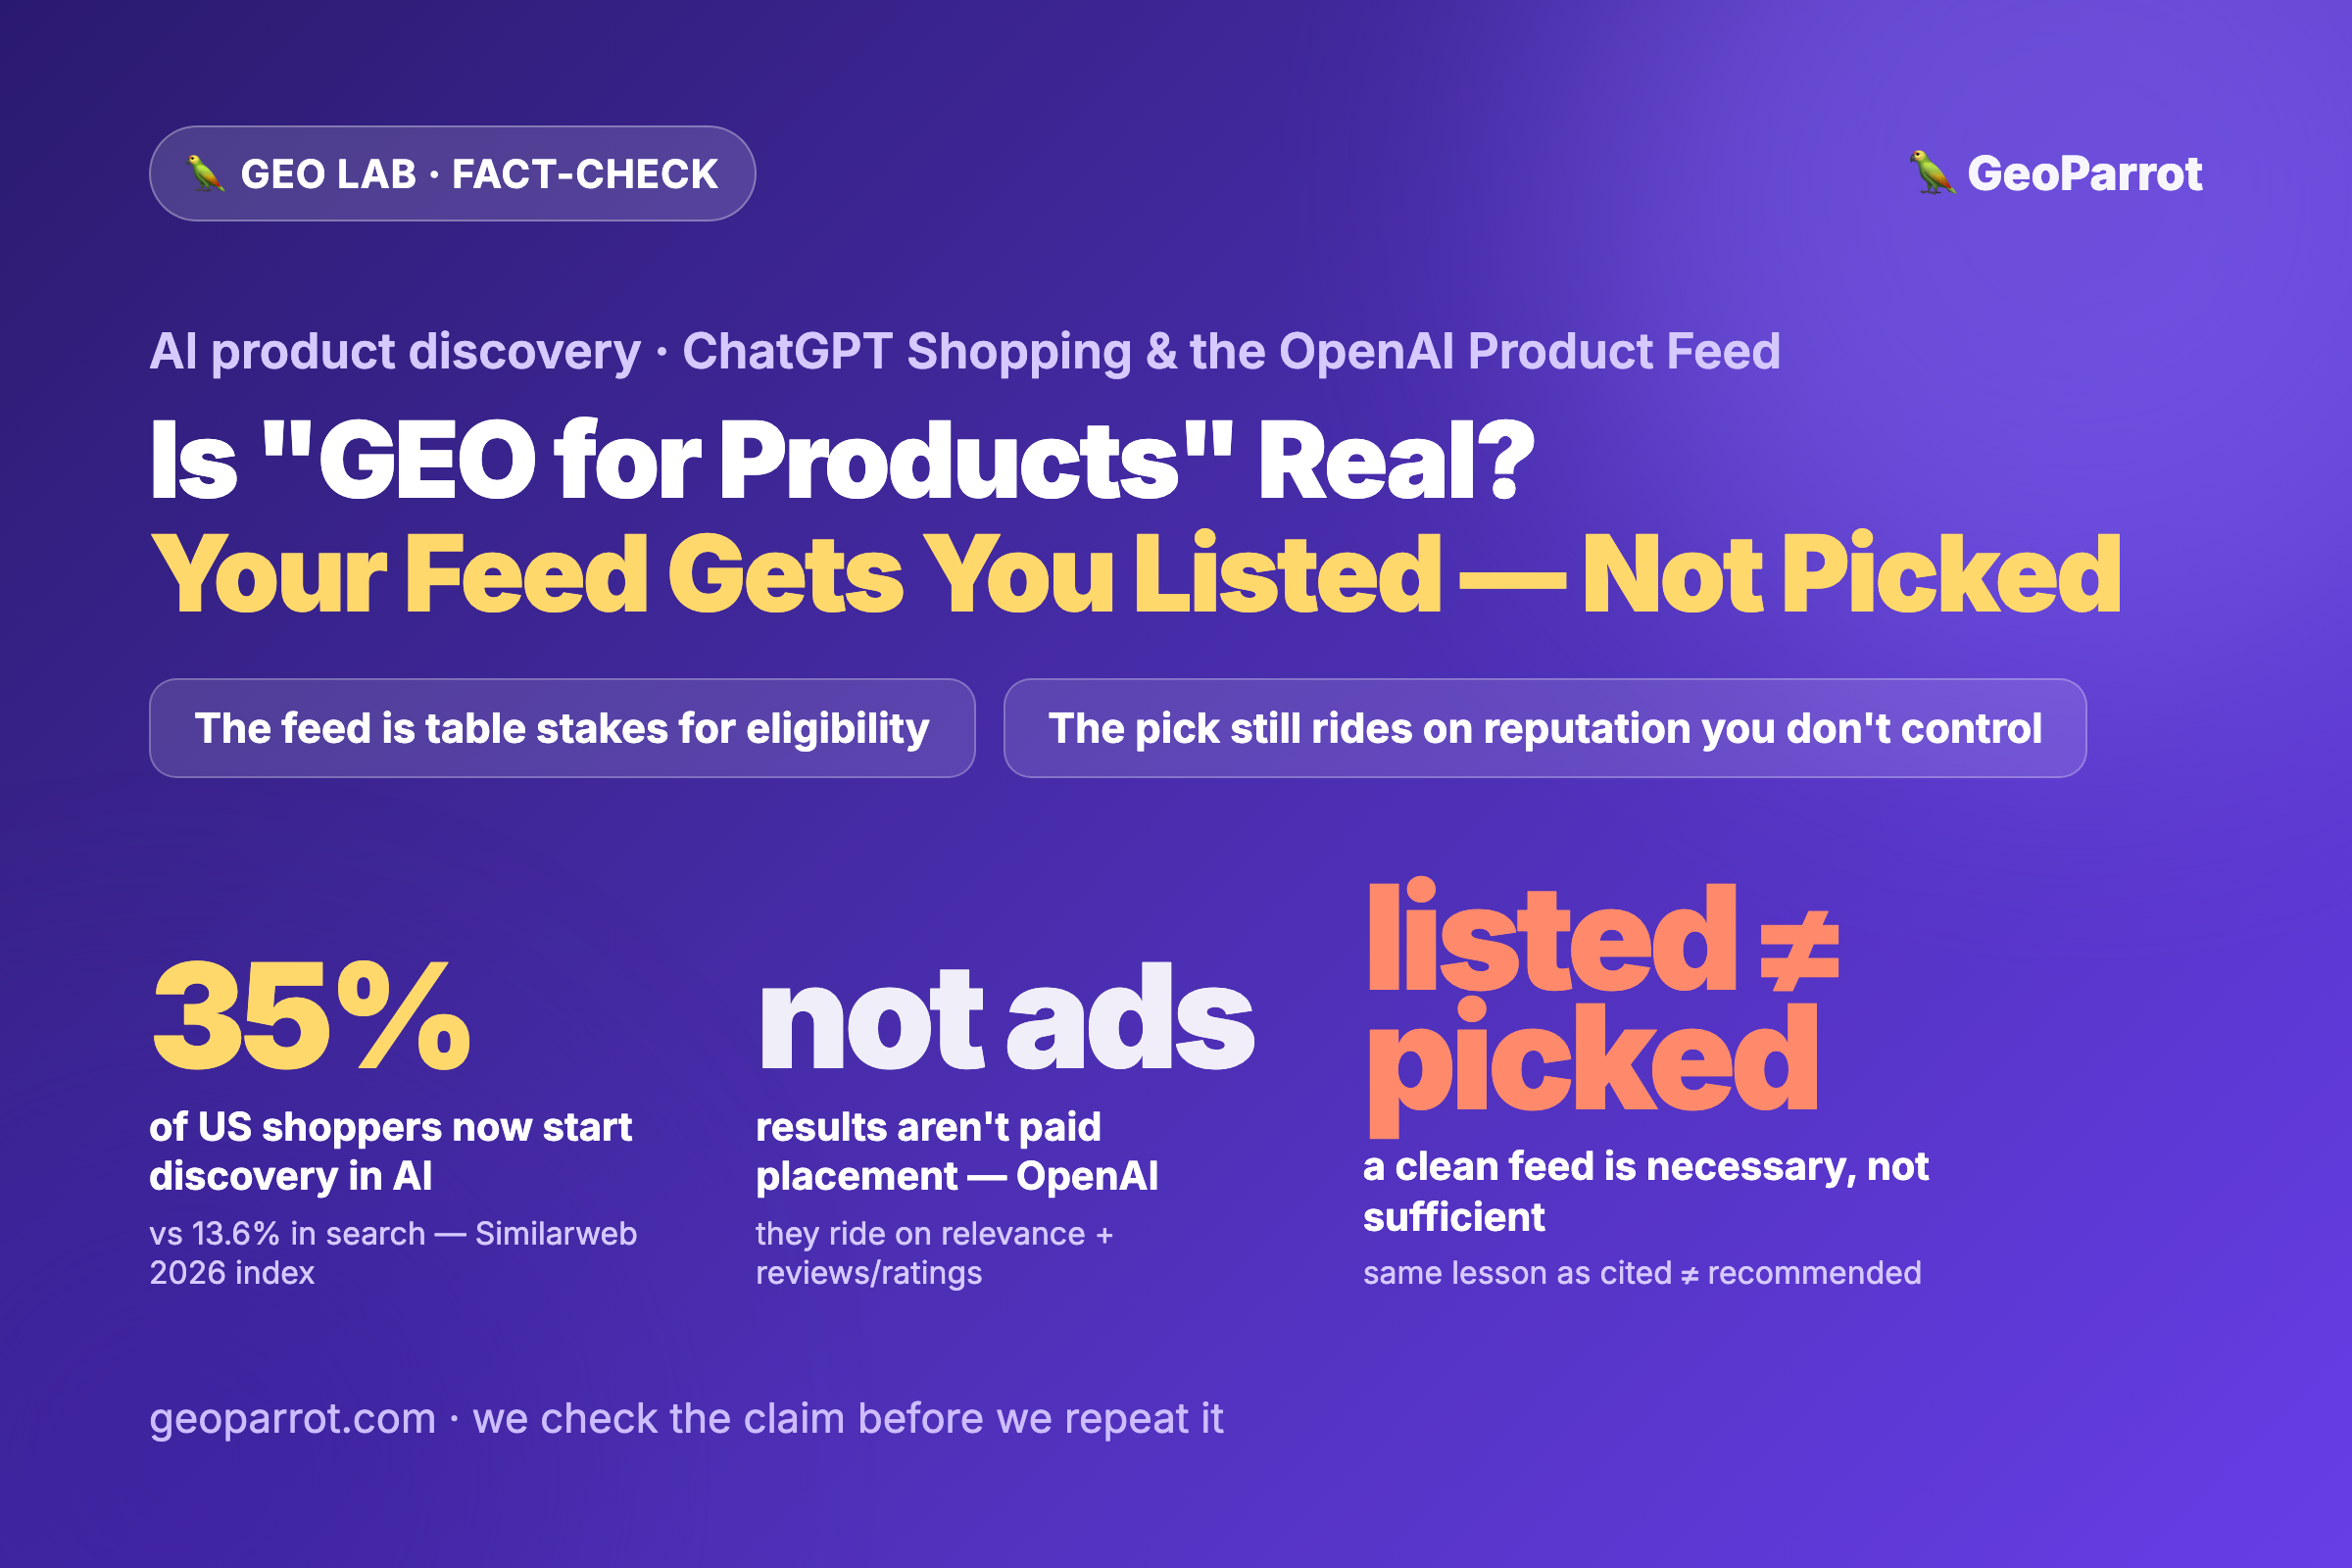
AI Is Eating Product Discovery. Is “GEO for Products” Real — or Just a Feed You Can’t Rank In?
A wave of “GEO for products” advice is landing as shoppers move discovery into ChatGPT, Gemini, and Perplexity. Here’s what actually changed — the OpenAI Product Feed, Agentic Commerce, ChatGPT Shopping — and the honest limit vendors skip: a clean feed makes you eligible, but it doesn’t buy you the pick. The lesson we’ve already…
-
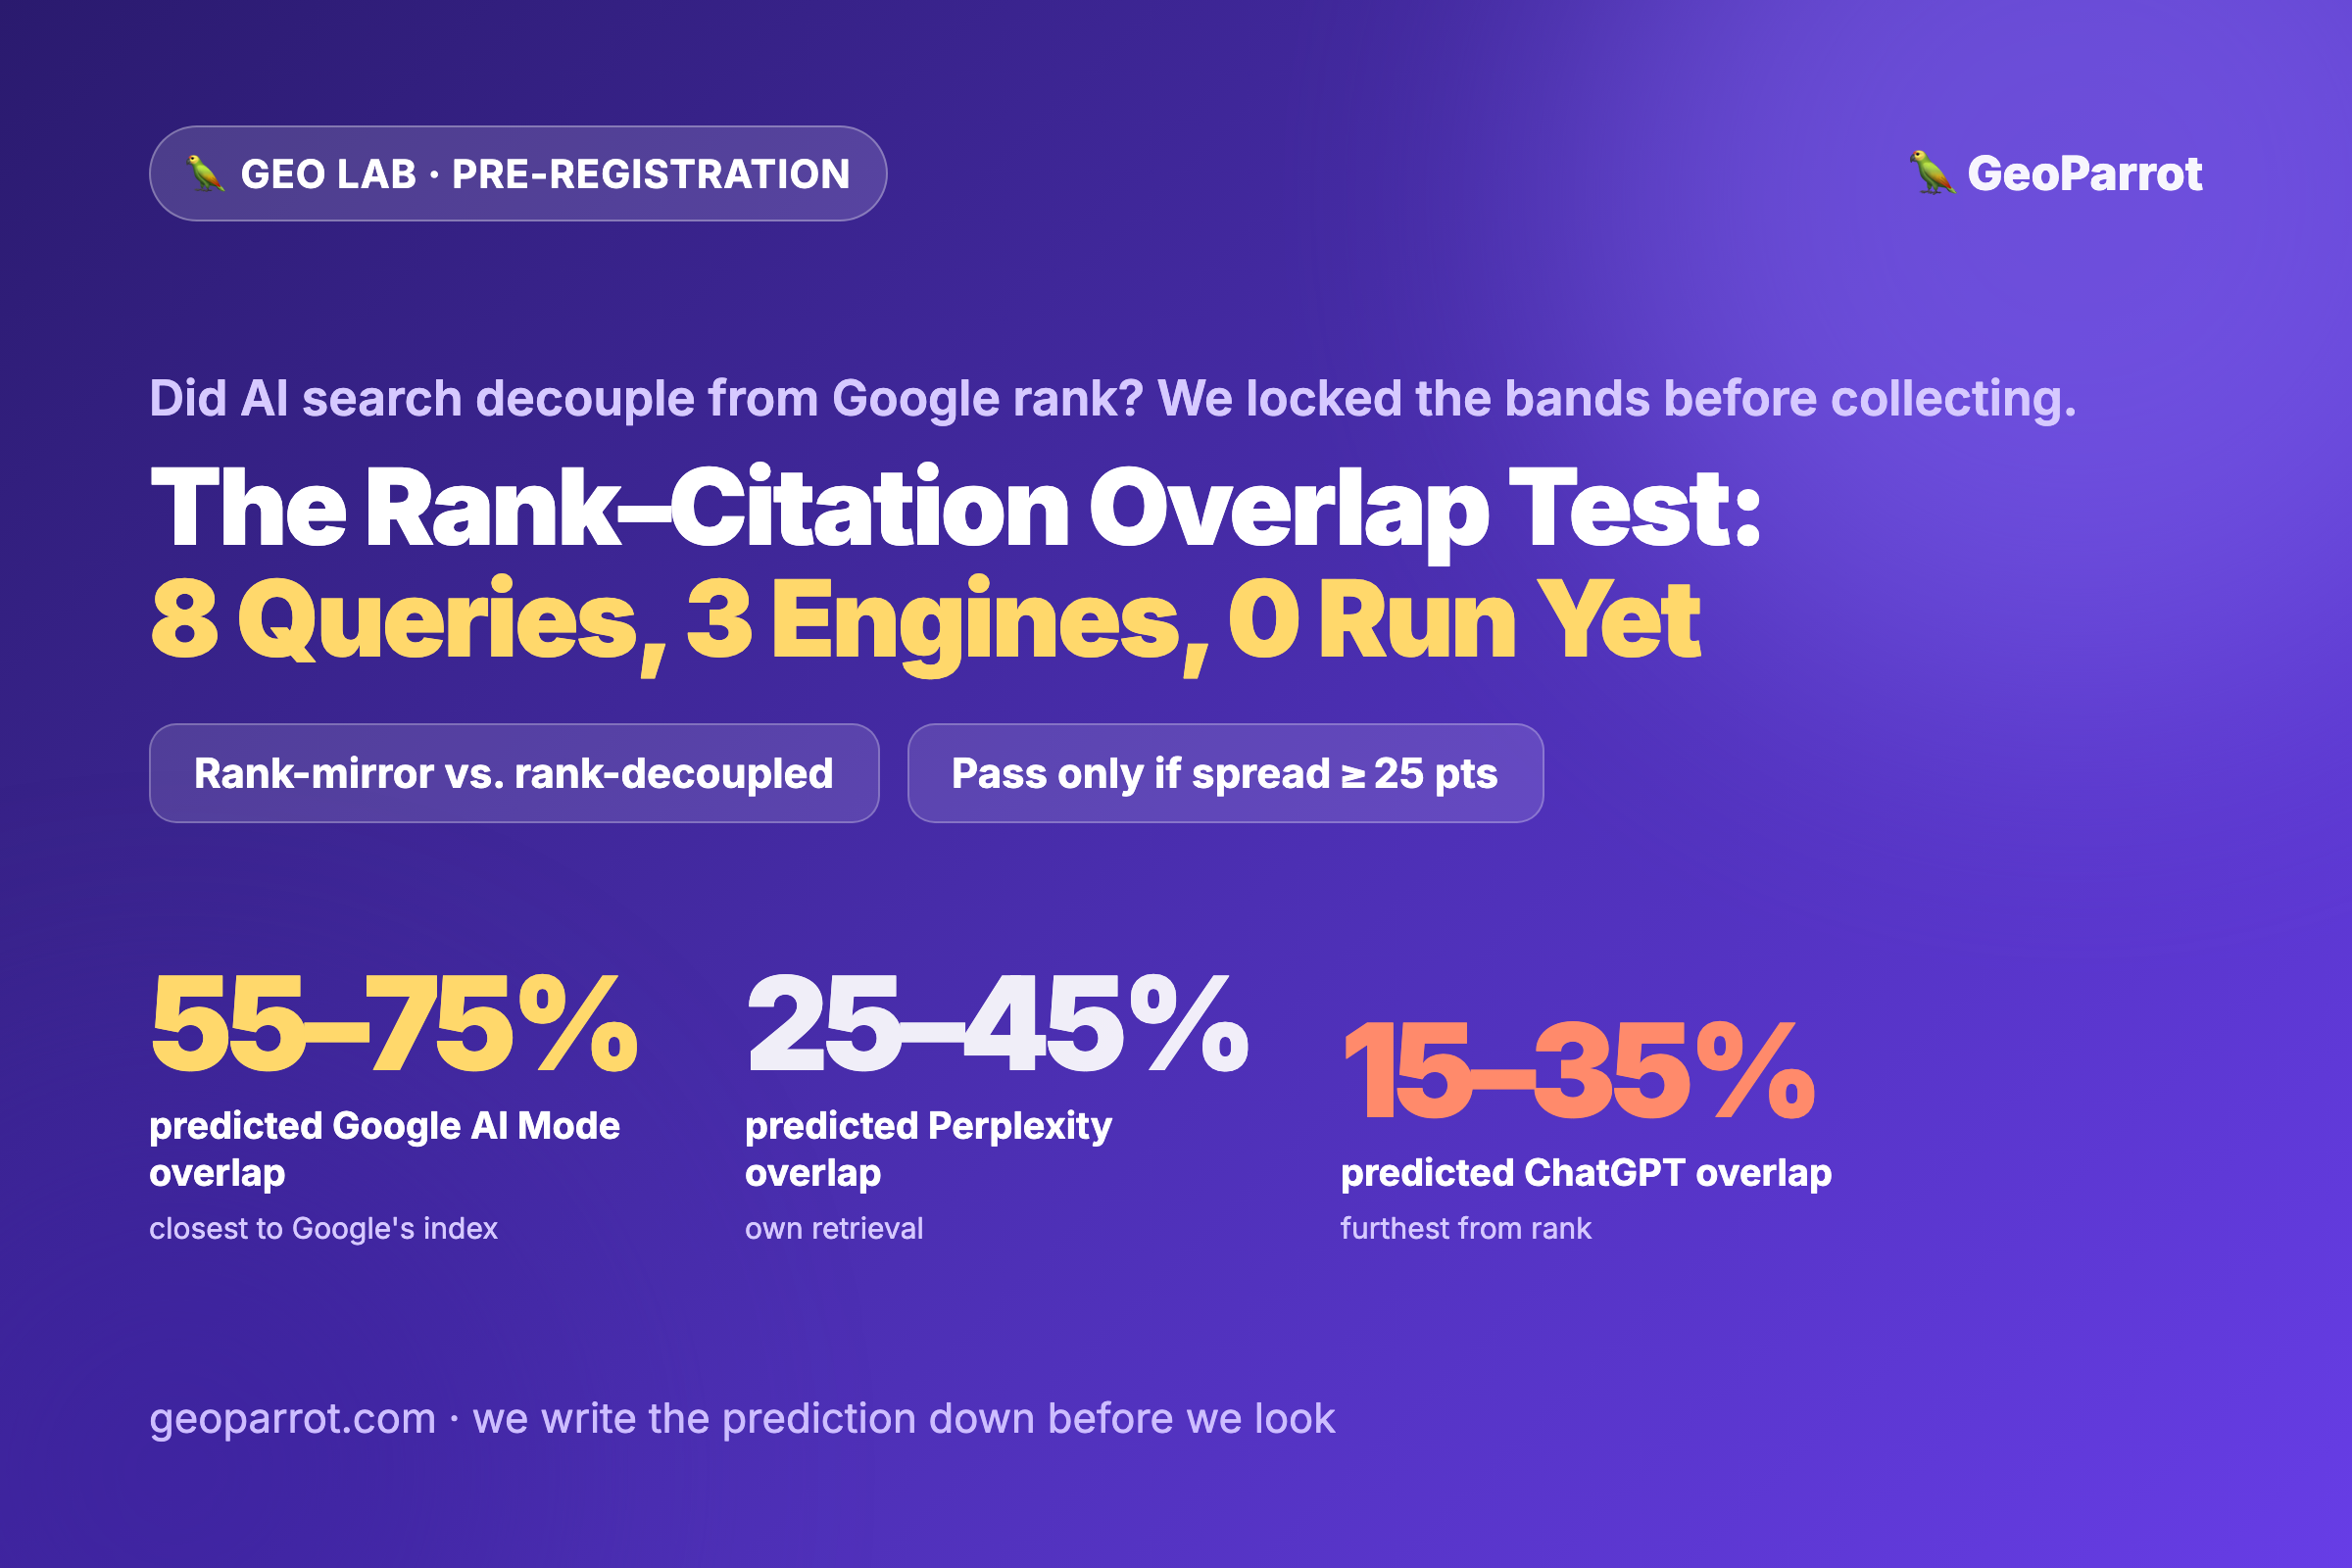
If AI Search Decoupled From Google Rank, Can We Measure the Gap Blind? Our Pre-Registered Protocol: 8 Buyer-Intent Queries, 3 Engines, and the Overlap Bands We Locked Before Collecting
Monday we argued that a #1 Google ranking no longer guarantees an AI citation — the top-rank-to-cited overlap fell from ~70% to under 20% — but that the collapse isn’t zero and isn’t uniform across engines. Today we turn that claim into a blind, pre-registered experiment. Two rival models compete: the rank-mirror model (AI answers…
-
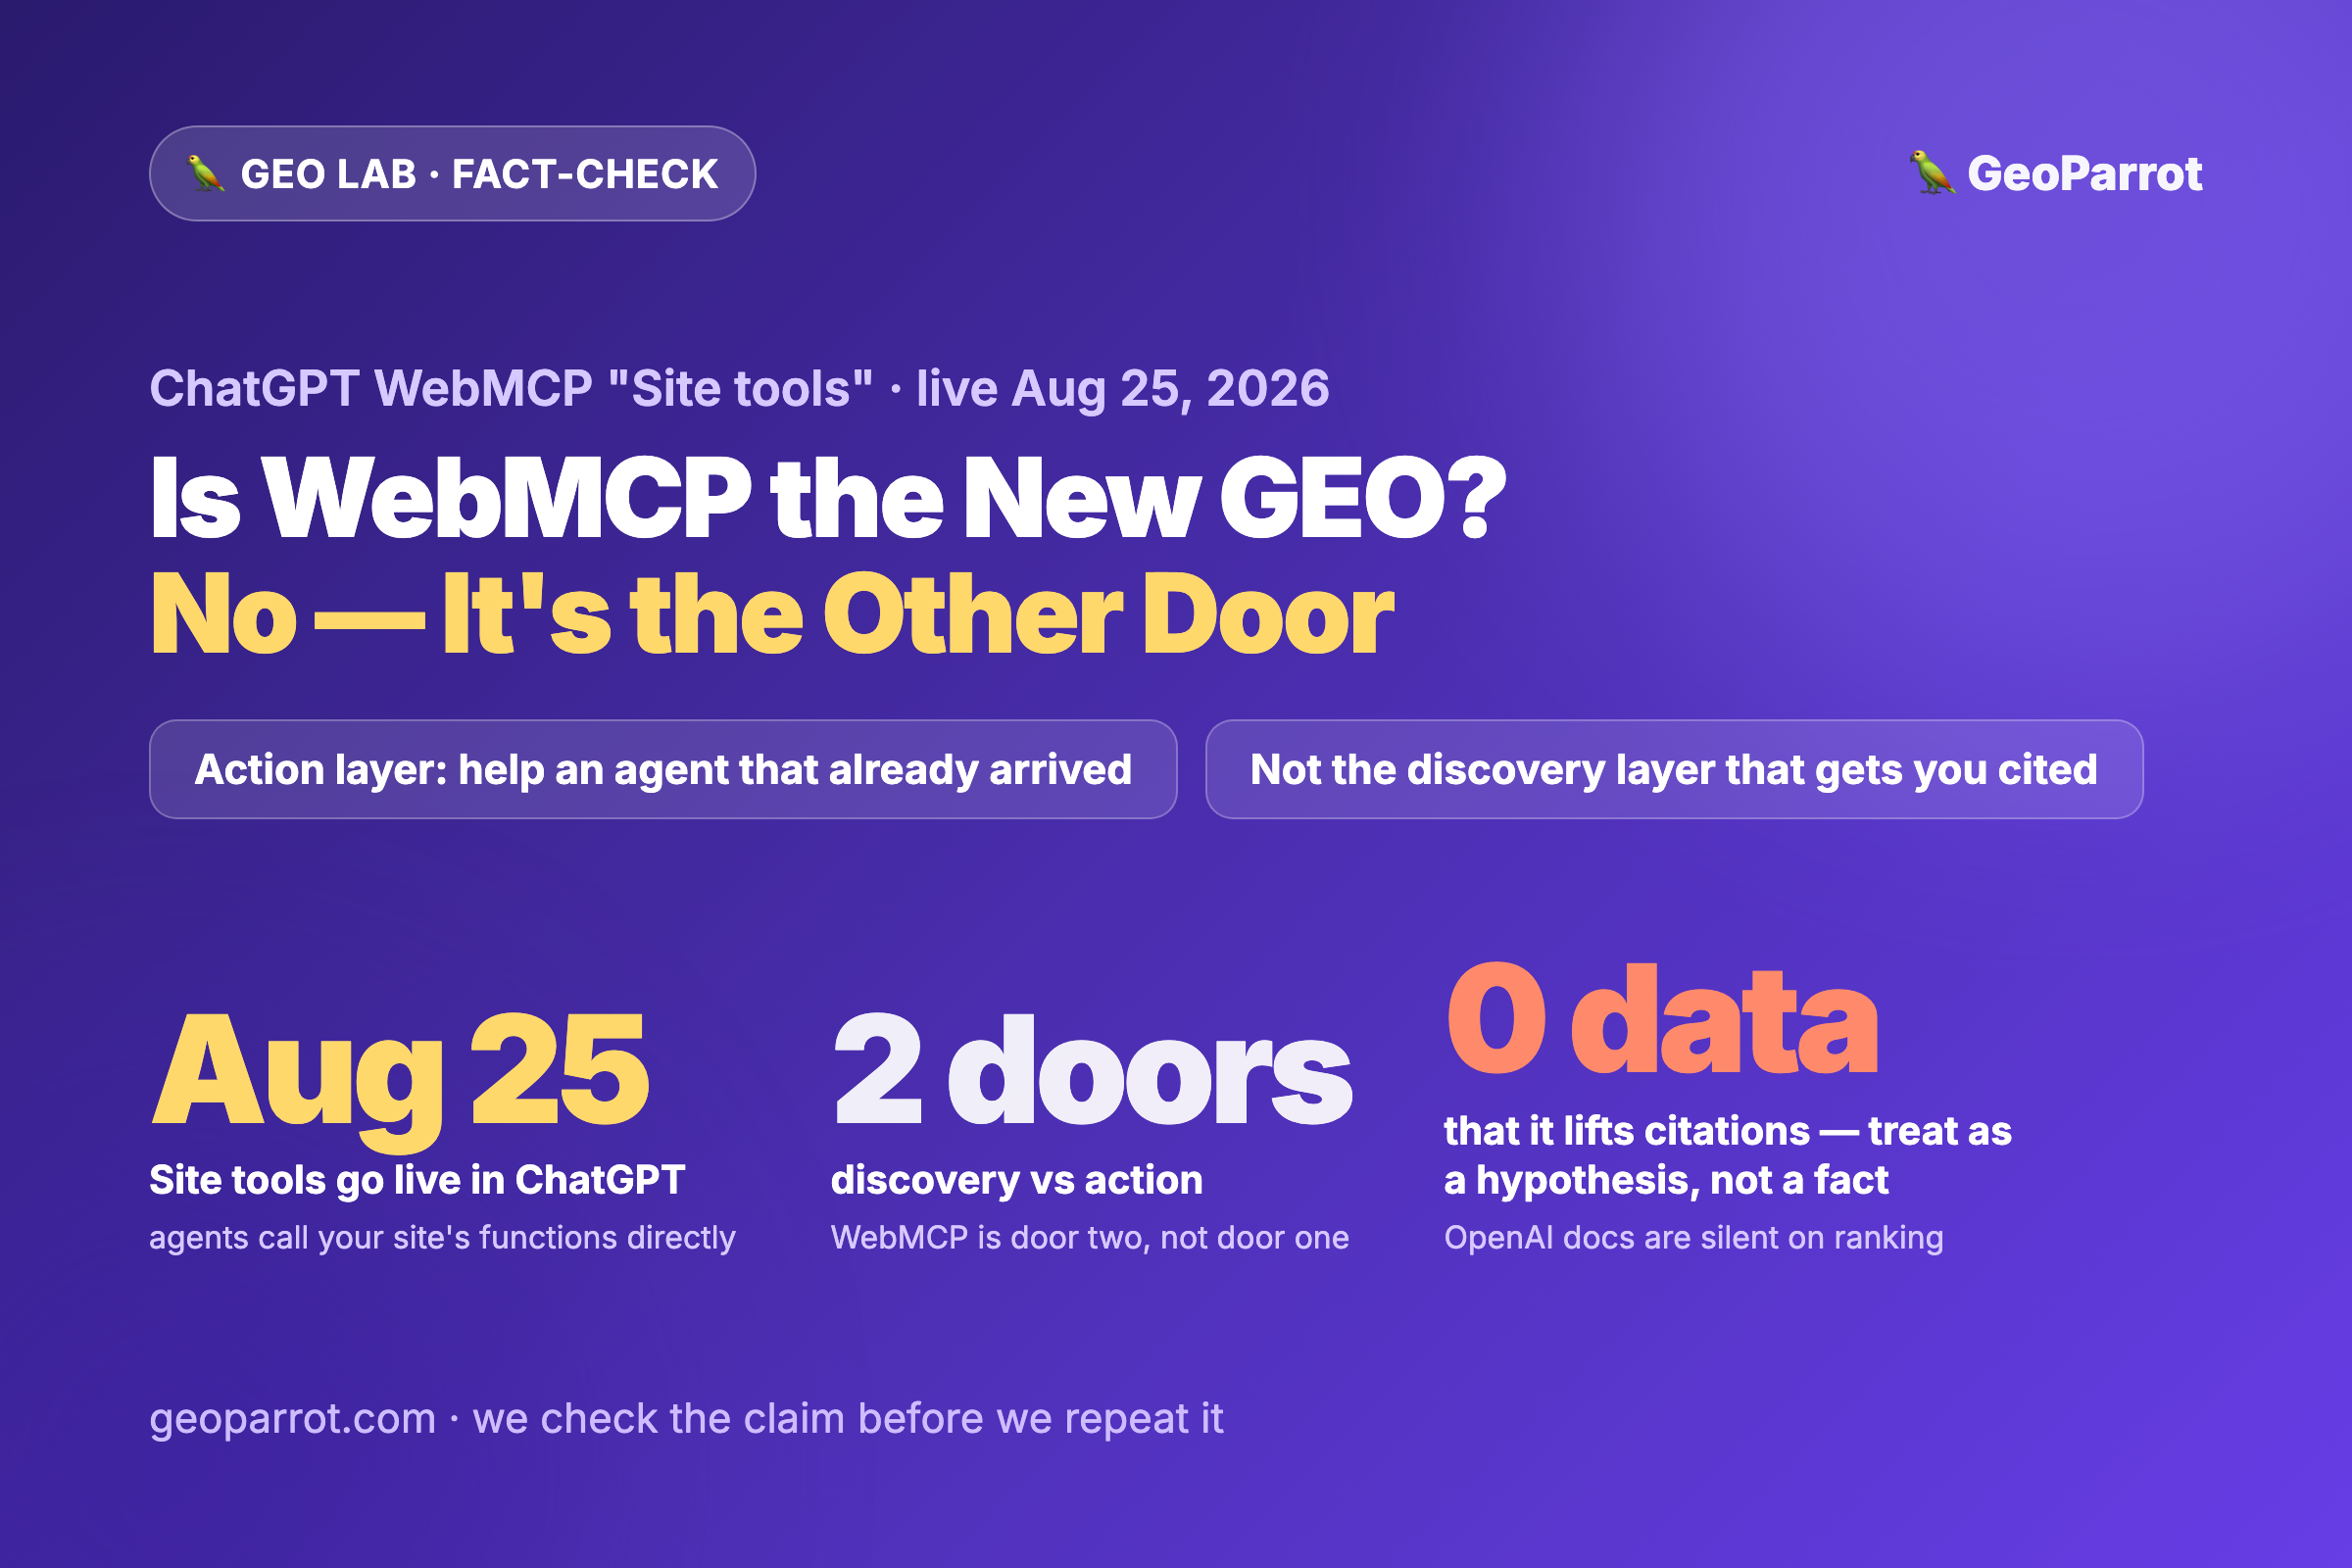
ChatGPT Just Shipped “Site Tools” (WebMCP) — Is This the New GEO?
On August 25, 2026, OpenAI added WebMCP “Site tools” to ChatGPT’s desktop browser, letting agents call a website’s own functions instead of guessing through its UI. It’s being framed as the next GEO. It isn’t — or not the way the hype says. WebMCP is the action layer (help an agent that already arrived get…
-
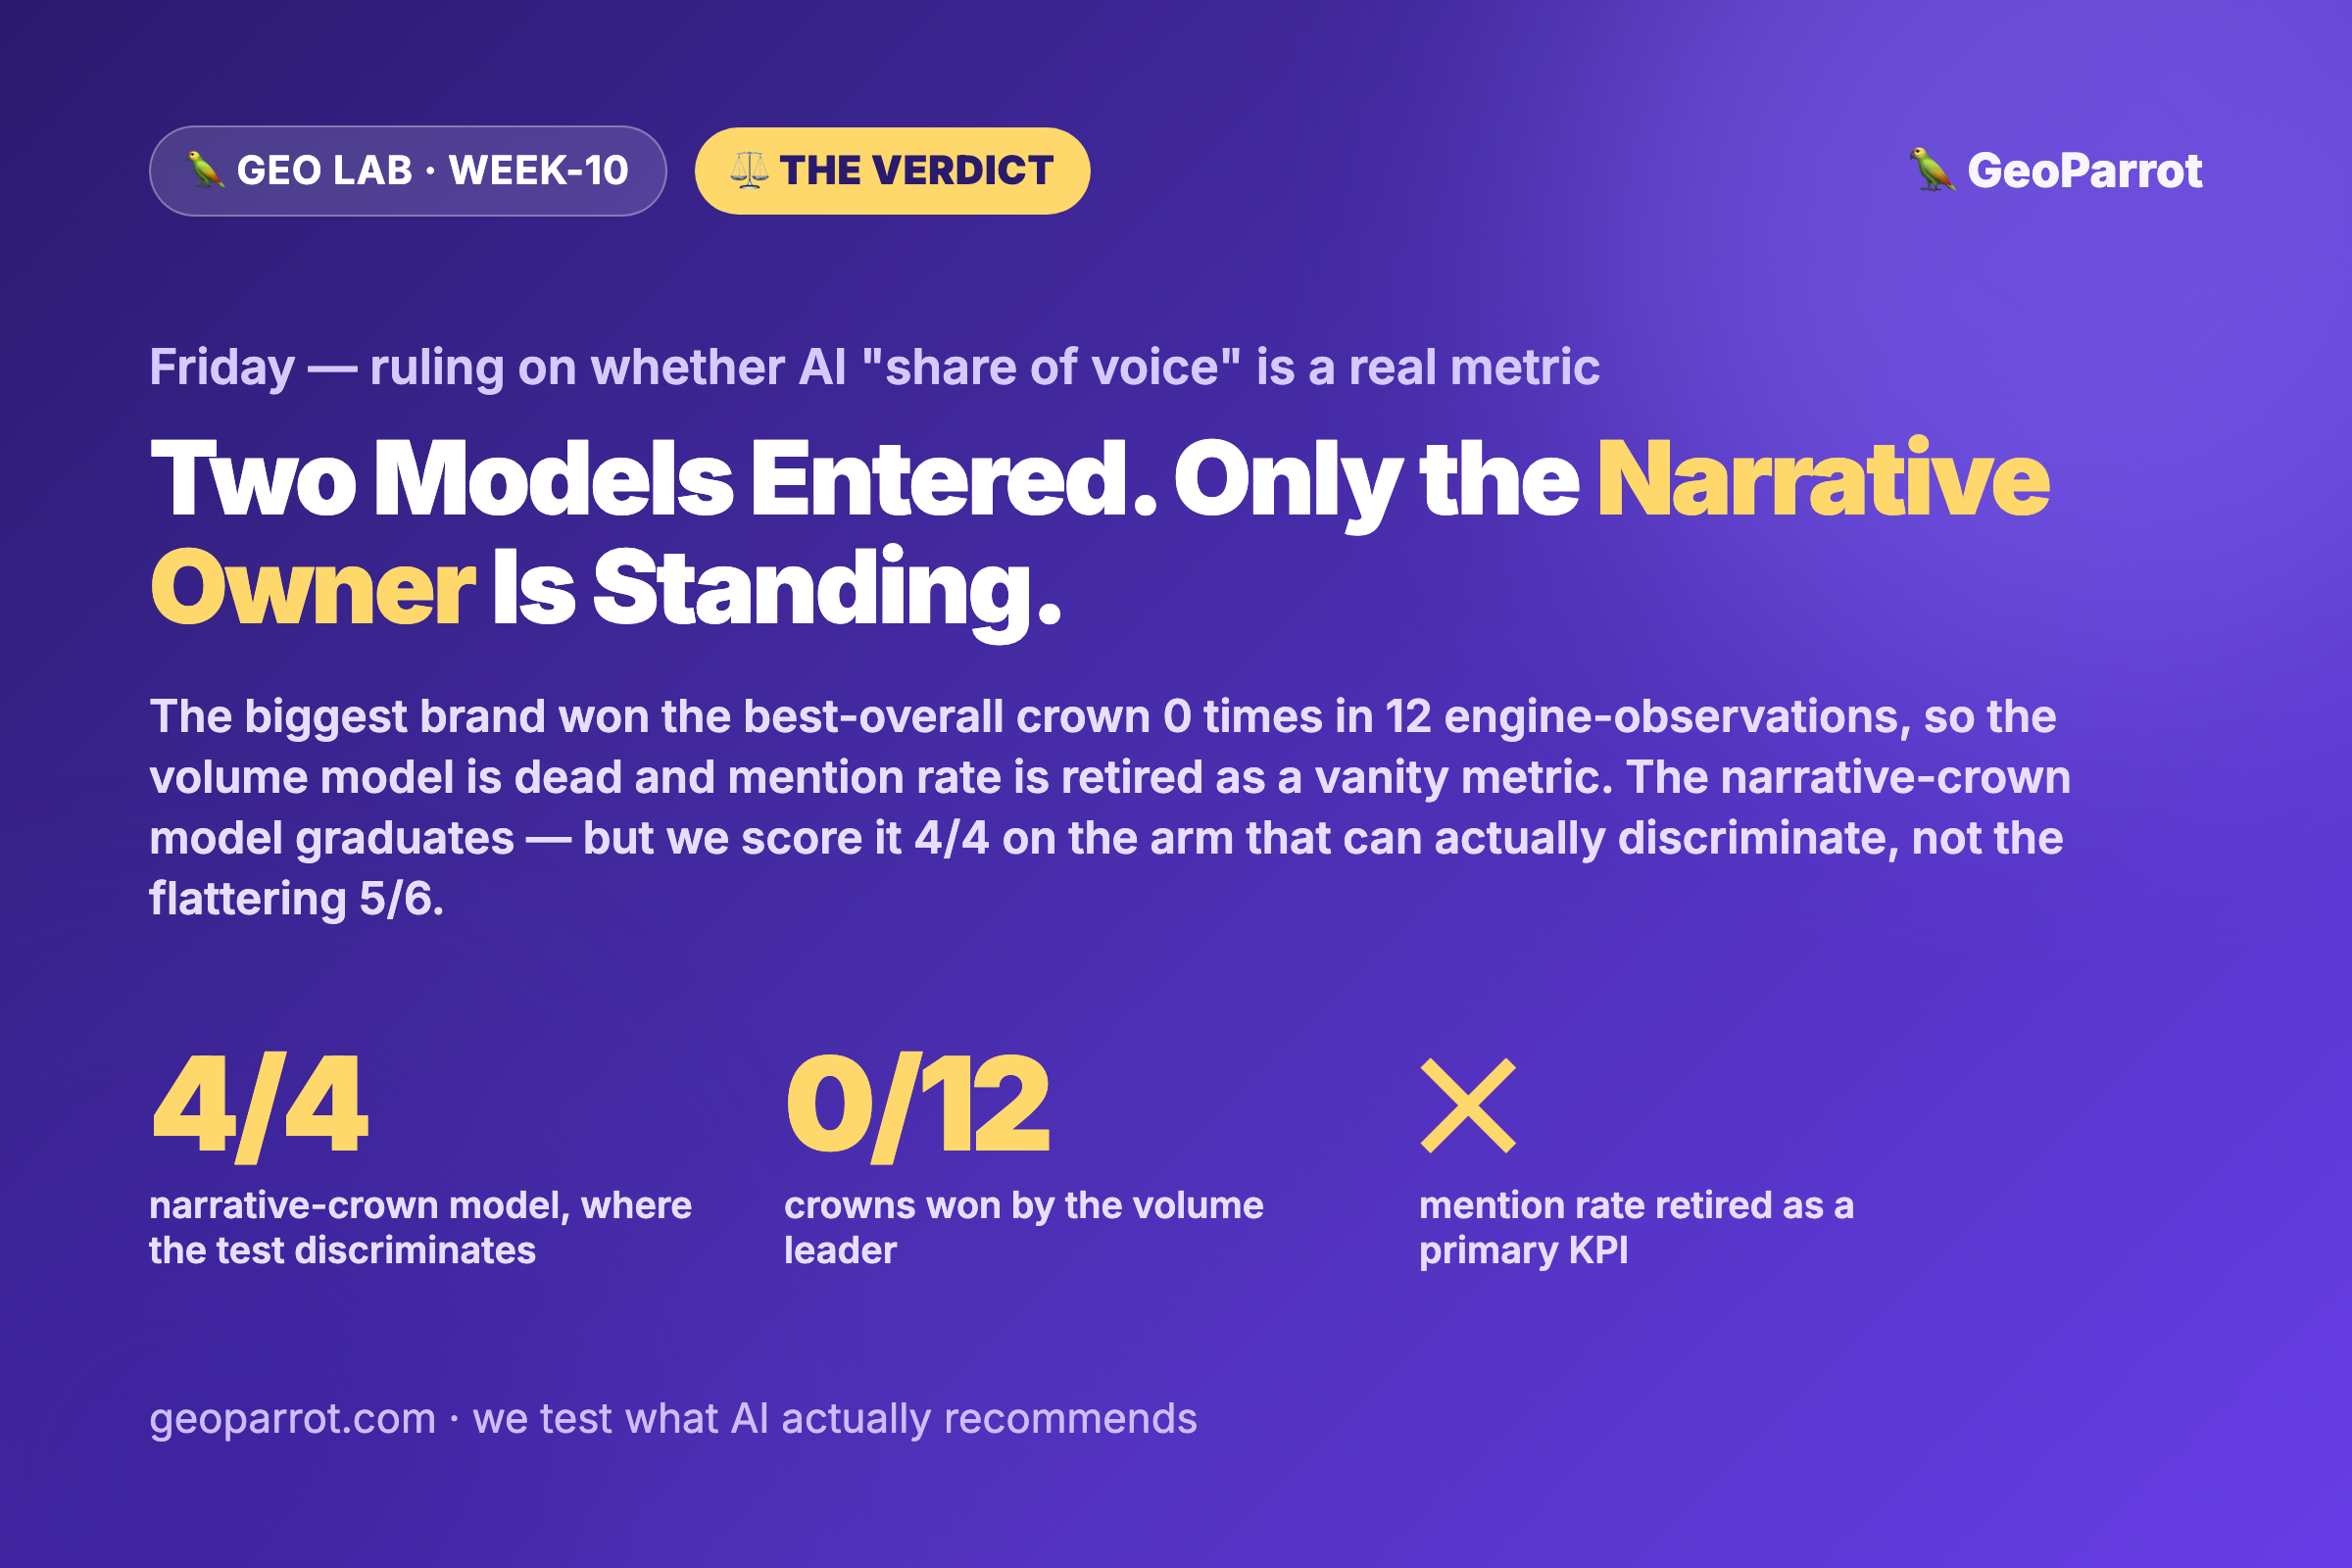
The Verdict: The Narrative-Crown Model Graduates — But at 4/4, Not the Flattering 5/6. The Volume Leader Went 0-for-12, So We’re Retiring “Mention Rate” as a Vanity Metric
This week we asked whether “AI share of voice” is a real metric or a vanity number, and whether the only score that moves a buyer — the best-overall crown — can be called blind. Monday we argued mention rate is vanity. Tuesday we pre-registered 6 crown predictions and locked them. Thursday we scored 5…
-
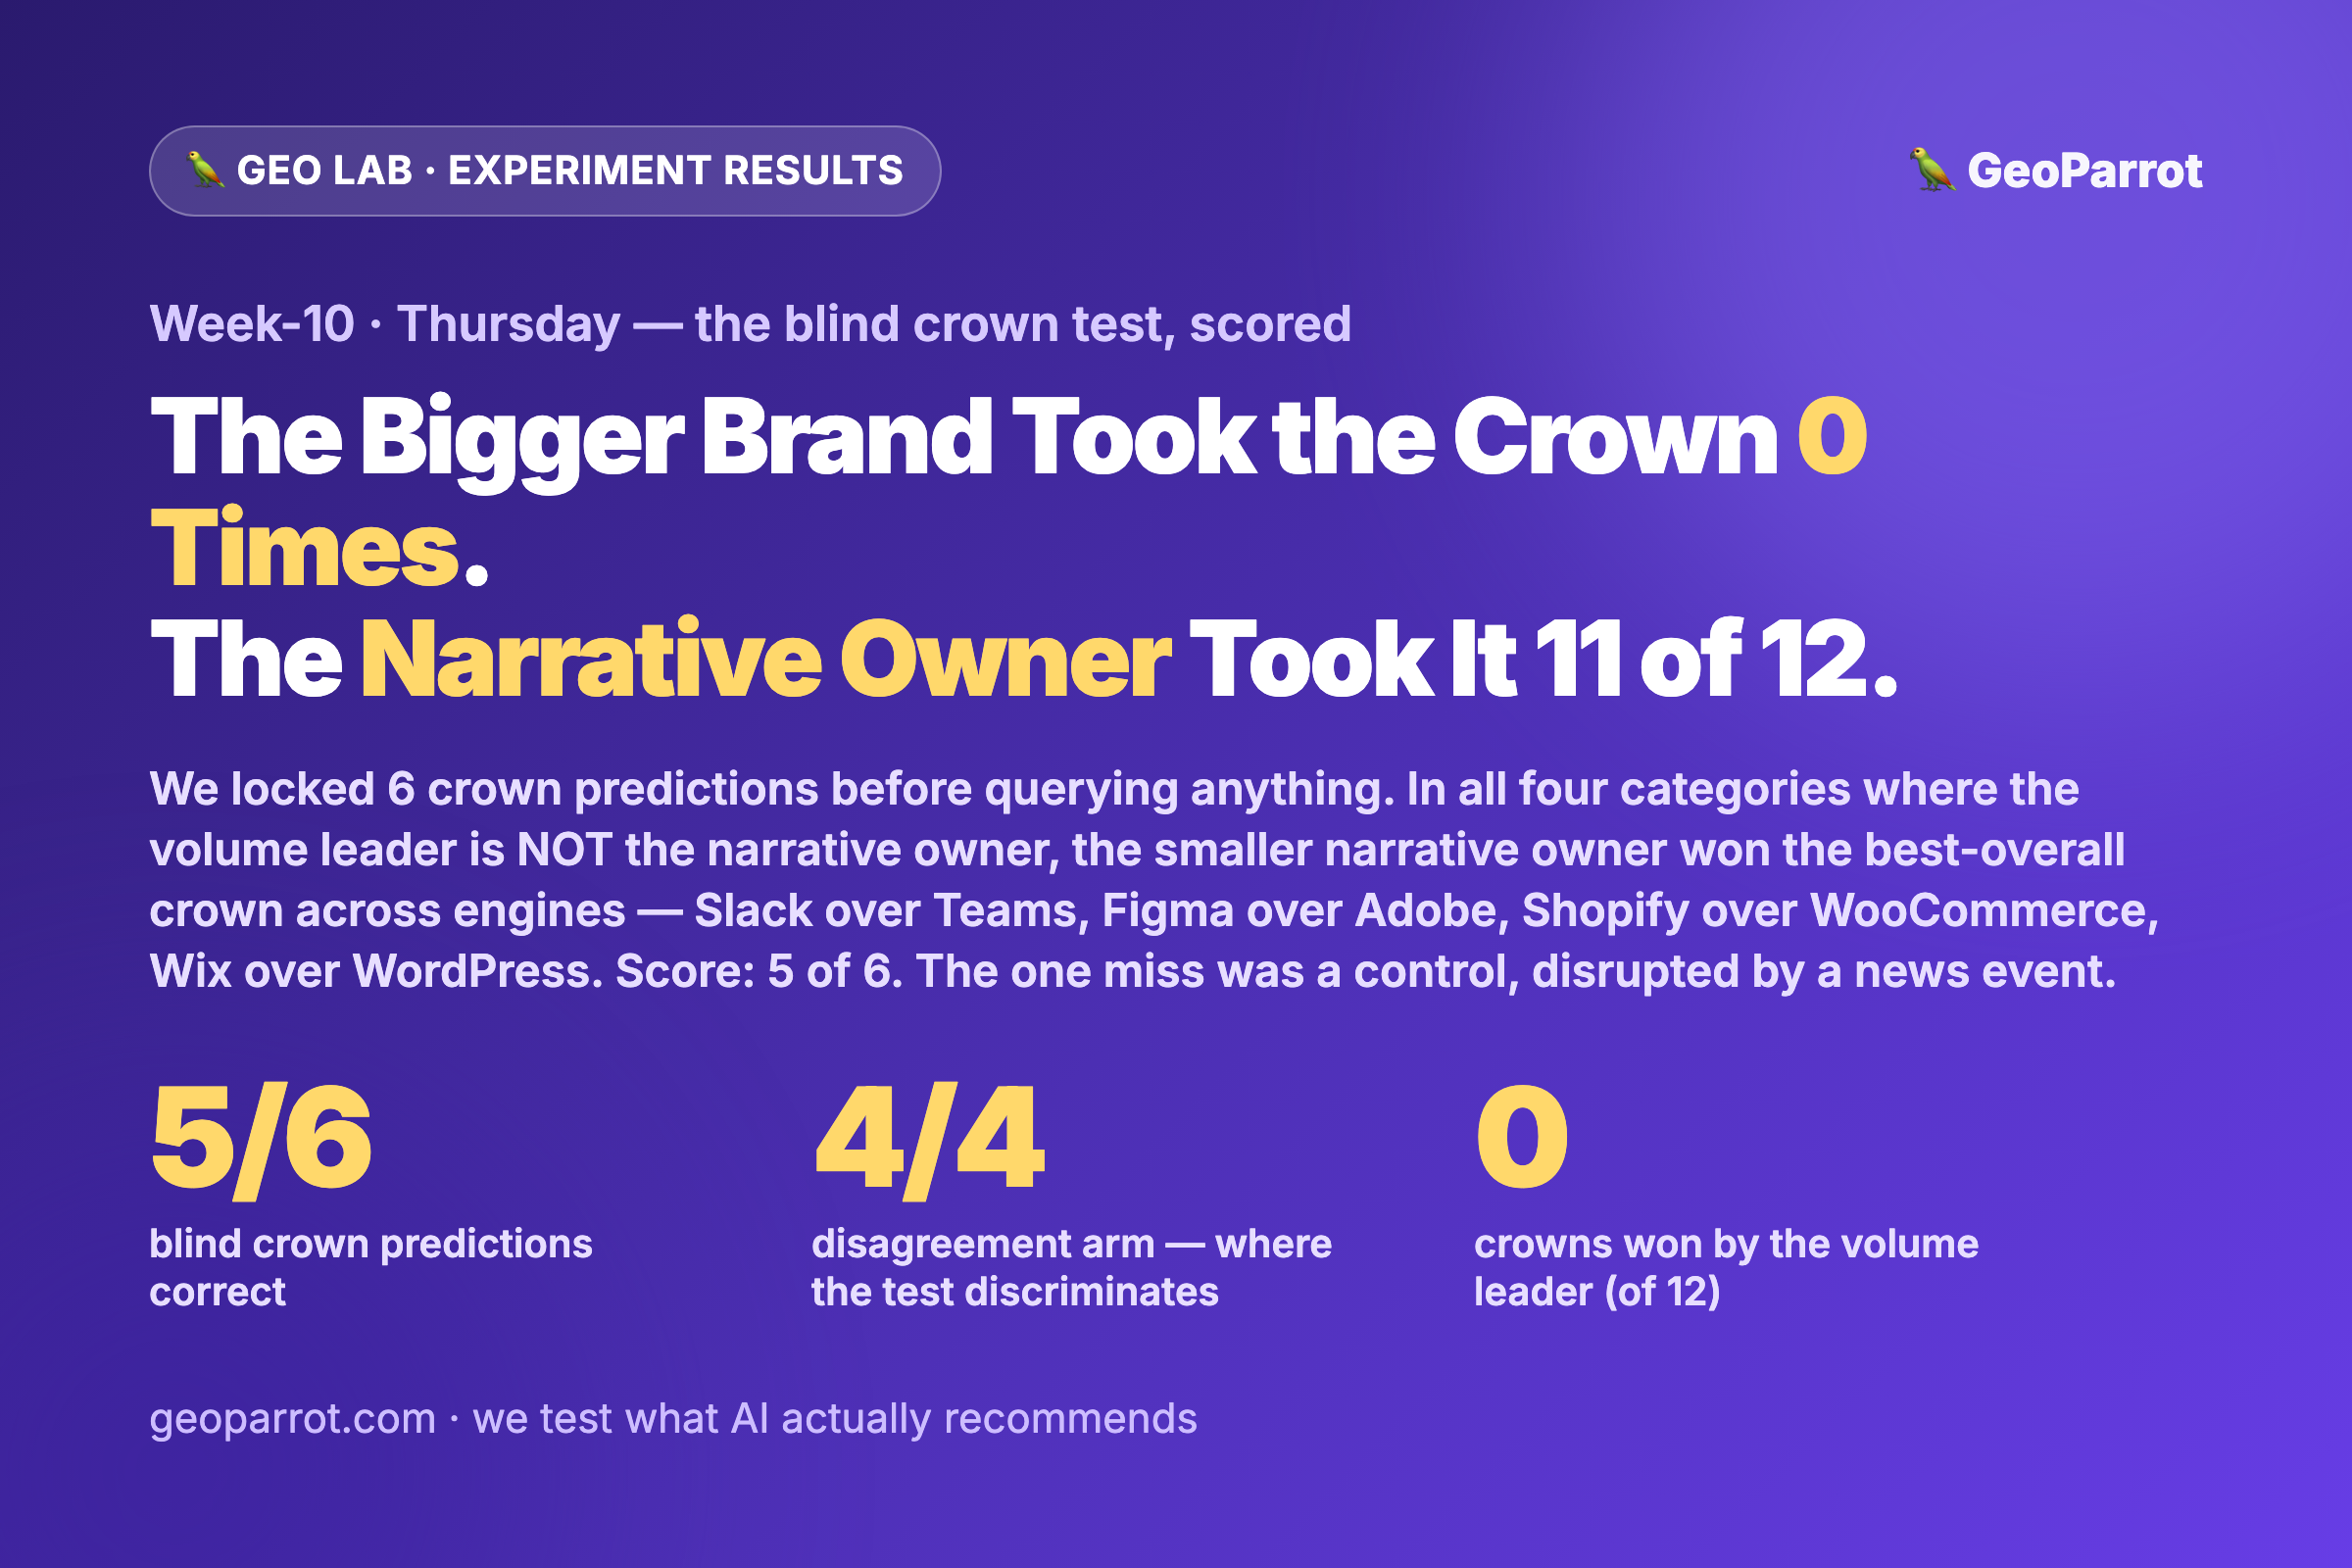
The Blind Crown Test Scored 5 of 6 — and the Volume Leader Won 0 of 12: In Every Category Where the Biggest Brand Isn’t the Narrative Owner, AI Crowned the Smaller Brand
On Tuesday we pre-registered 6 predictions and locked them before querying a single engine: in each category, we bet the “best-overall crown” would go to the narrative owner — the brand that owns the category’s defining sentence — not the volume leader with more installs or mentions. Today we ran the neutral query “best [category]…