Author: GeoParrot Team
-
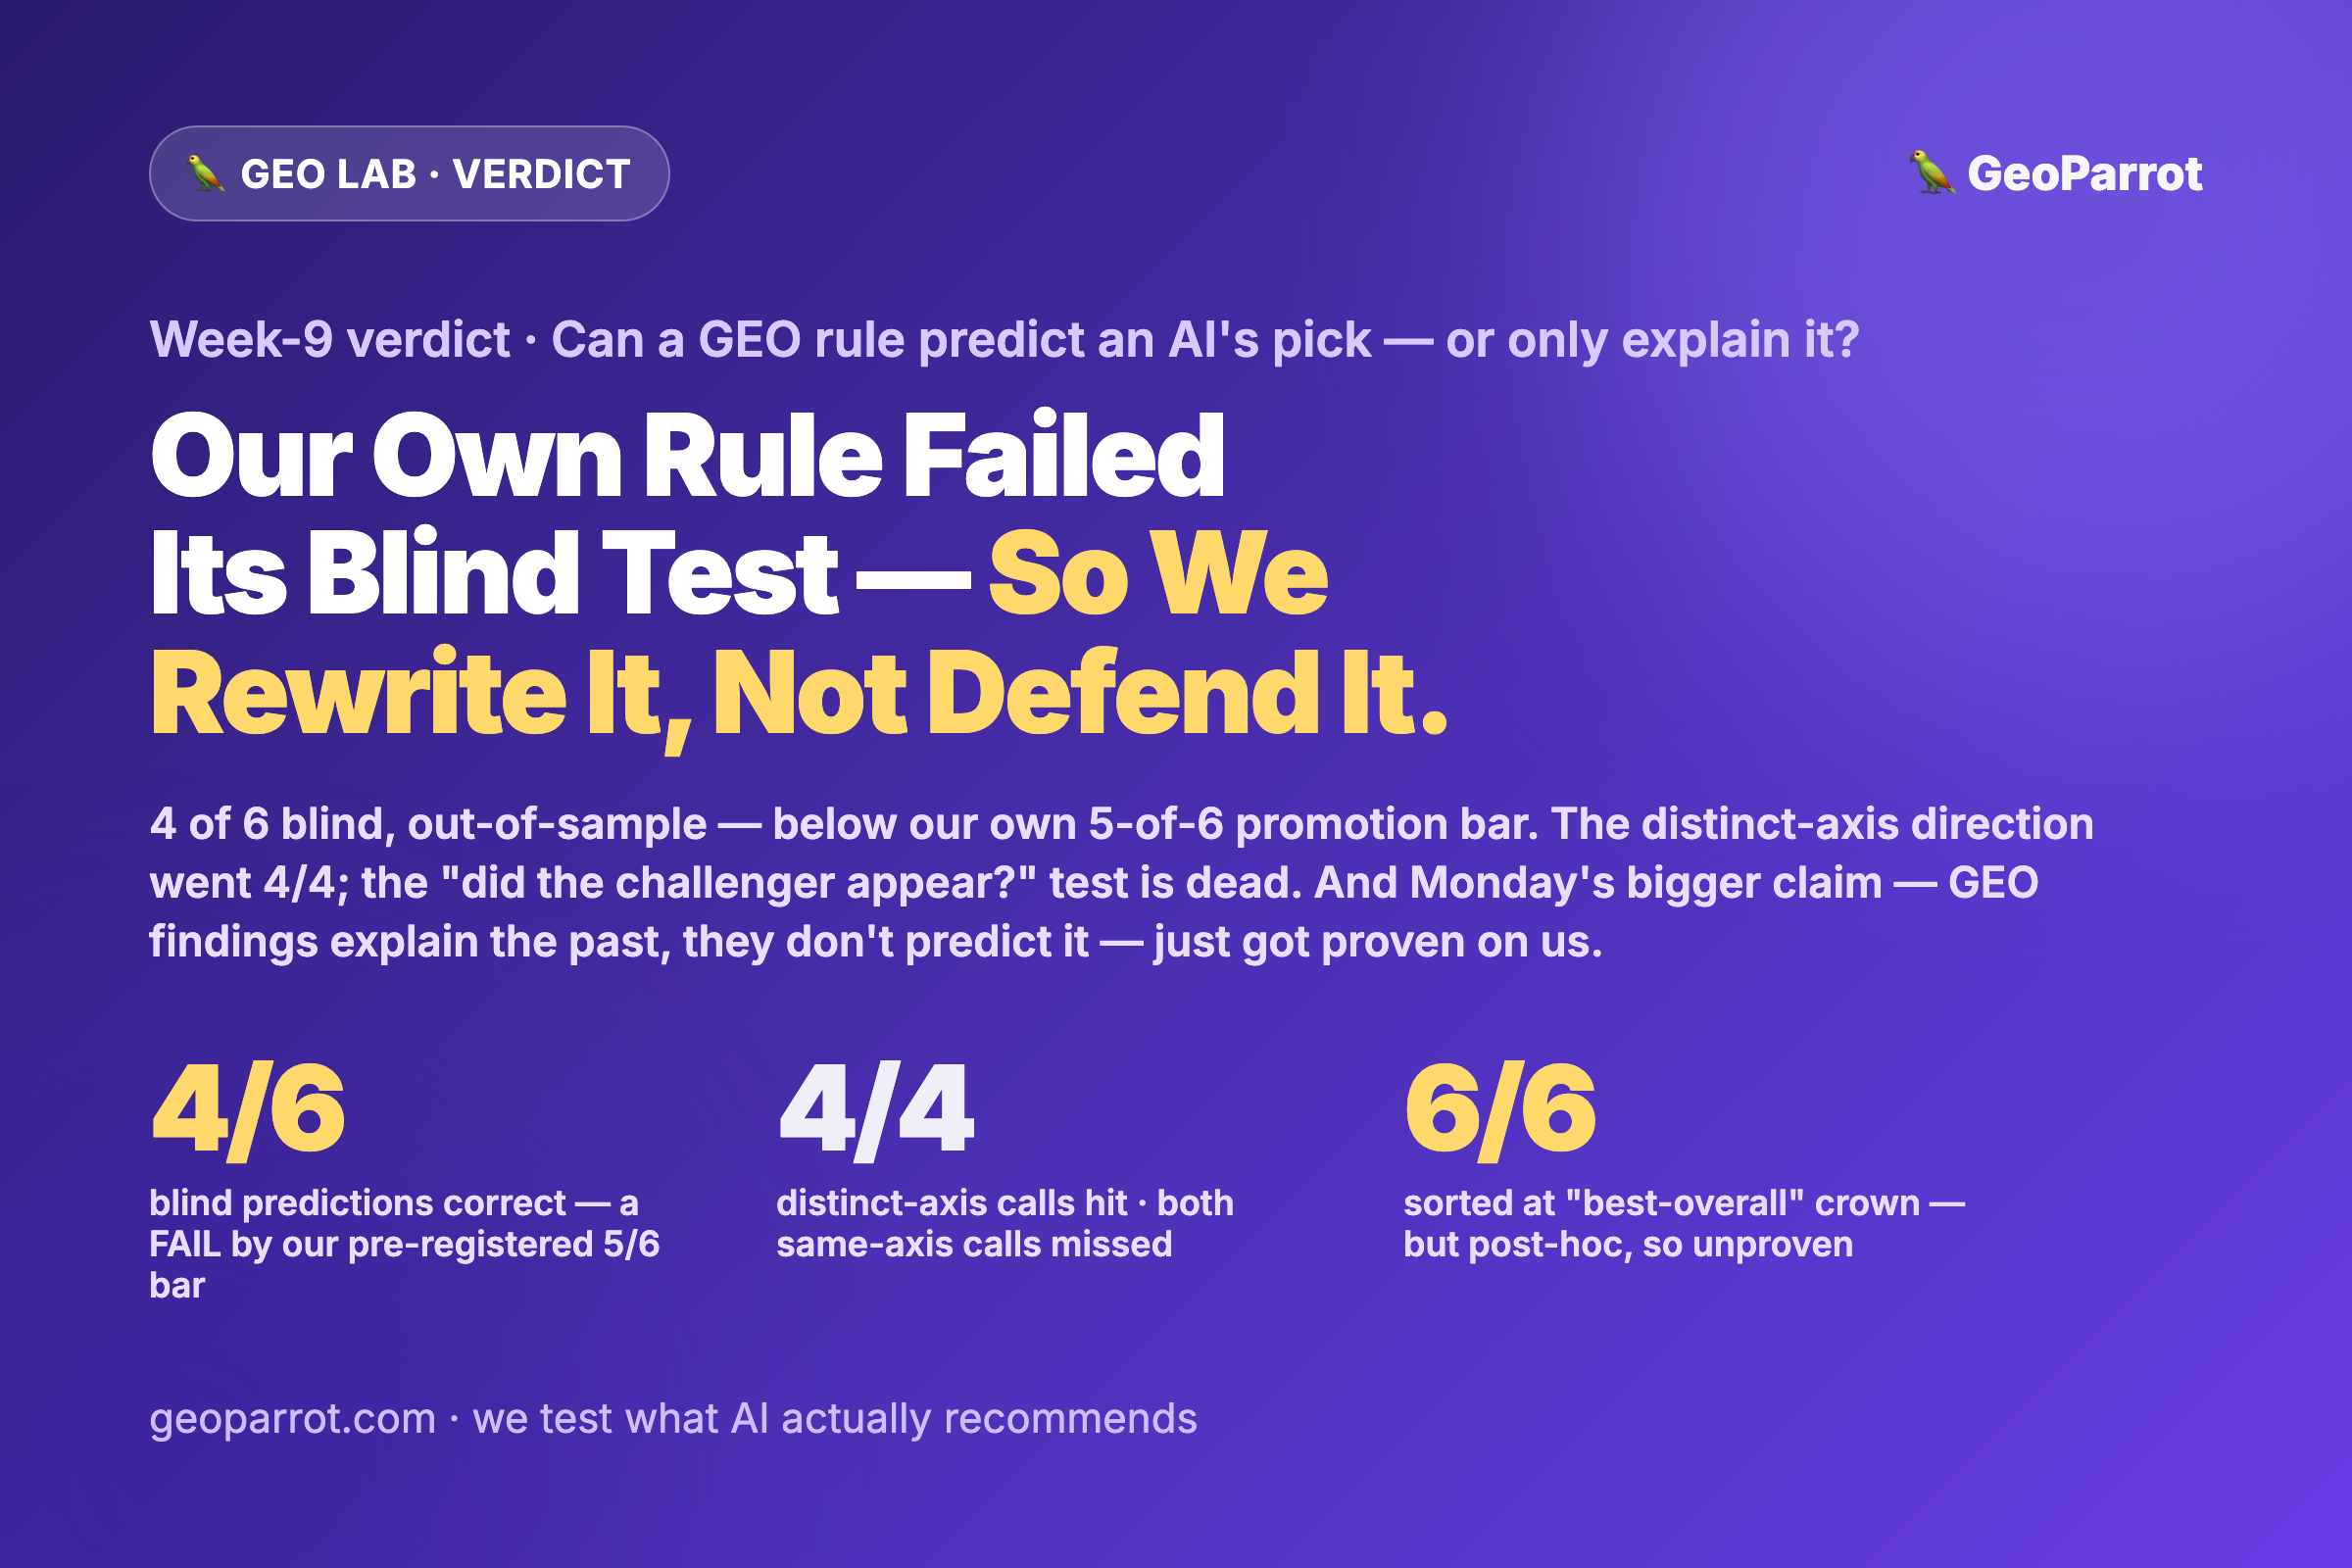
The Verdict: Our Geometry Rule Failed Its Own Blind Test at 4/6 — So We Rewrite It, Not Defend It. Monday’s Bigger Claim (GEO Findings Explain, They Don’t Predict) Just Got Proven on Us
All week we put our own geometry rule on the line: a challenger crosses the AI-search incumbency moat when it owns a distinct attribute axis, and stays held when it’s just a “better version” of the incumbent’s axis. We pre-registered 6 blind, out-of-sample predictions (4 CROSS, 2 HELD) with the pass line fixed in advance…
-
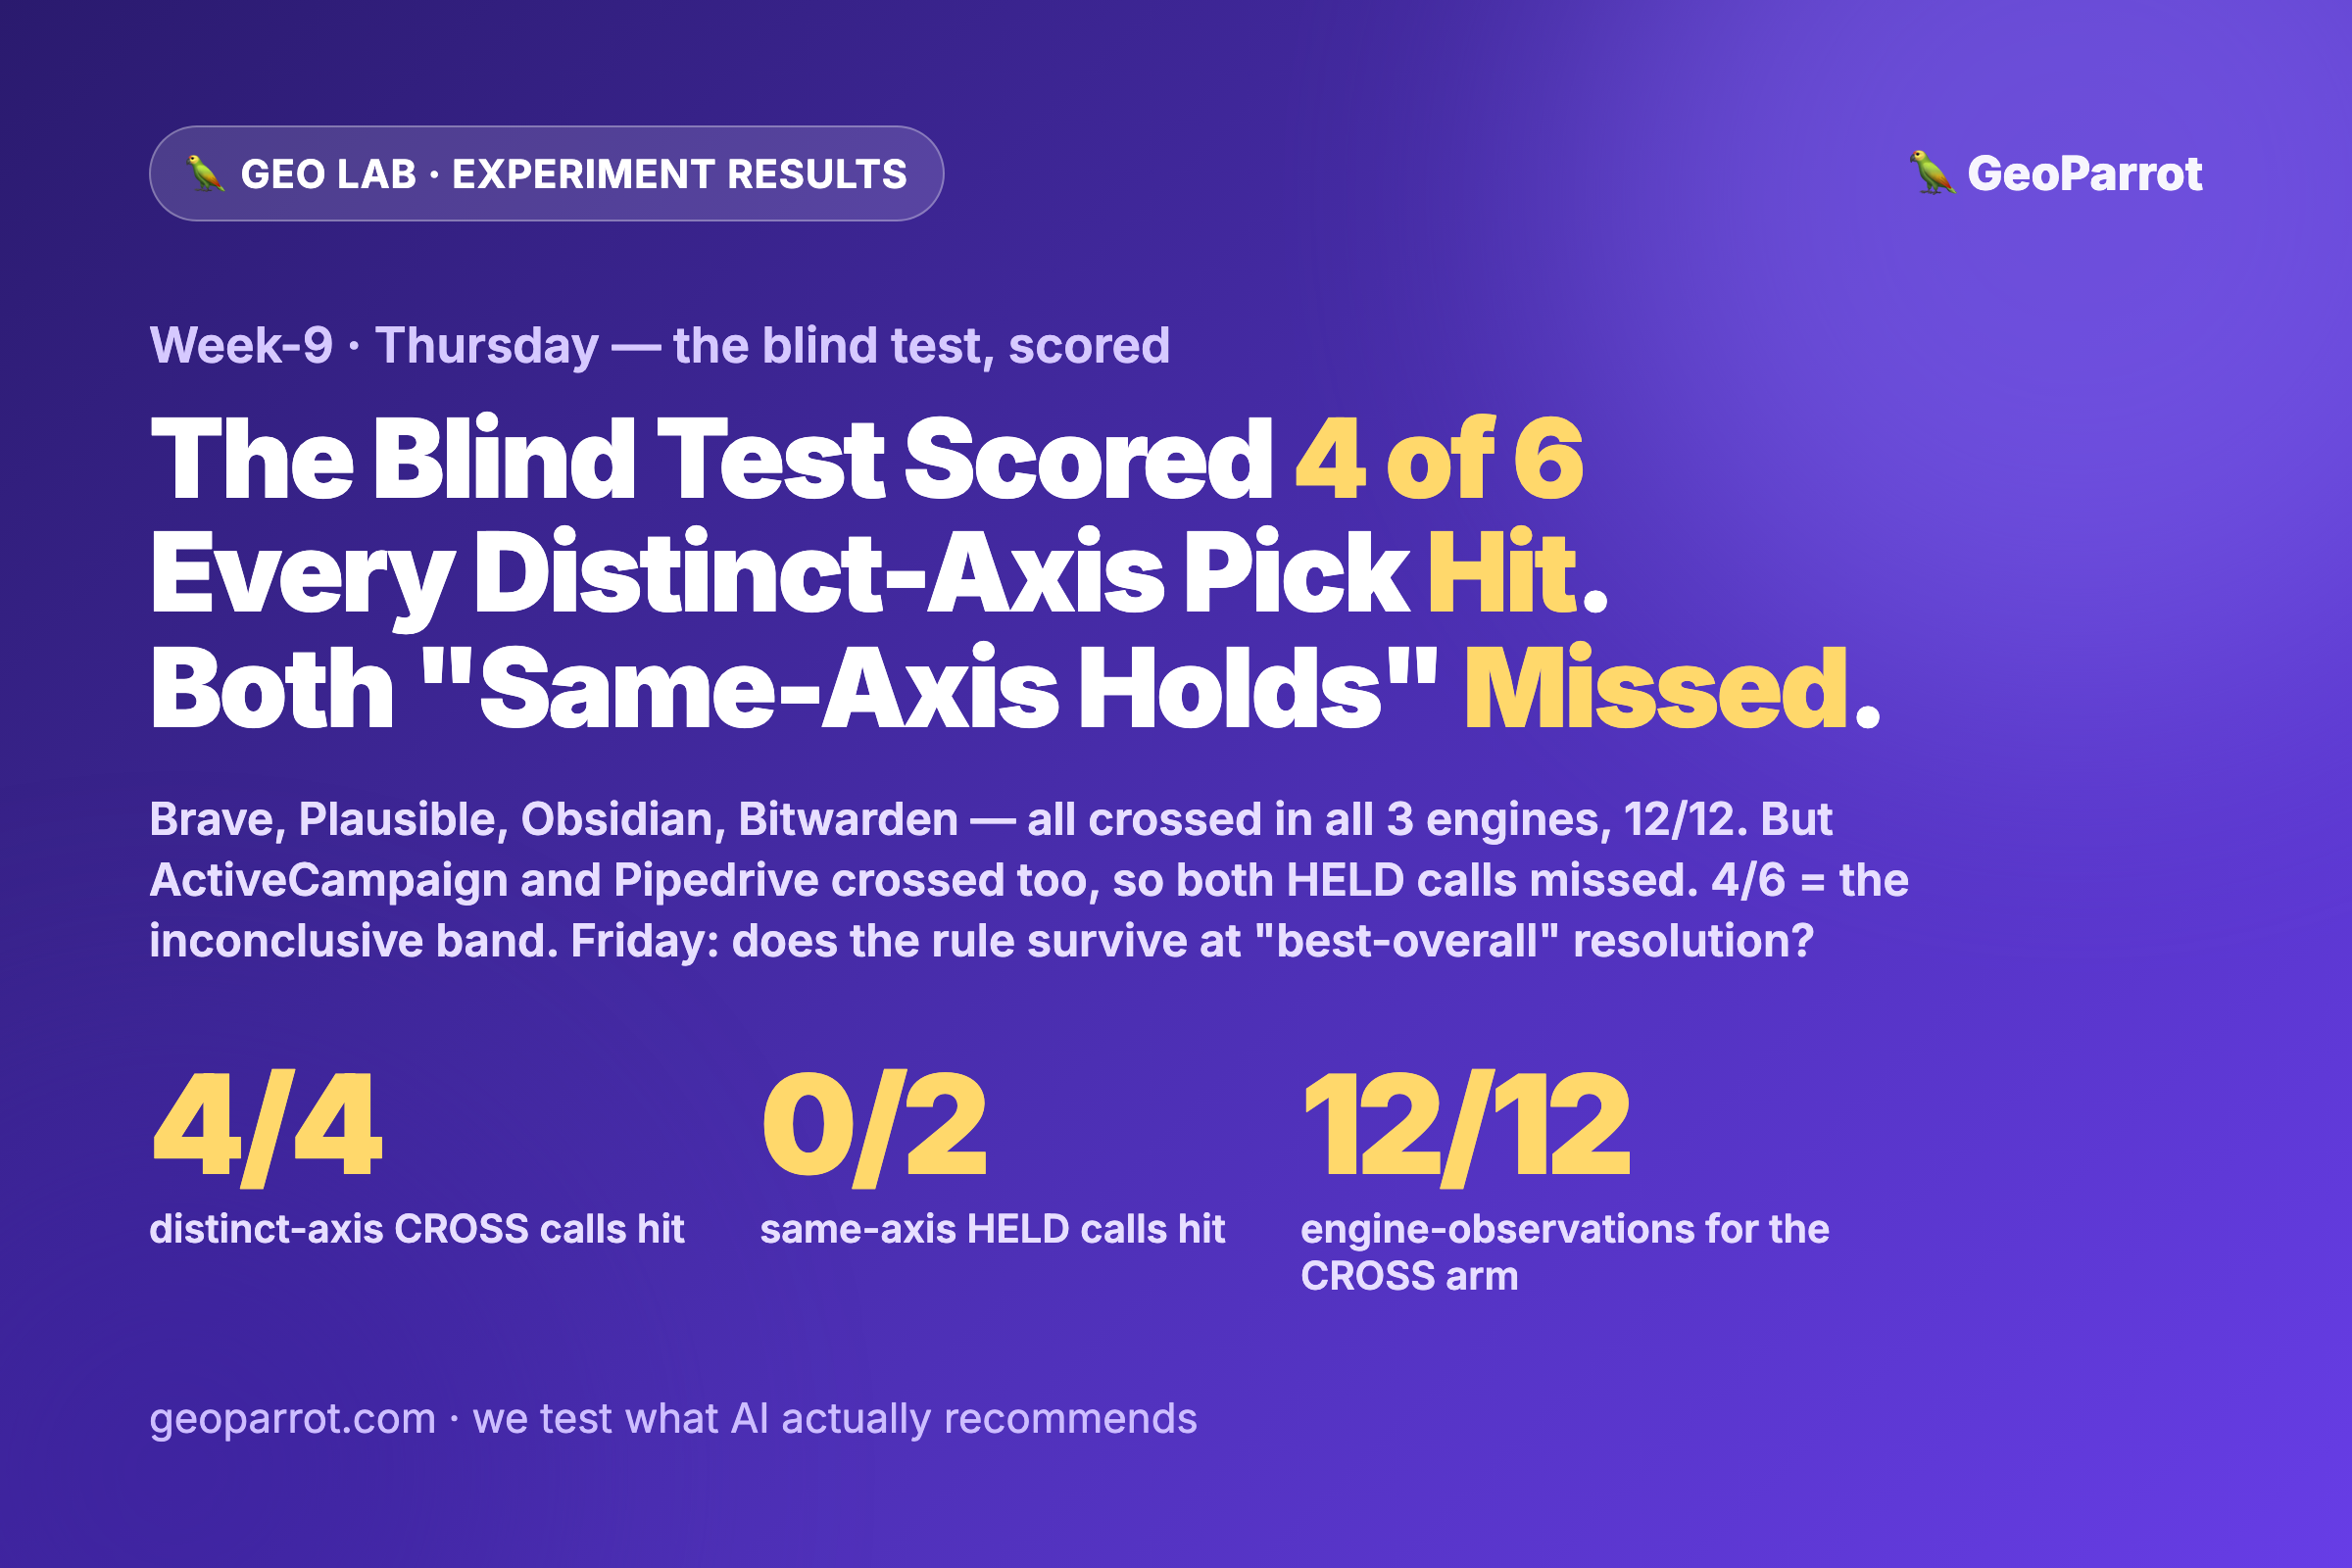
The Blind Test Scored 4 of 6: Our Geometry Rule Called Every Distinct-Axis Pick Correctly — and Missed Both “Same-Axis Holds” Because the Challenger Crossed Anyway
On Tuesday we locked 6 blind, out-of-sample predictions before querying a single engine: 4 said a distinct-axis challenger would cross into the AI’s recommendation set, 2 said a same-axis challenger would stay held. Today we queried ChatGPT, Perplexity, and Google AI Mode with a neutral “best [category] in 2026?” and scored against the frozen table.…
-
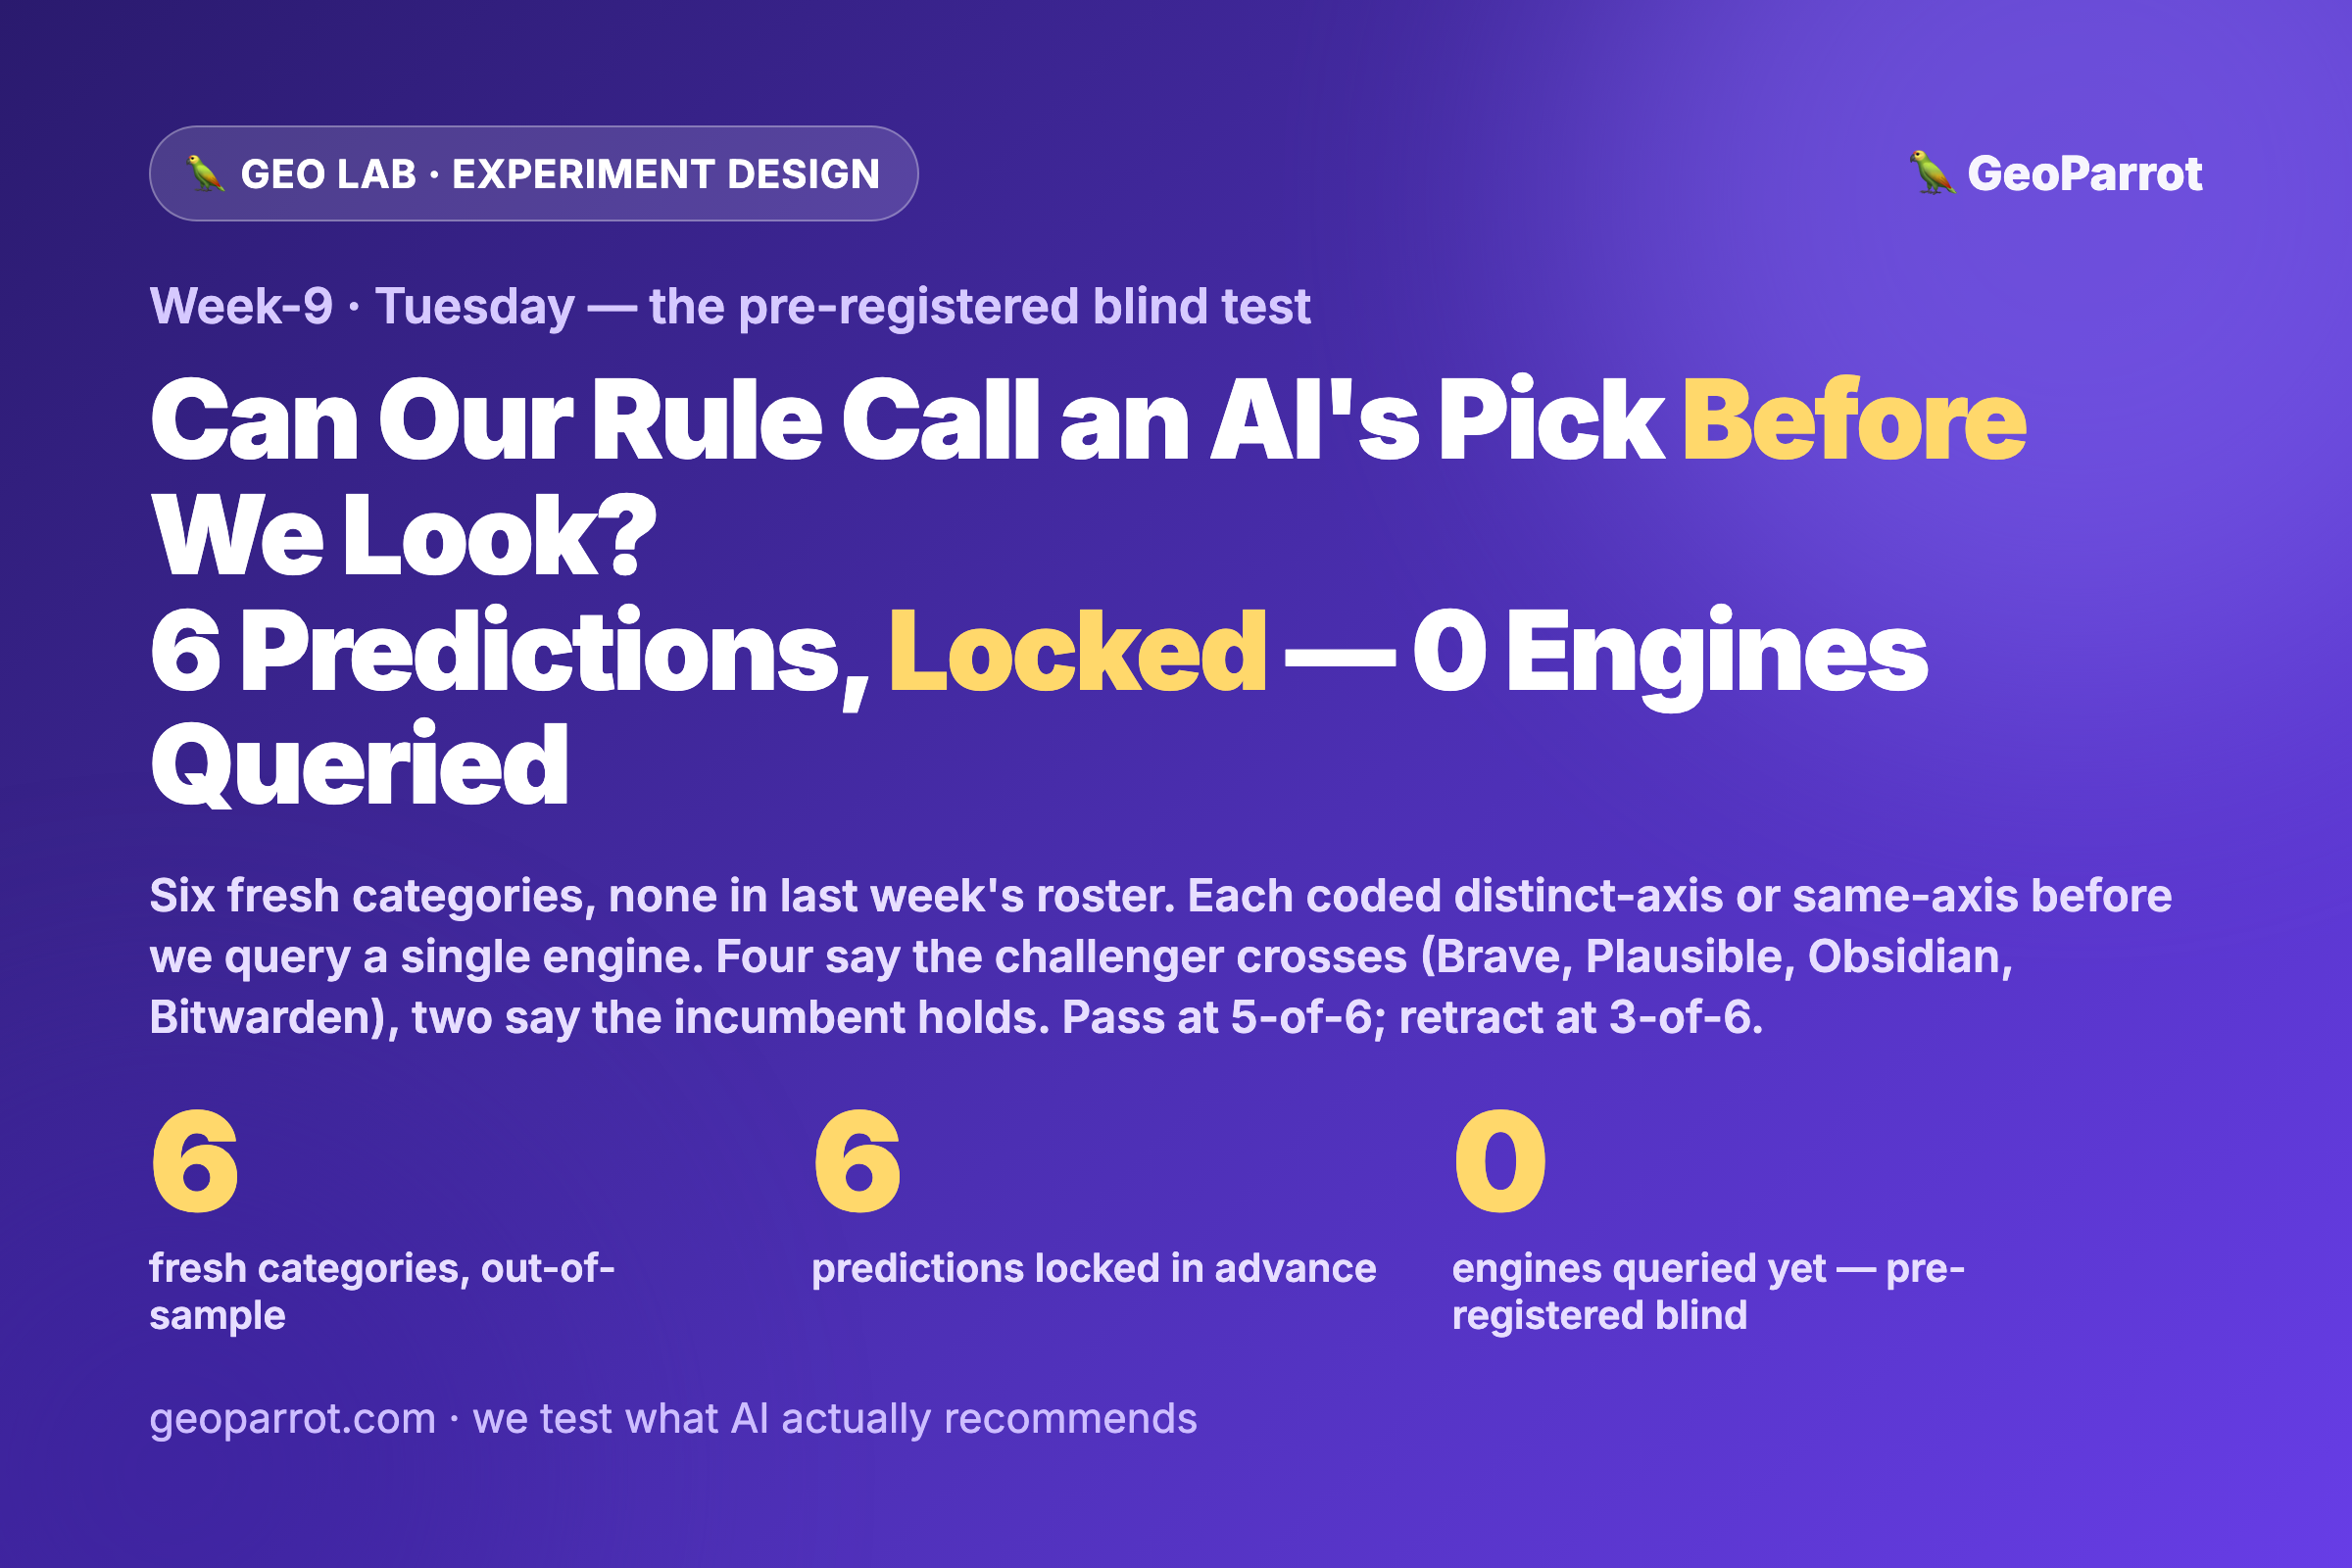
Can Our Geometry Rule Call an AI’s Pick Before We Look? We Pre-Register 6 Blind Predictions — Locked Here, Before a Single Engine Is Queried
Monday we admitted our own geometry-gate rule — a challenger crosses the AI-search incumbency moat when it owns a distinct attribute axis, and stays stuck when it’s a “better version” of the incumbent’s axis — fit last week’s data 6-for-6 only in hindsight: labels public, n=6, coded after we saw the picks. Today we put…
-
Most 2026 GEO “Findings” Explain the Past — They Don’t Predict. This Week We Test Whether Our Own Geometry Rule Can Call an AI’s Pick Before We Look
August 2026 produced a wave of impressive GEO studies — 680 million citations analyzed, a 46x brand-citation gap between ChatGPT (0.59%) and Perplexity (13.05%), 55+ data points on AI search behavior. All of it is real and useful, and almost all of it is retrodictive: it explains patterns in data already collected, correlationally, after the…
-
When Does an Earned Narrative Beat an Incumbent in AI Search? The Verdict: The Moat Is a Geometry Gate, Not a Size Threshold — Plus a Per-Category, Per-Engine Playbook
All week we hunted for the incumbency-moat threshold in AI search: how strong does an incumbent’s default have to be before a challenger’s earned narrative can’t cross it? The verdict on our frozen 6-category roster — zero engines re-queried — is that the threshold everyone looks for doesn’t exist. There is no size line. The…
-
The AI-Search Incumbency Moat Isn’t About the Incumbent’s Size — It’s the Challenger’s Narrative Axis. We Scored 6 Categories: Geometry 6-for-6, Magnitude Draws No Line
Tuesday we pre-registered two rival explanations for why a challenger crosses the AI-search incumbency moat in some categories and not others: the incumbent’s SIZE (magnitude) or the challenger’s NARRATIVE AXIS (geometry). We scored all 6 frozen categories with zero engine re-queries — and all four pre-registered predictions held. Magnitude drew no line: the biggest size…
-
Can a Challenger Earn Narrative Ownership — or Is It Locked in Category History? The Verdict: Earnable, But It Won’t Buy You the Pick
This week’s GEO Lab ran a natural experiment on our frozen 18-brand roster — zero engines re-queried — to settle one question: can a challenger deliberately EARN ownership of its category’s defining narrative, or is that ownership locked in category history (age, size, being the incumbent)? The verdict on our first-party data: earnable, but not…
-
Where’s the Incumbency Moat Threshold in AI Search — the Incumbent’s Size, or the Challenger’s Narrative Axis? Our Pre-Registered Test
Monday we said AI search is only “half” a level playing field — the old moats (domain authority, backlinks) dissolved, but a new one survived: being the category’s default narrative. Two of our six frozen categories saw a challenger cross that moat (a smaller/younger brand became the AI’s #1 pick); four held. This week’s question…
-
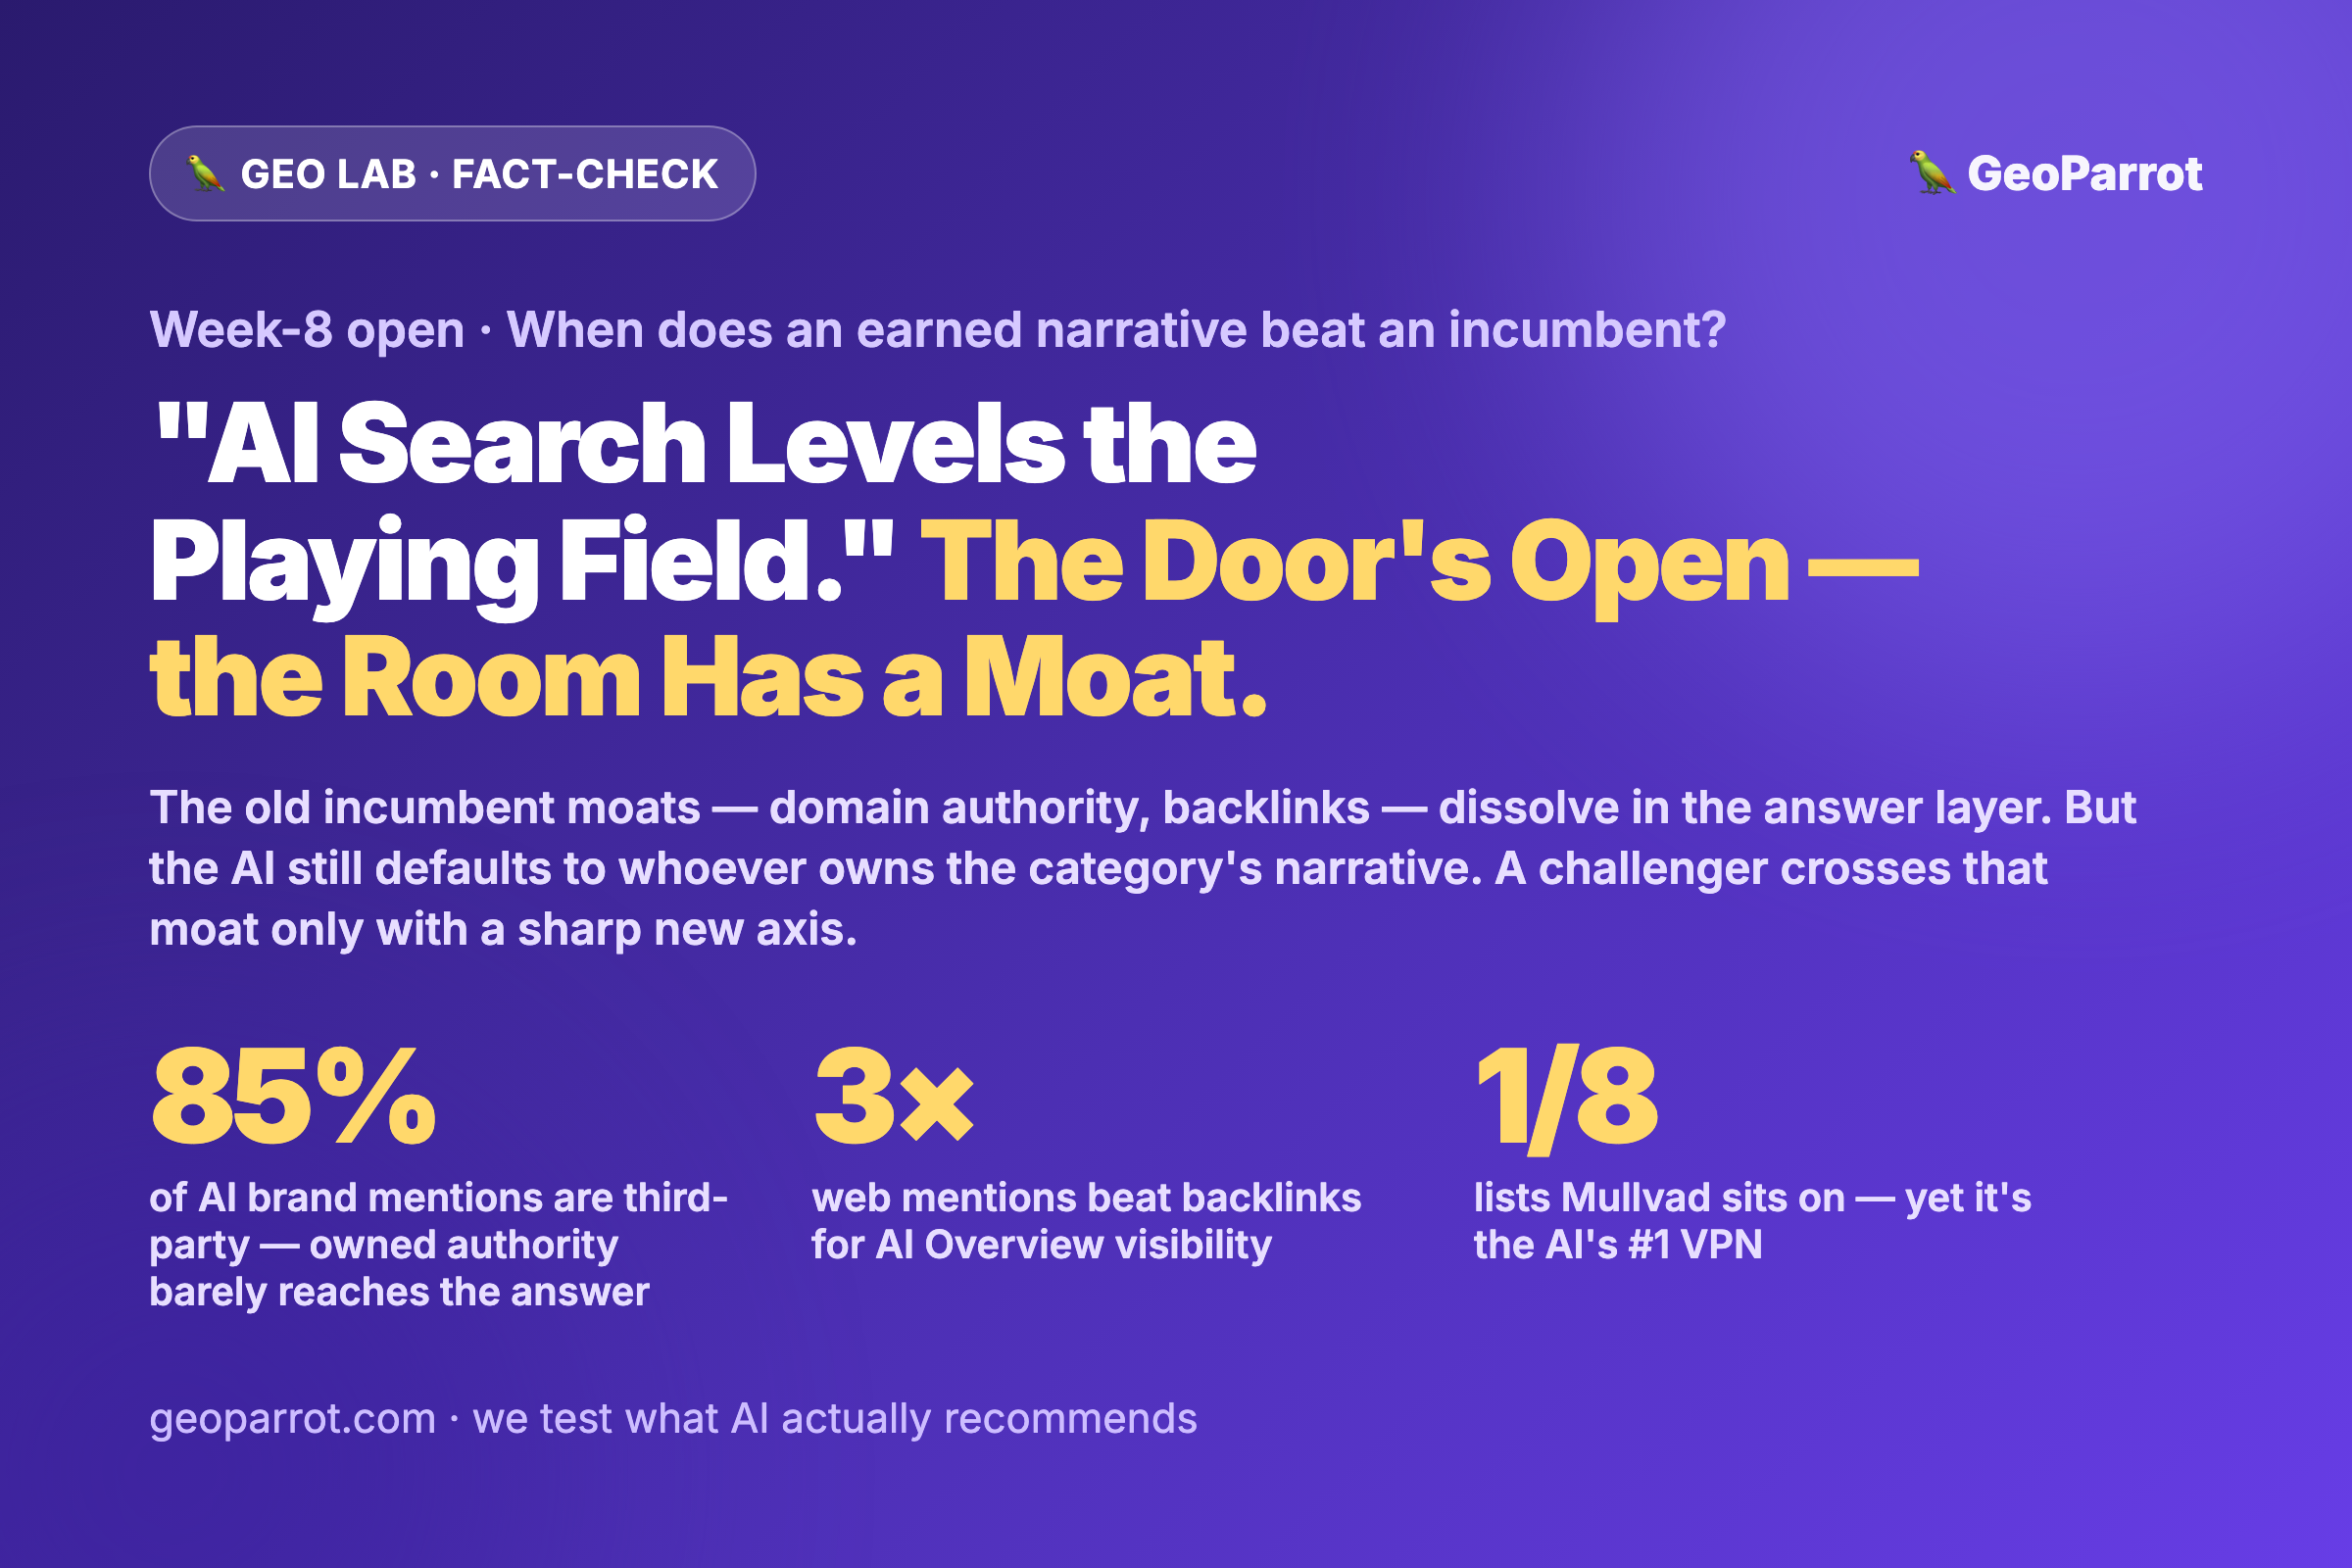
“AI Search Levels the Playing Field for Challengers.” Half True — Our Data Says There’s an Incumbency Moat, and Earned Narrative Crosses It Only Sometimes
The loudest optimistic GEO claim of August 2026 is that AI search levels the playing field — a “huge opportunity for challenger brands” now that answers are built from third-party text instead of owned domain authority. Half of that is real and new: about 85% of AI brand mentions come from third-party pages, brands are…
-
Can a Challenger Deliberately Earn Narrative Ownership — or Is It Locked in Category History? Our Pre-Registered Causal Test
Monday we showed earned media is a floor a challenger must clear, but raw mention volume predicted the AI’s #1 pick only 1 of 6 times — what out-predicted it 4-to-1 was narrative ownership, owning the language of the category. That’s a correlation. This week’s question is causal: can a challenger deliberately build that ownership,…