Category: Uncategorized
-
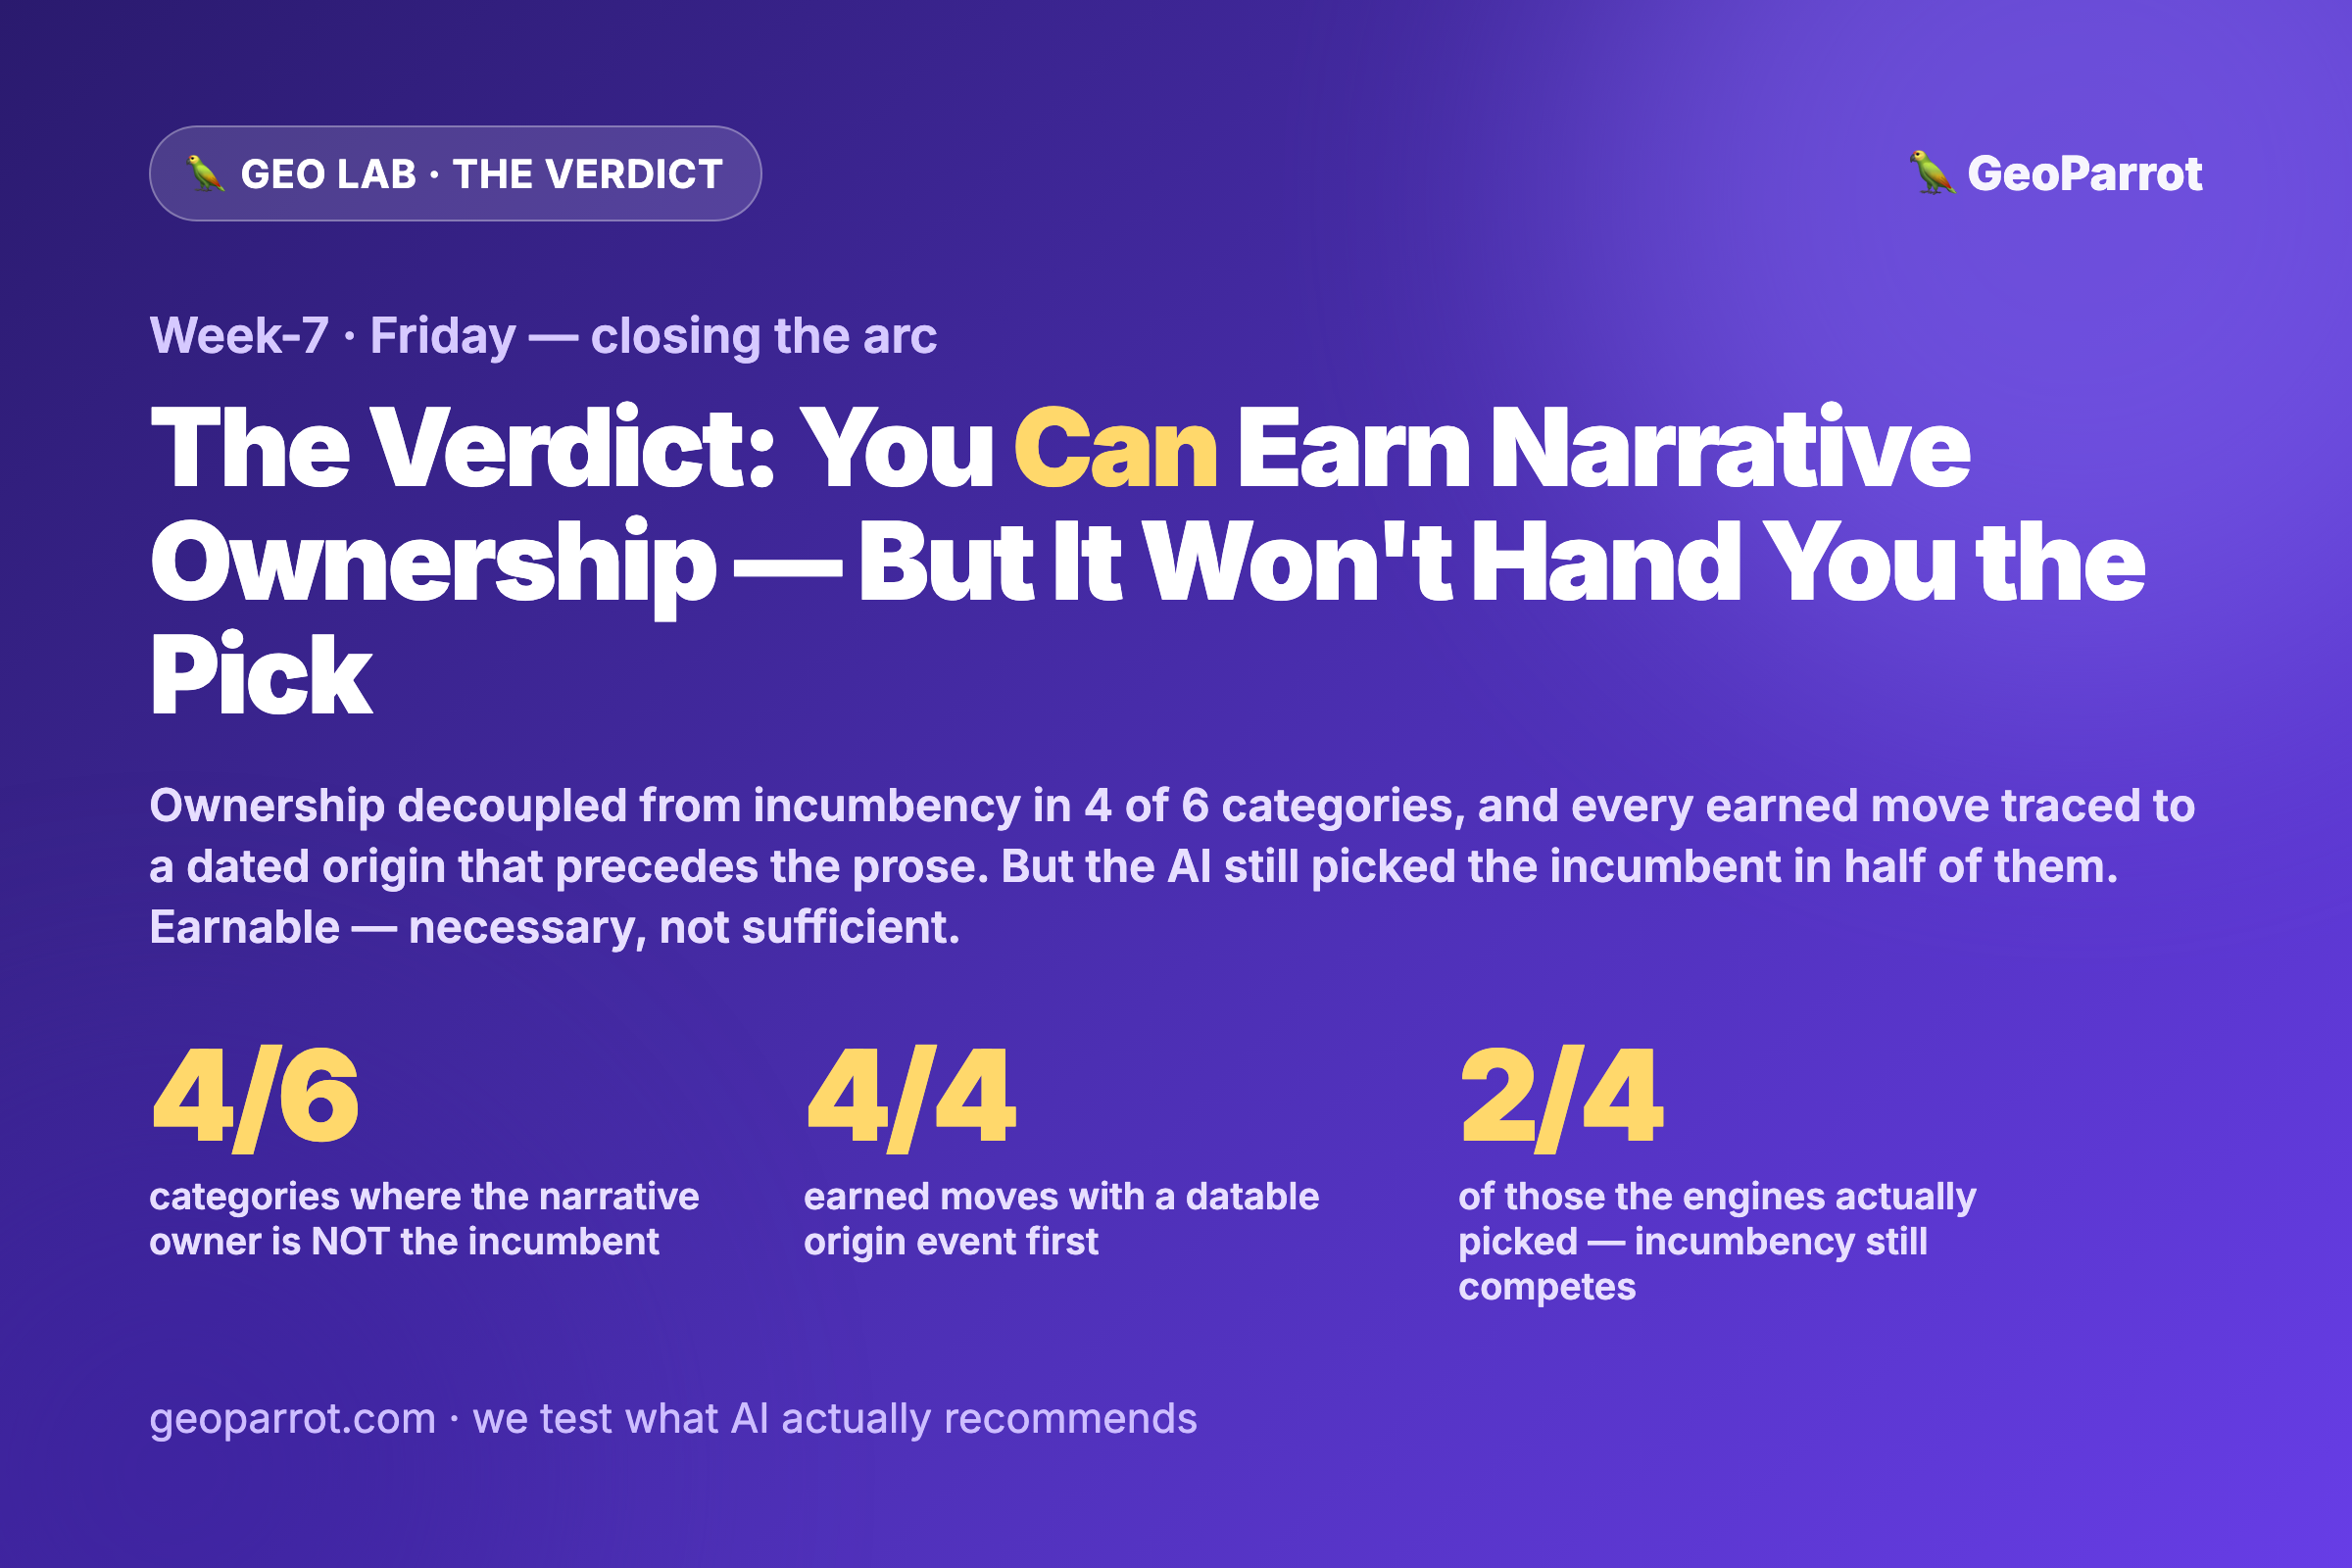
Can a Challenger Earn Narrative Ownership — or Is It Locked in Category History? The Verdict: Earnable, But It Won’t Buy You the Pick
This week’s GEO Lab ran a natural experiment on our frozen 18-brand roster — zero engines re-queried — to settle one question: can a challenger deliberately EARN ownership of its category’s defining narrative, or is that ownership locked in category history (age, size, being the incumbent)? The verdict on our first-party data: earnable, but not…
-
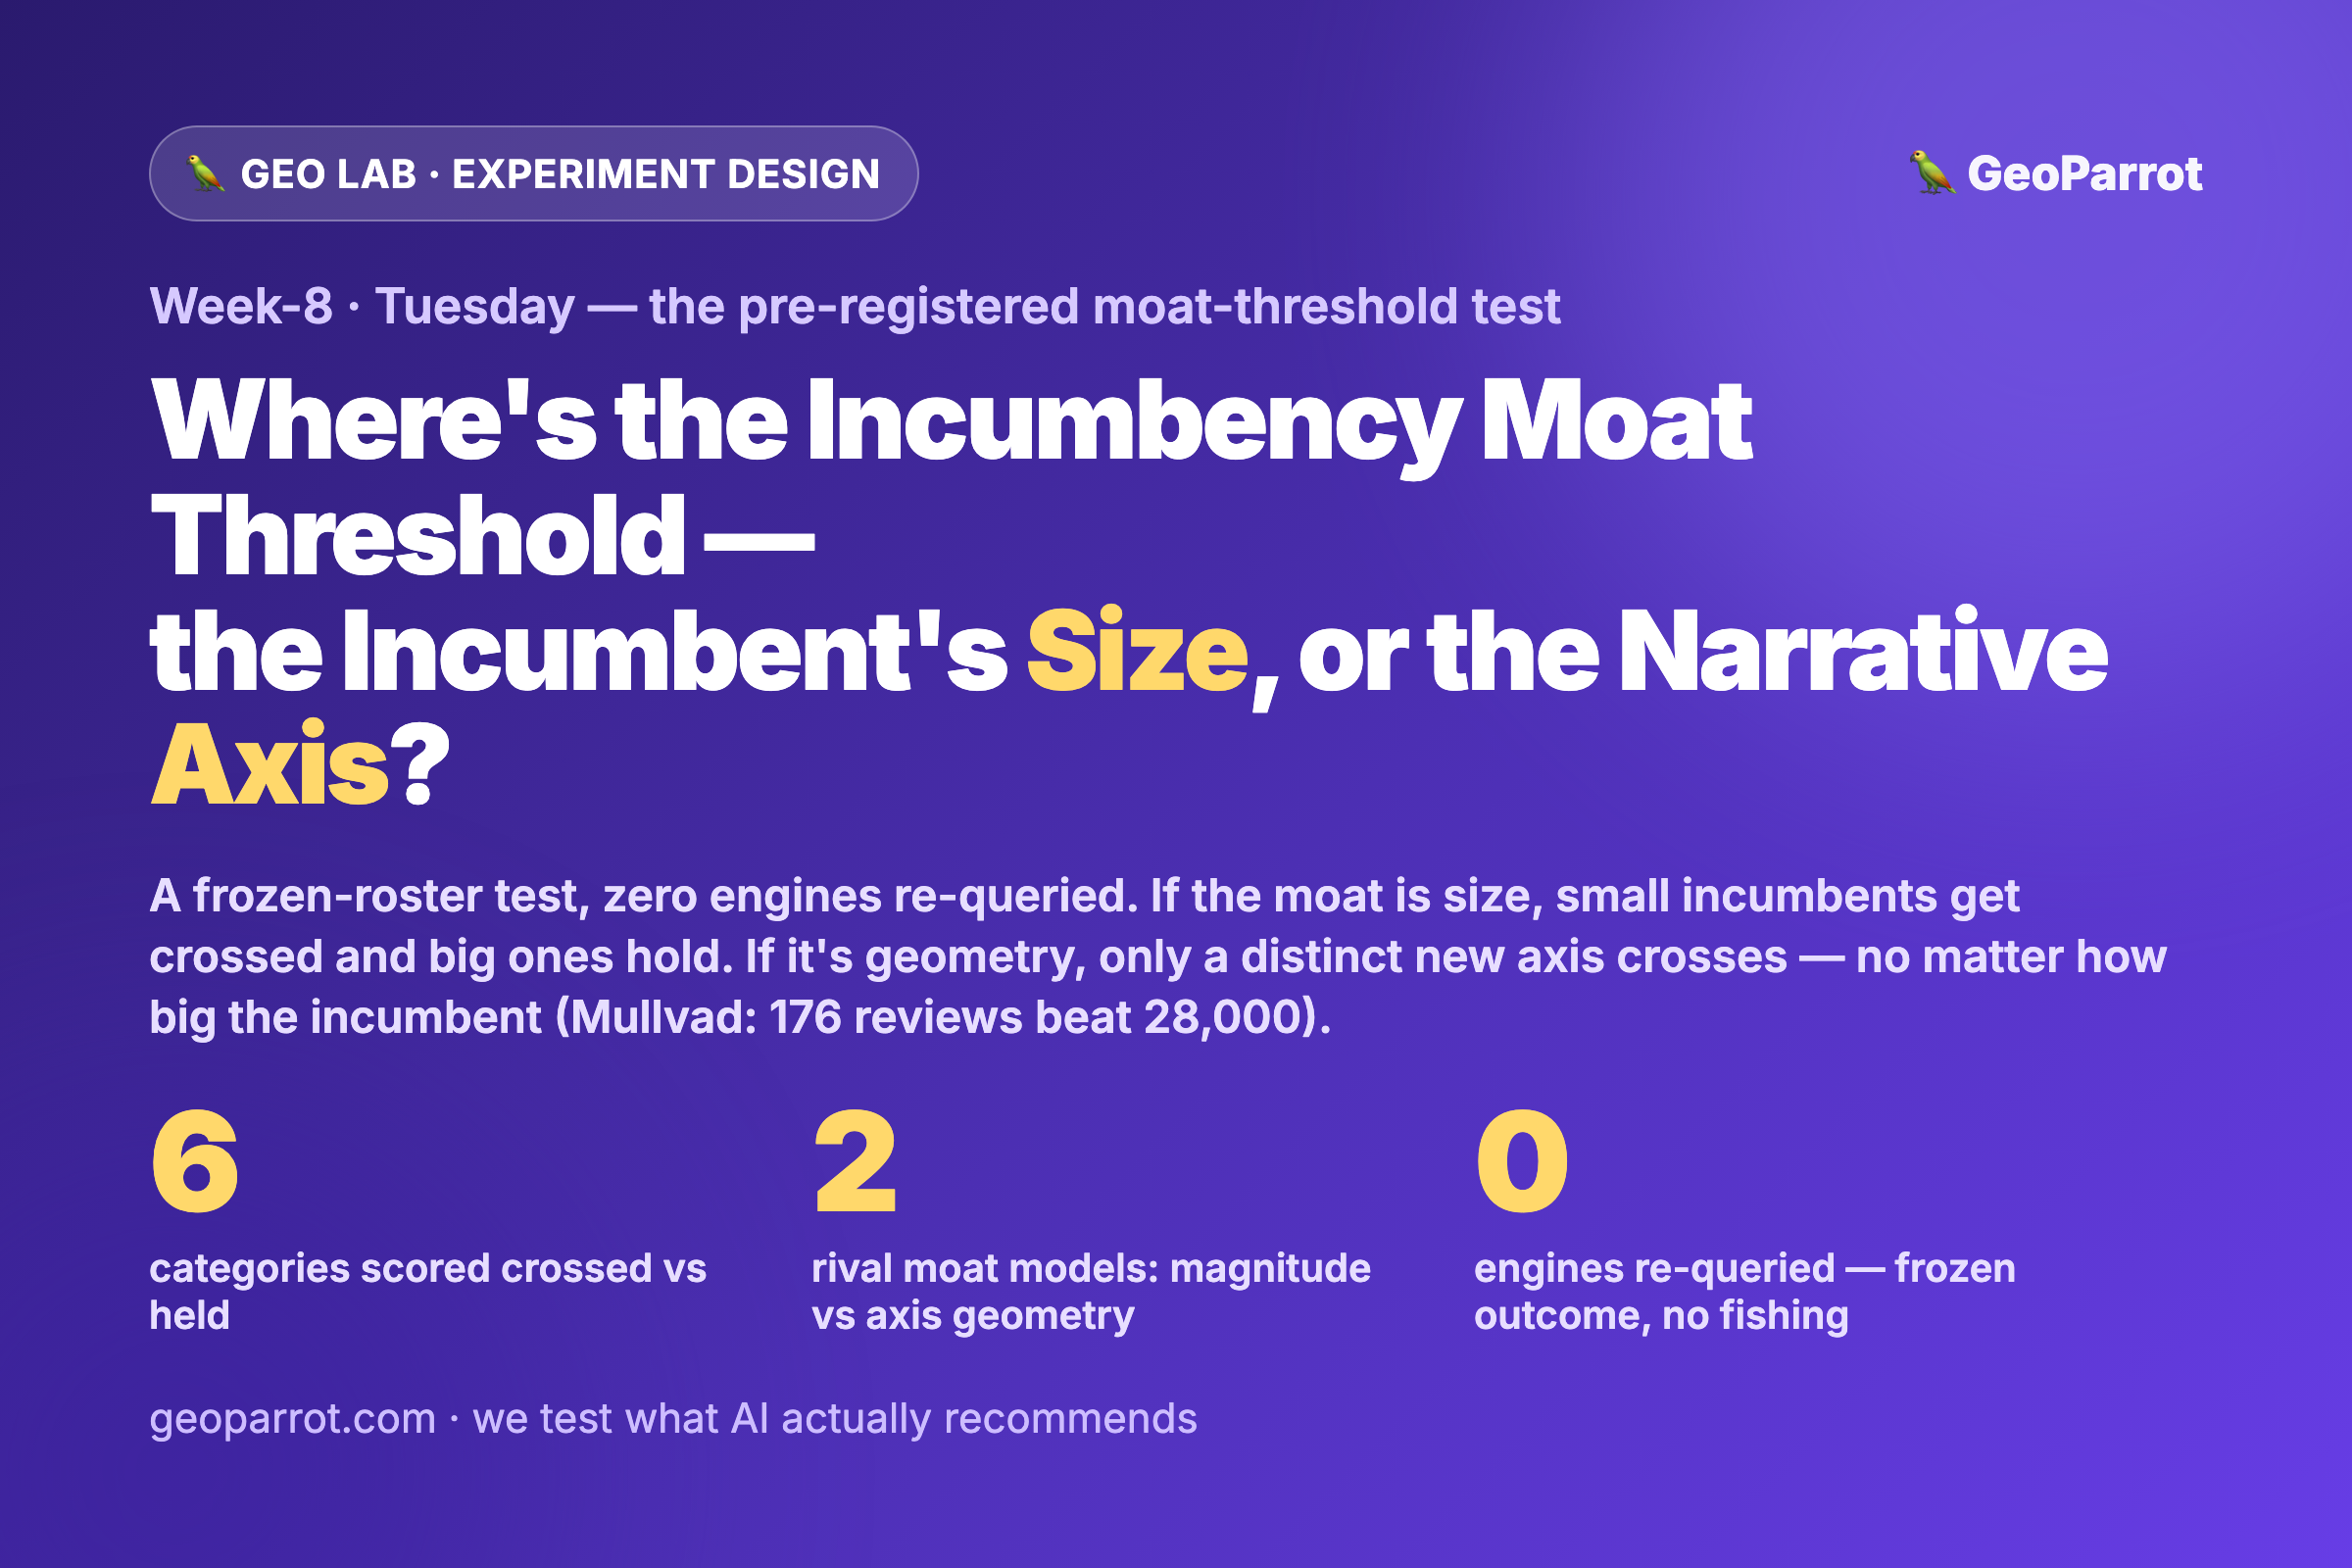
Where’s the Incumbency Moat Threshold in AI Search — the Incumbent’s Size, or the Challenger’s Narrative Axis? Our Pre-Registered Test
Monday we said AI search is only “half” a level playing field — the old moats (domain authority, backlinks) dissolved, but a new one survived: being the category’s default narrative. Two of our six frozen categories saw a challenger cross that moat (a smaller/younger brand became the AI’s #1 pick); four held. This week’s question…
-
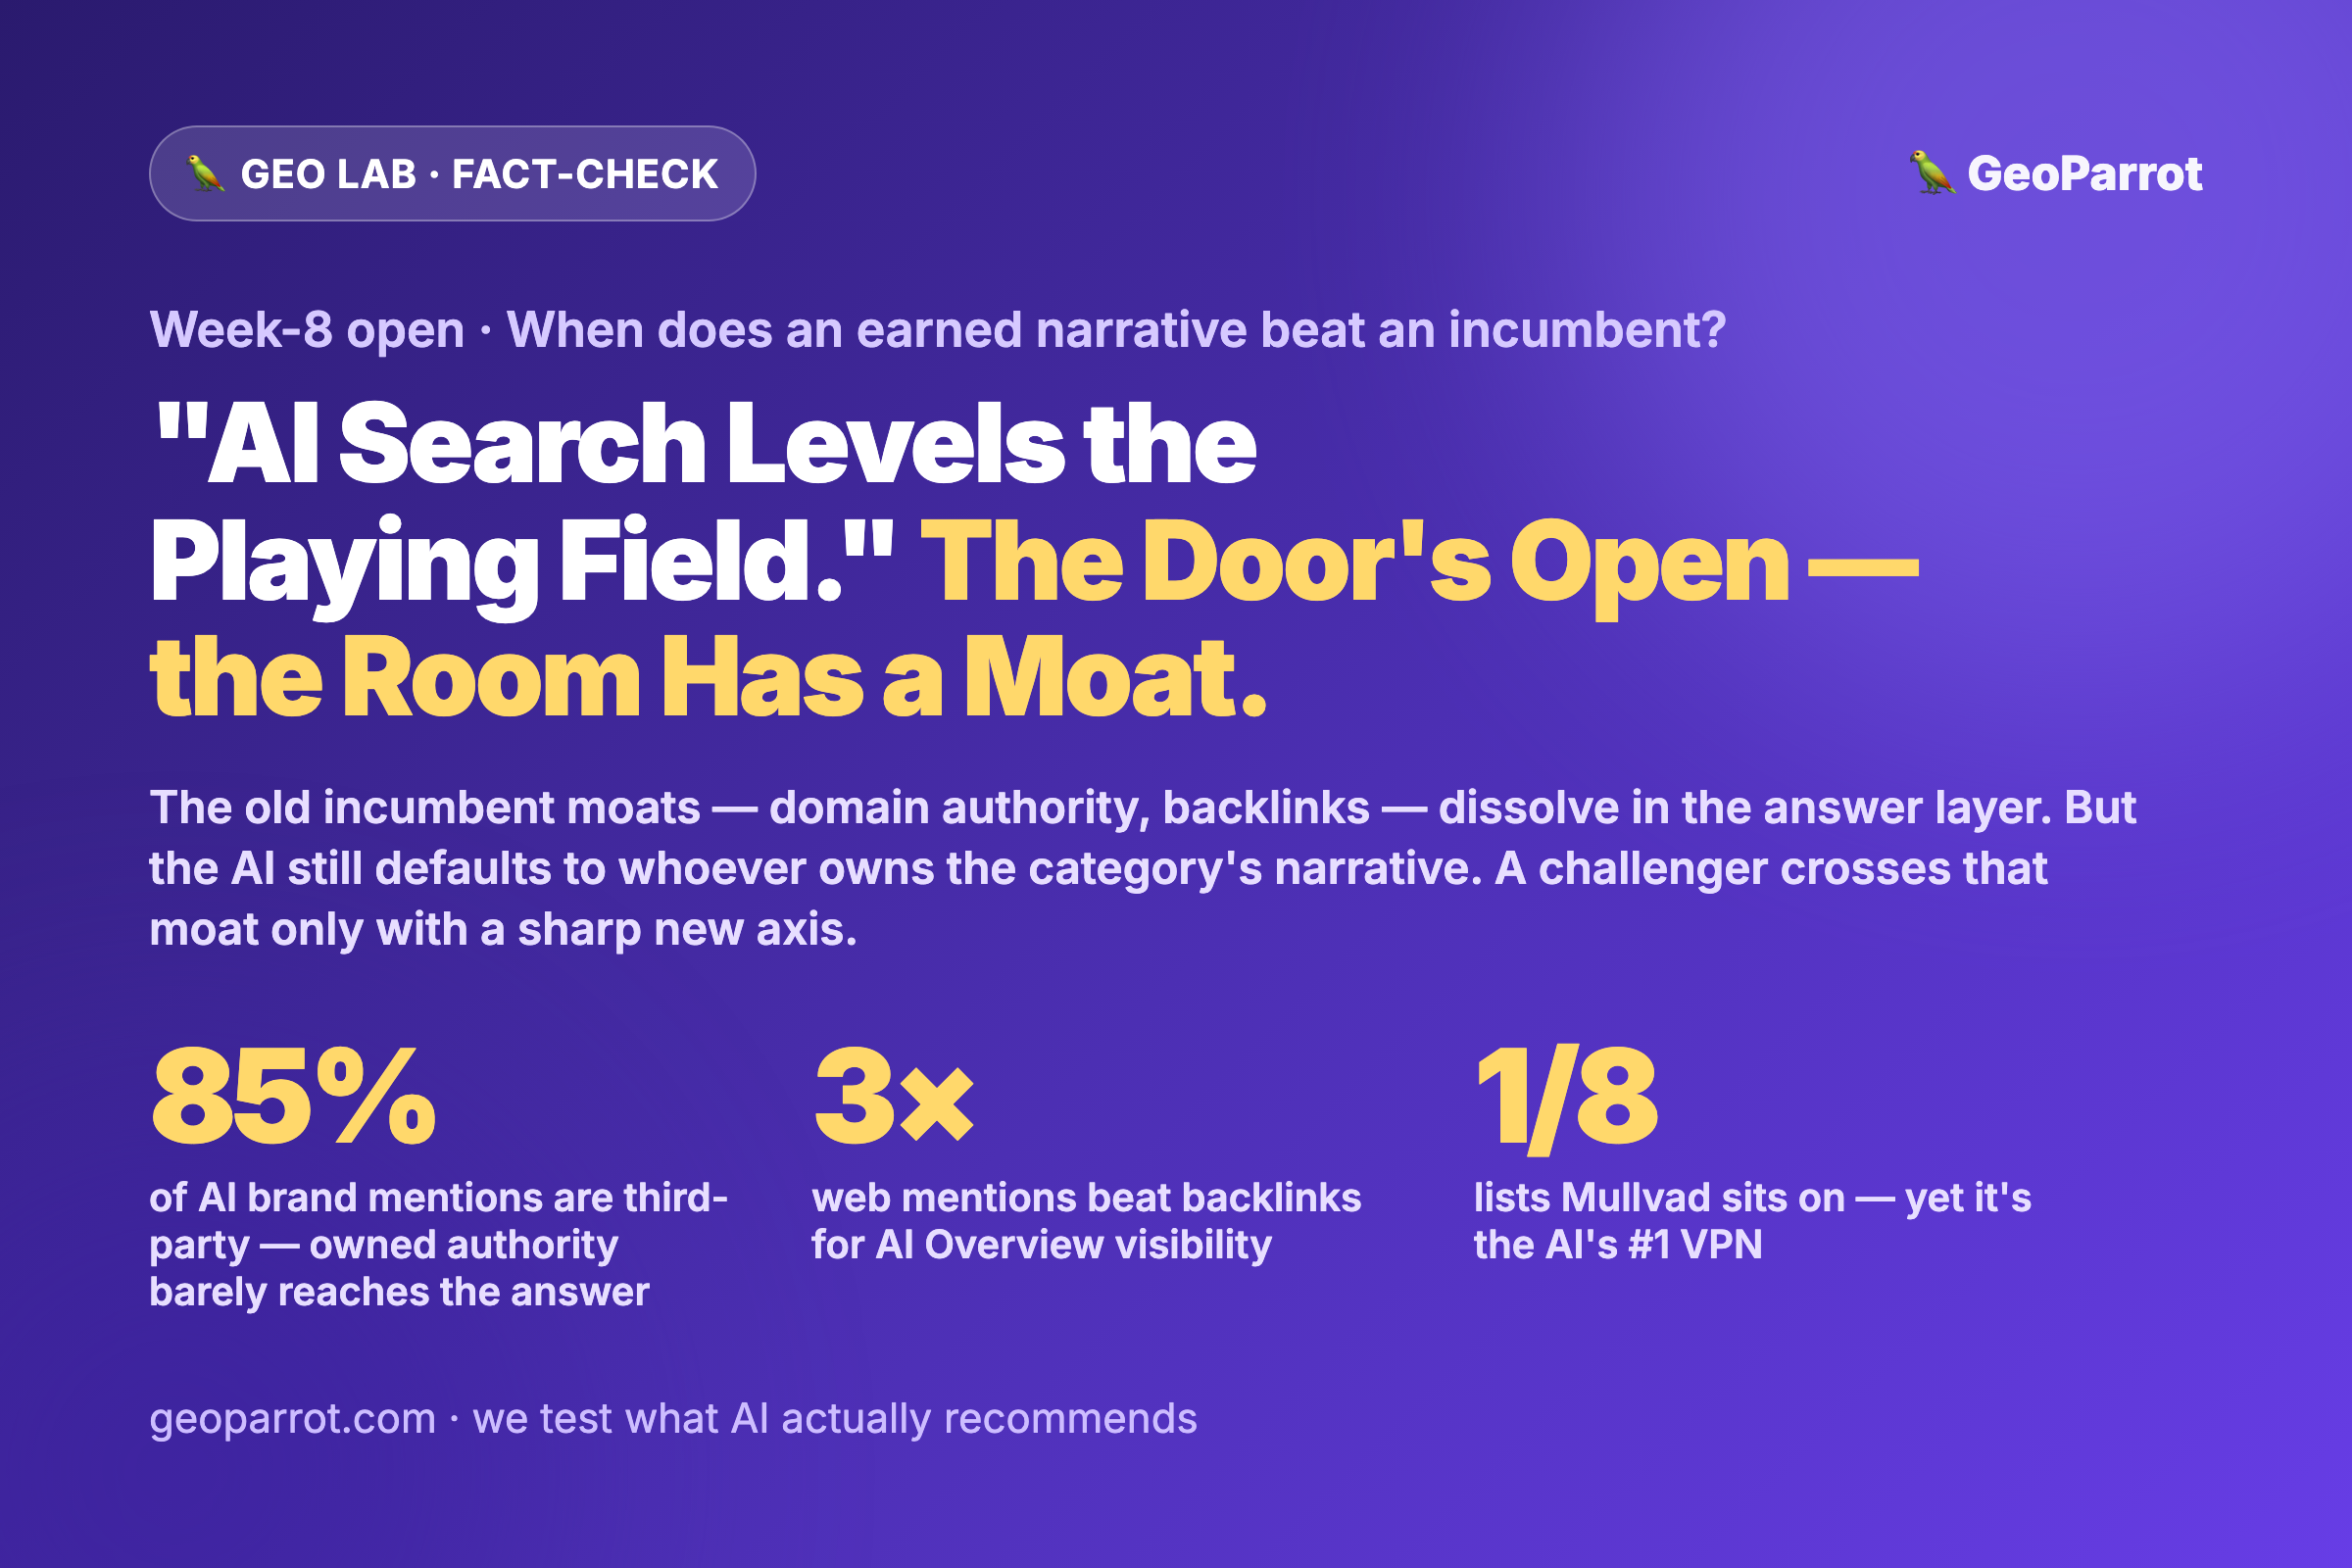
“AI Search Levels the Playing Field for Challengers.” Half True — Our Data Says There’s an Incumbency Moat, and Earned Narrative Crosses It Only Sometimes
The loudest optimistic GEO claim of August 2026 is that AI search levels the playing field — a “huge opportunity for challenger brands” now that answers are built from third-party text instead of owned domain authority. Half of that is real and new: about 85% of AI brand mentions come from third-party pages, brands are…
-
Can a Challenger Deliberately Earn Narrative Ownership — or Is It Locked in Category History? Our Pre-Registered Causal Test
Monday we showed earned media is a floor a challenger must clear, but raw mention volume predicted the AI’s #1 pick only 1 of 6 times — what out-predicted it 4-to-1 was narrative ownership, owning the language of the category. That’s a correlation. This week’s question is causal: can a challenger deliberately build that ownership,…
-
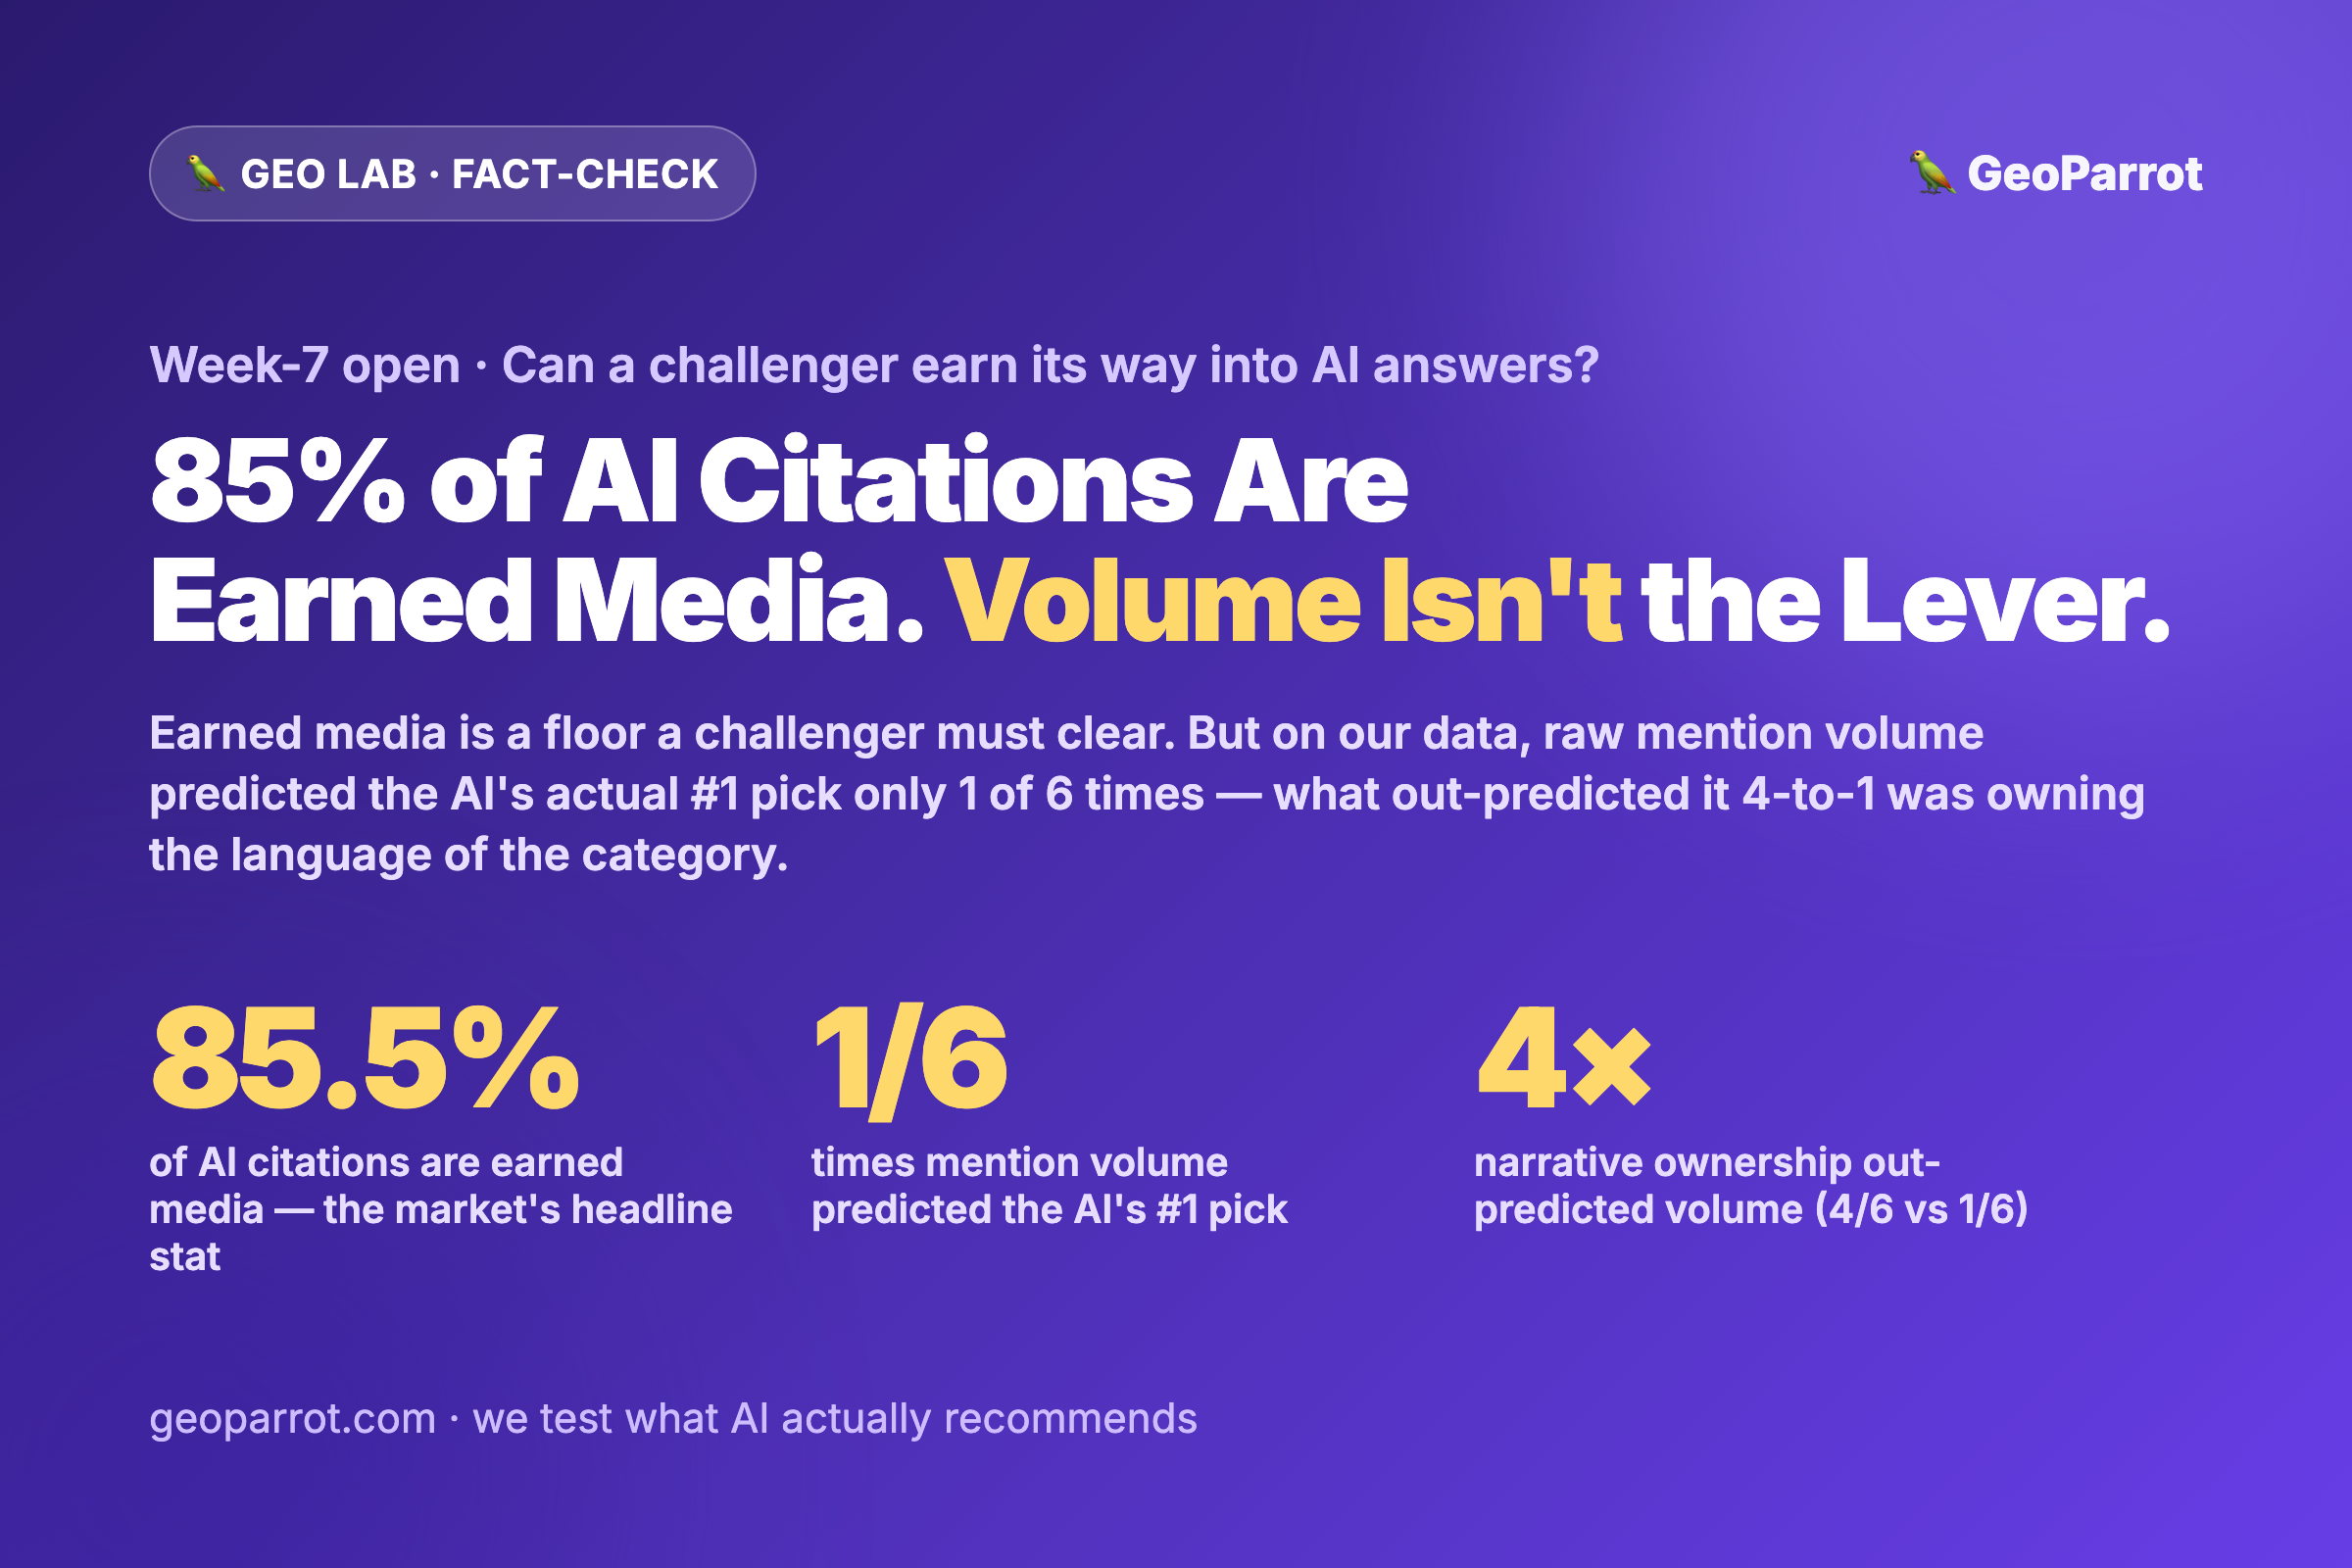
“85% of AI Citations Are Earned Media.” So Can a Challenger Just PR Its Way to the #1 AI Pick?
The loudest GEO claim of 2026 is that AI visibility is bought with earned media: Muck Rack found 85.5% of AI citations come from earned sources, University of Toronto measured earned cited ~5x more than owned, and a Stacker/Scrunch study lifted an article’s citation rate from 8% to 34% just by distributing it to third-party…
-
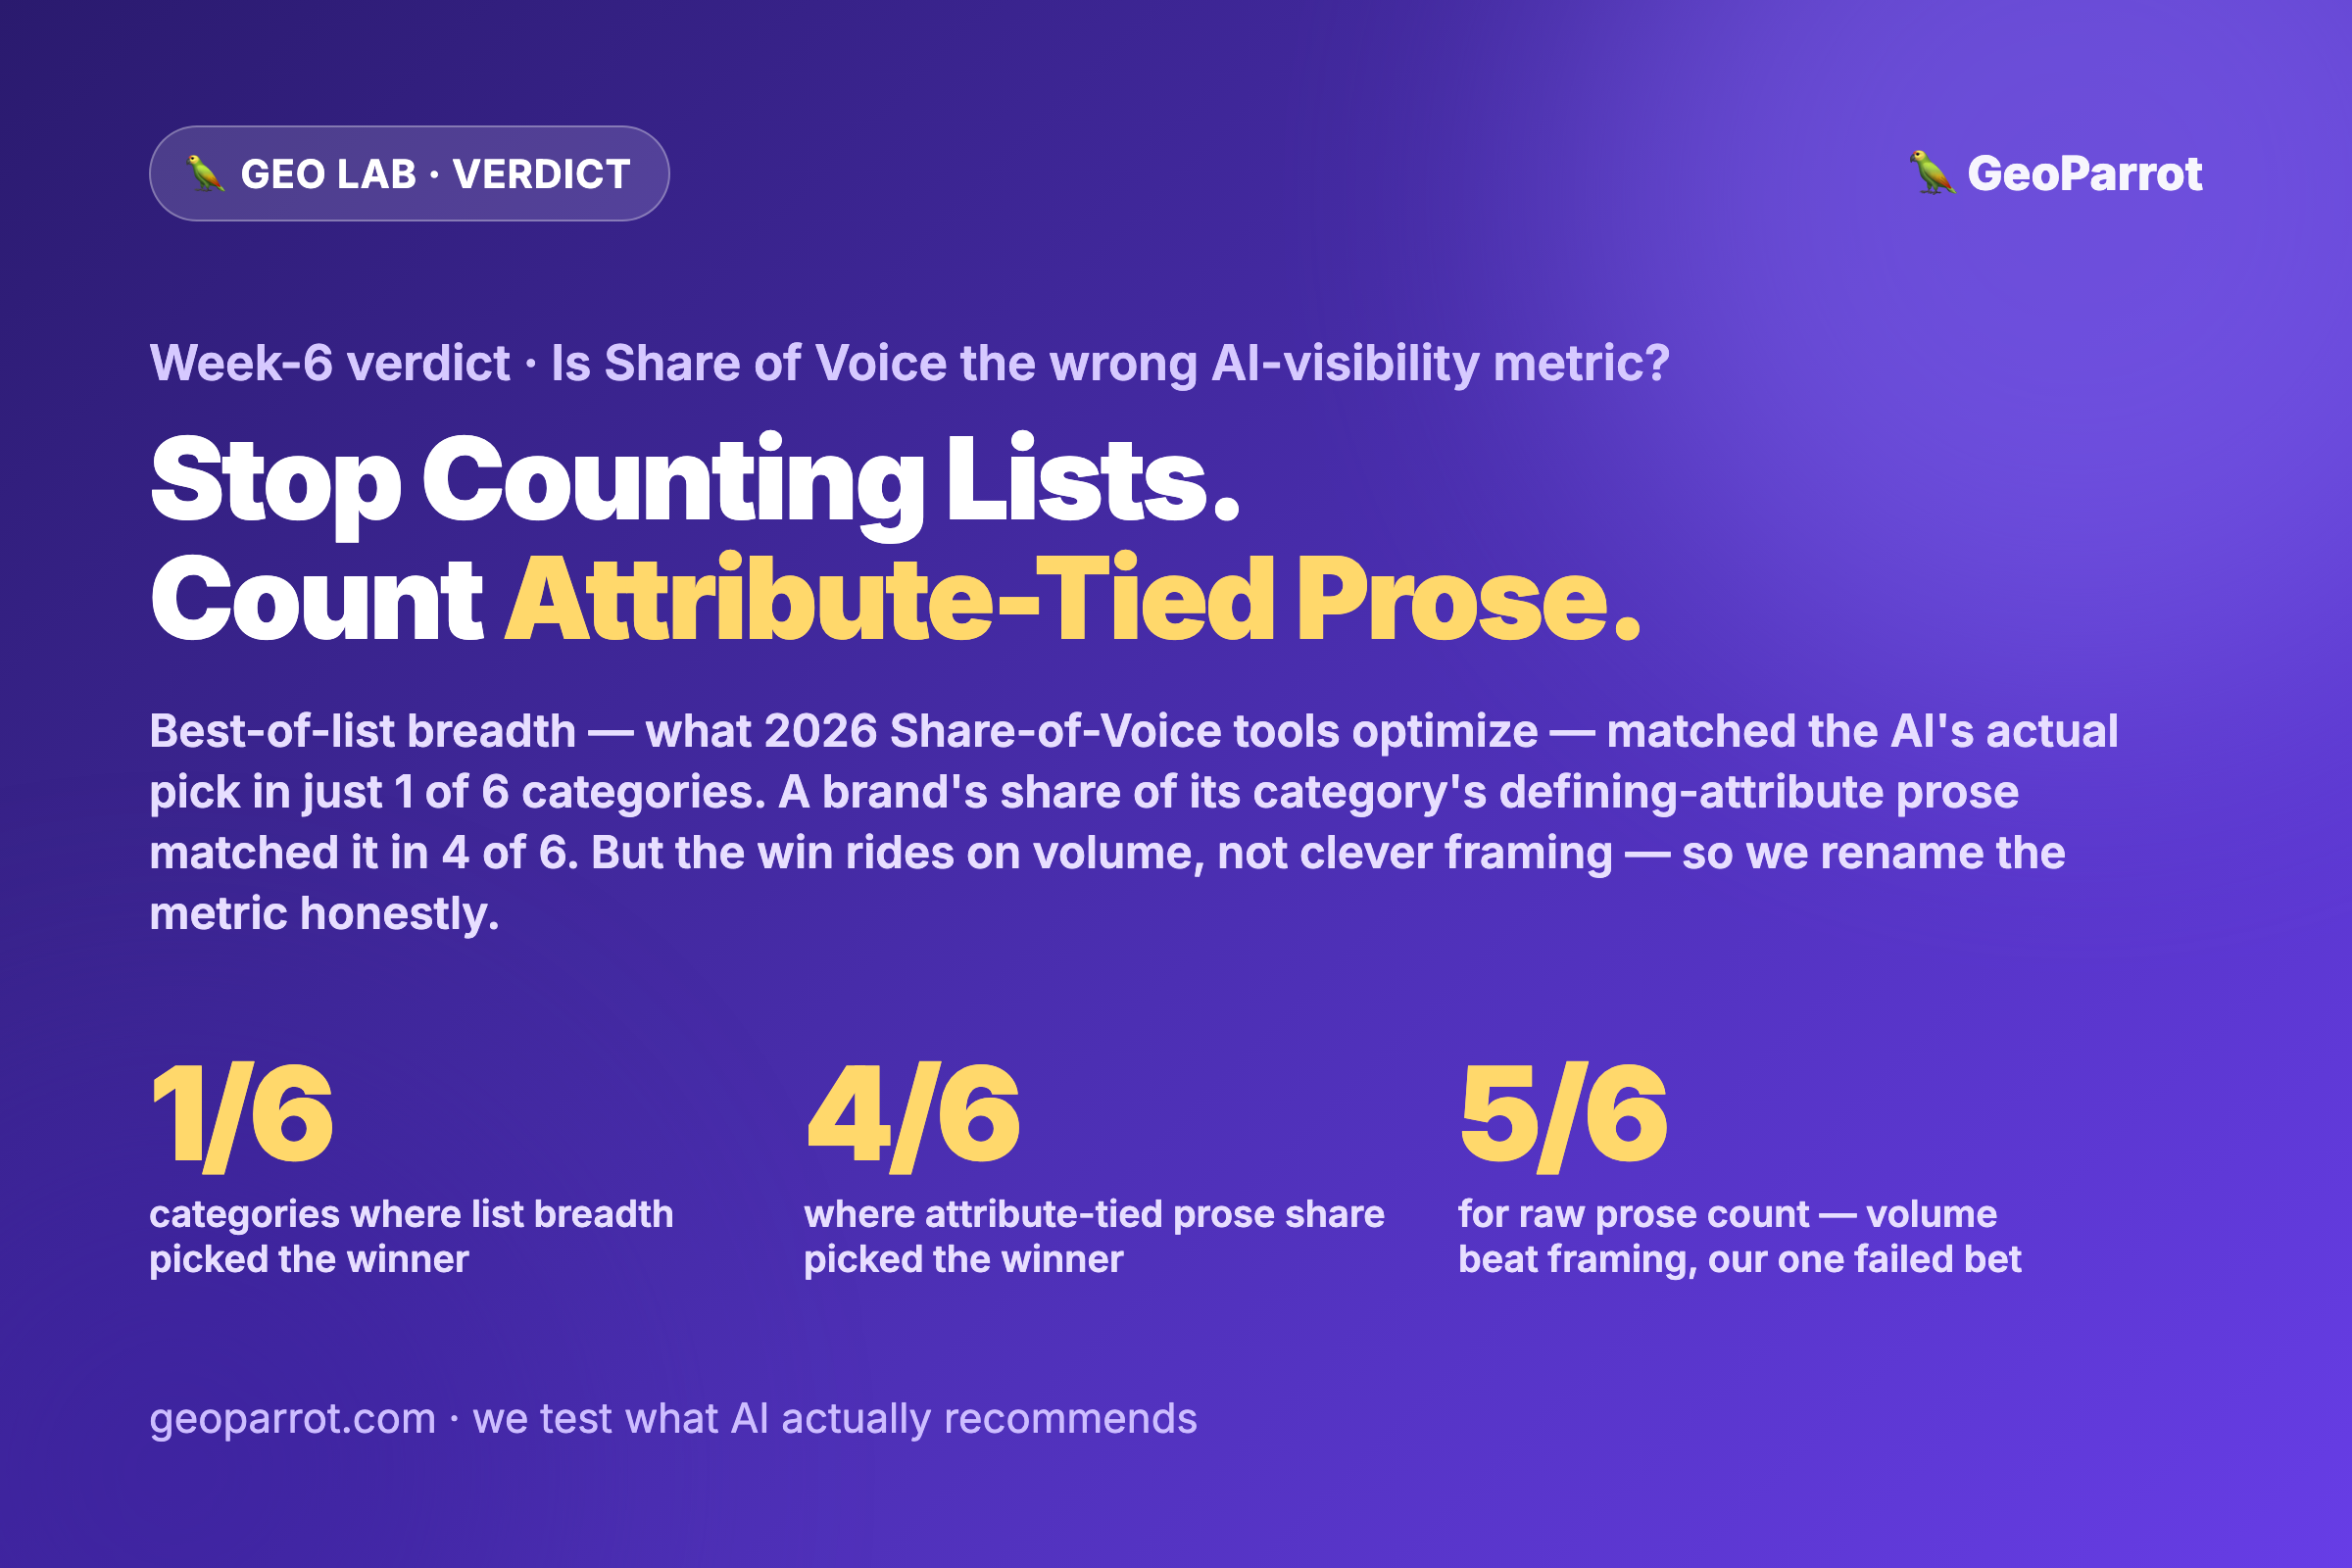
Is Share of Voice the Wrong AI-Visibility Metric? The Verdict: Yes as a Ranking Signal — Optimize Attribute-Tied Prose, Not Best-of Breadth
This week’s GEO Lab tested one question: is Share of Voice — the metric the entire 2026 GEO tooling wave optimizes — the wrong way to measure AI visibility, and should you quantify “narrative ownership” instead? The verdict, on our first-party data: conditionally yes. Best-of-list breadth (what Share-of-Voice tools actually optimize) predicted the AI’s pick…
-
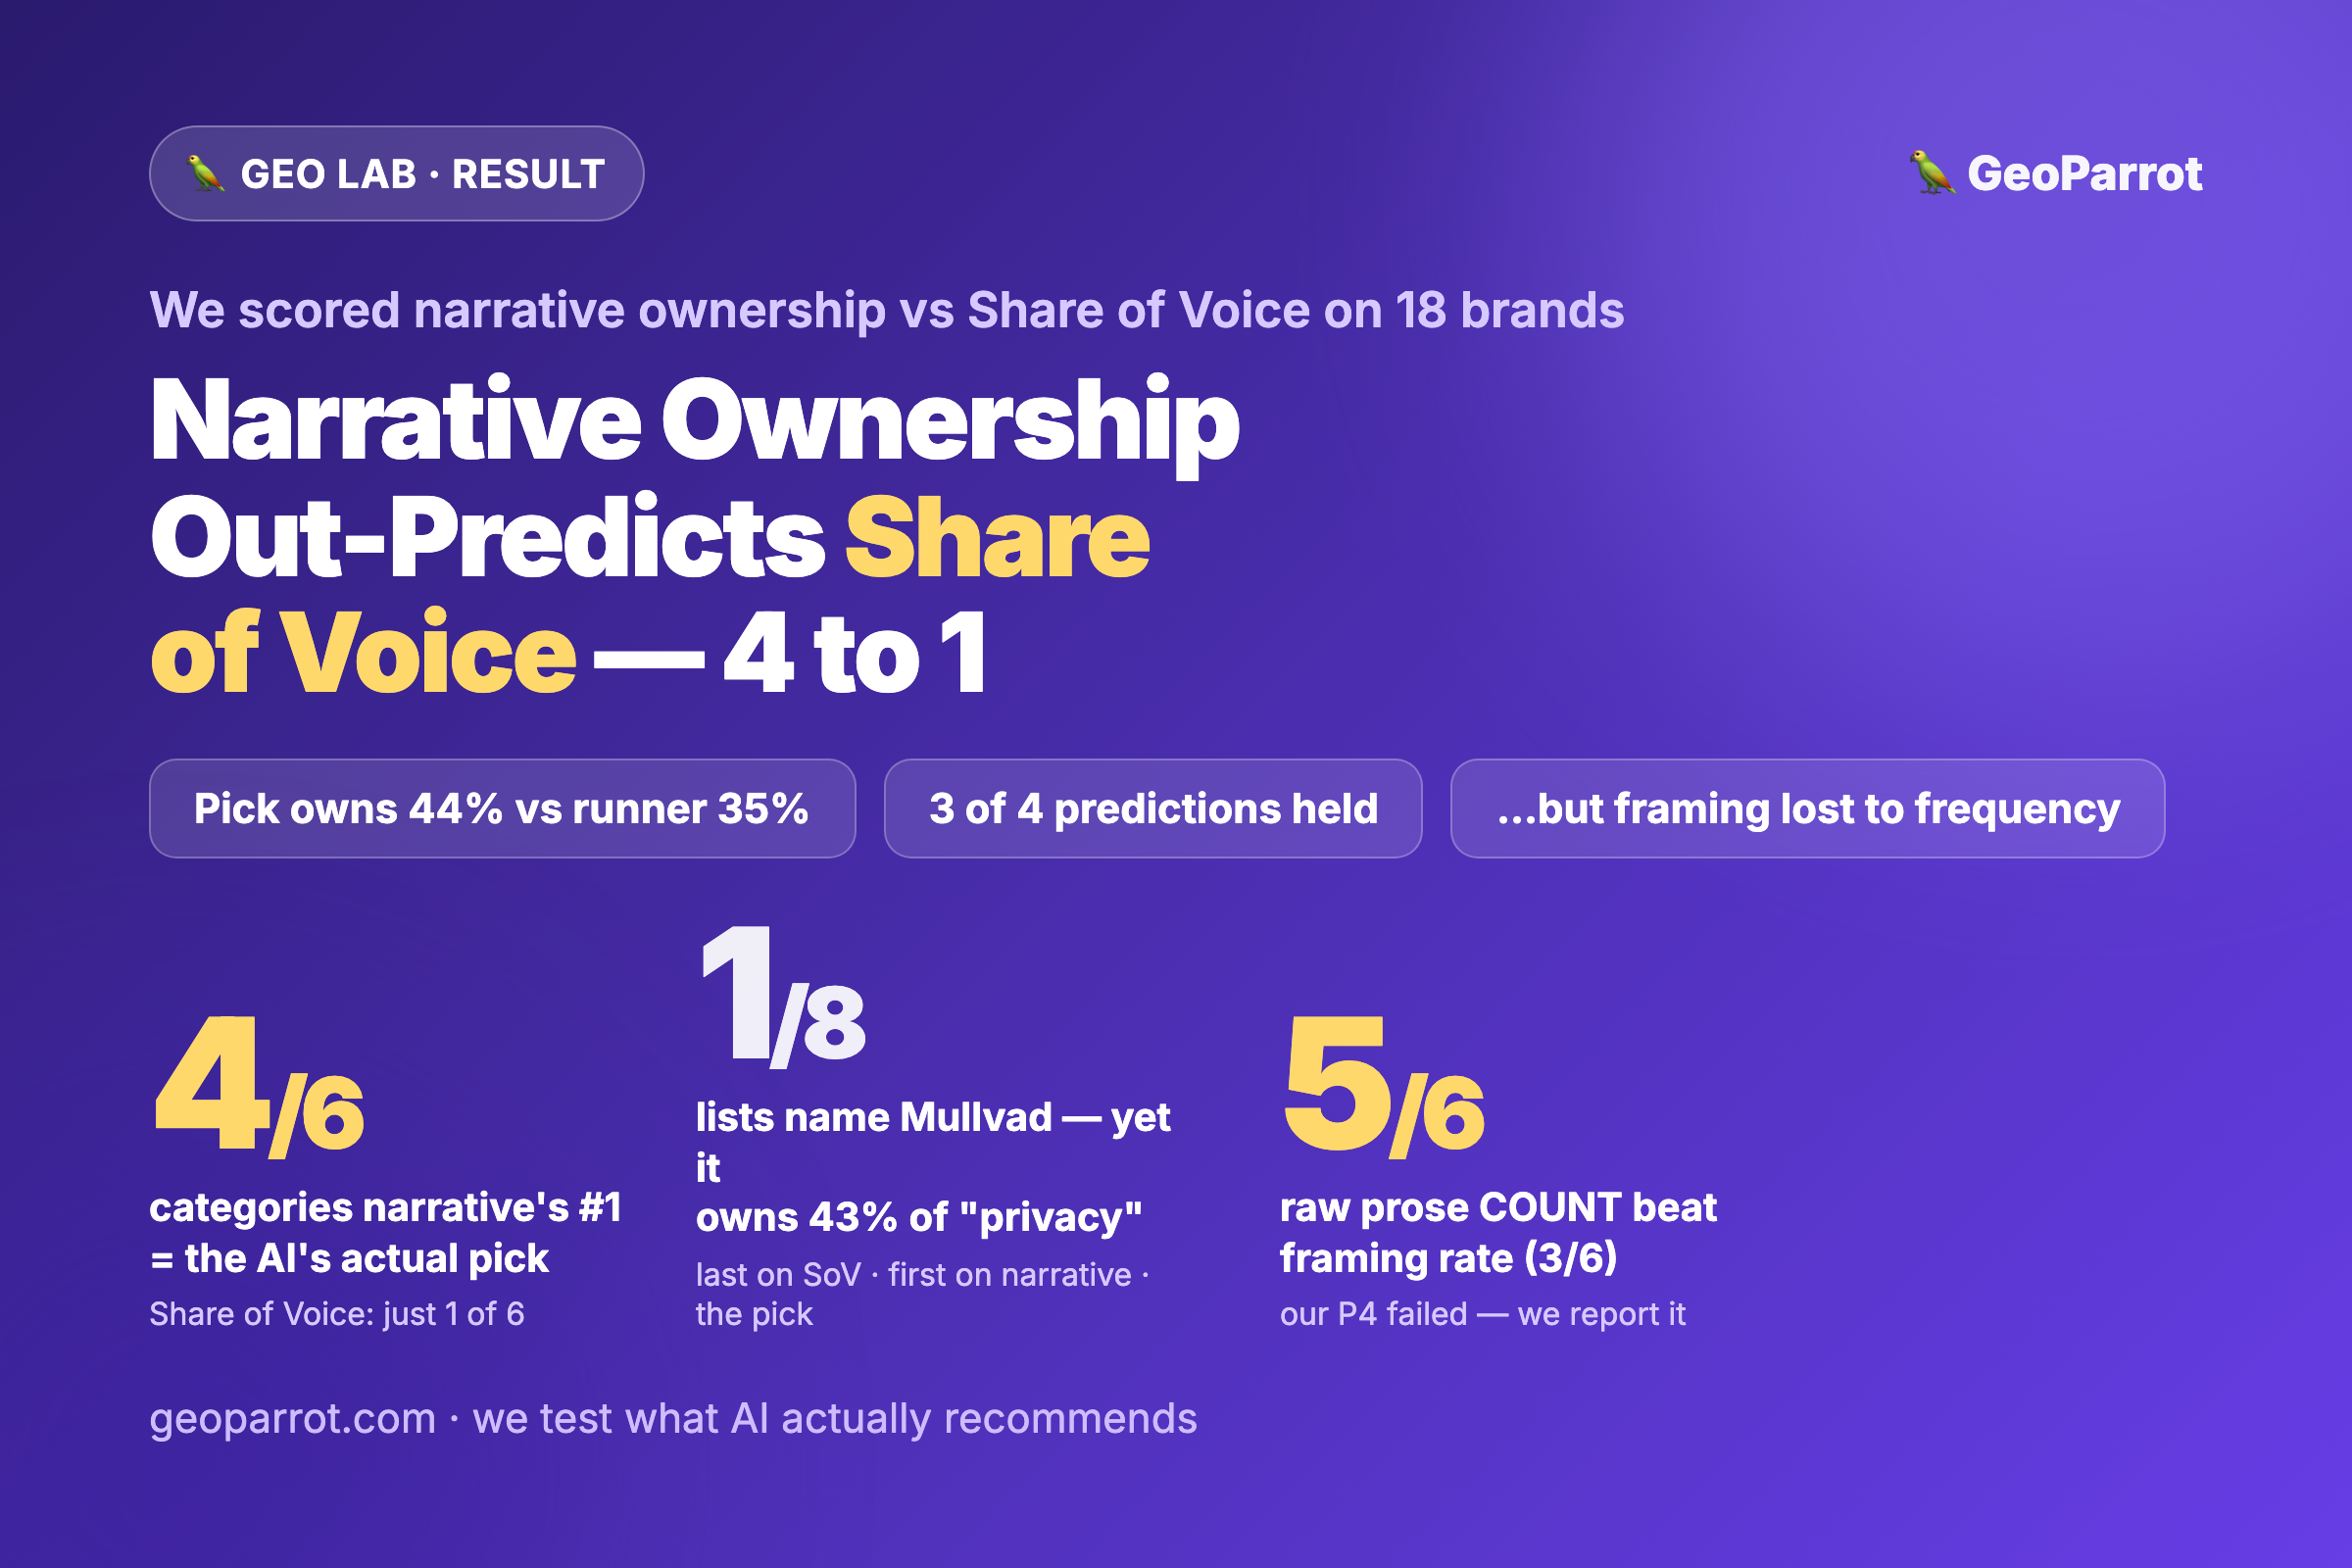
We Scored “Narrative Ownership” vs Share of Voice — It Out-Predicts 4-to-1, But Our Cleanest Prediction Failed
Tuesday we pre-registered four predictions about whether a scored “narrative ownership” metric out-predicts Share of Voice at explaining which brand AI engines recommend. We coded 18 brands across 6 buyer-intent categories on the same frozen corpus — and three of four predictions held. Narrative ownership separates the pick from its runner-up (44% vs 35% vs…
-
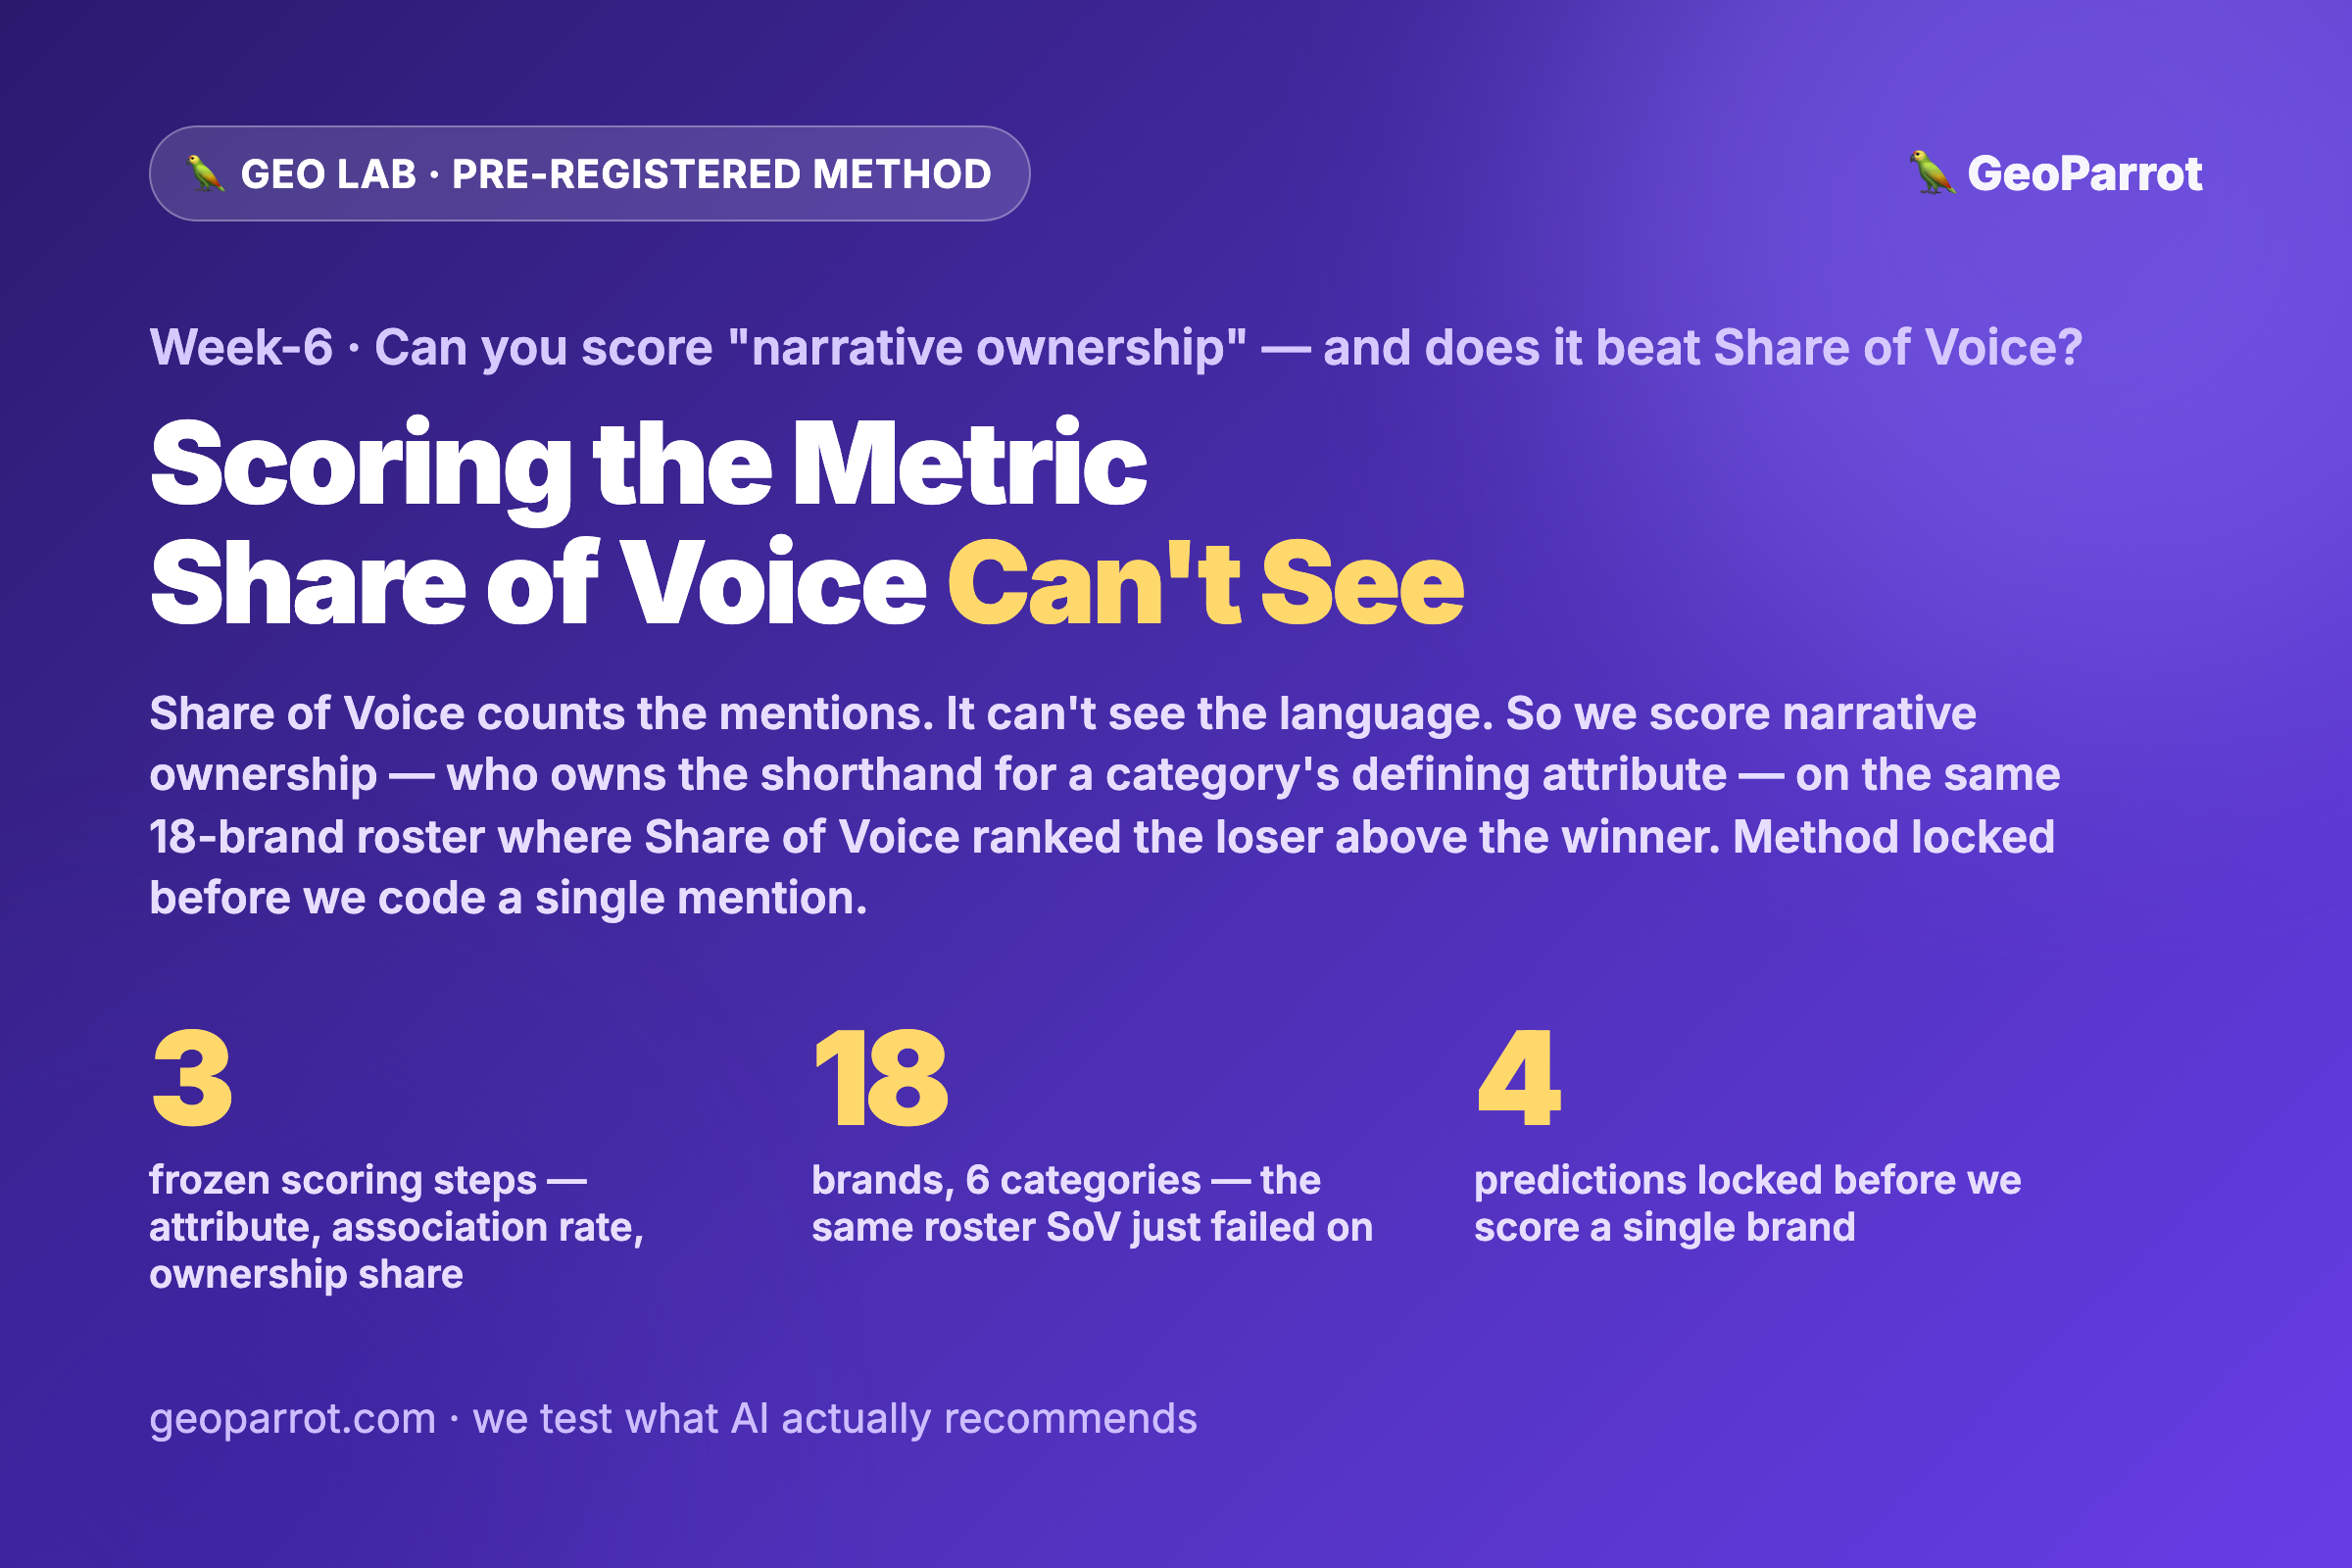
Can You Score “Narrative Ownership” — and Does It Out-Predict Share of Voice? Our Pre-Registered Method
Monday we showed Share of Voice ranks the AI’s runner-up ahead of the winner: the consensus pick sits on fewer best-of lists (82.6% vs 93.2%), with a lower rating and fewer reviews, yet still gets recommended. The lever we named was “narrative ownership” — owning your category’s defining-attribute language in independent prose. But a slogan…
-
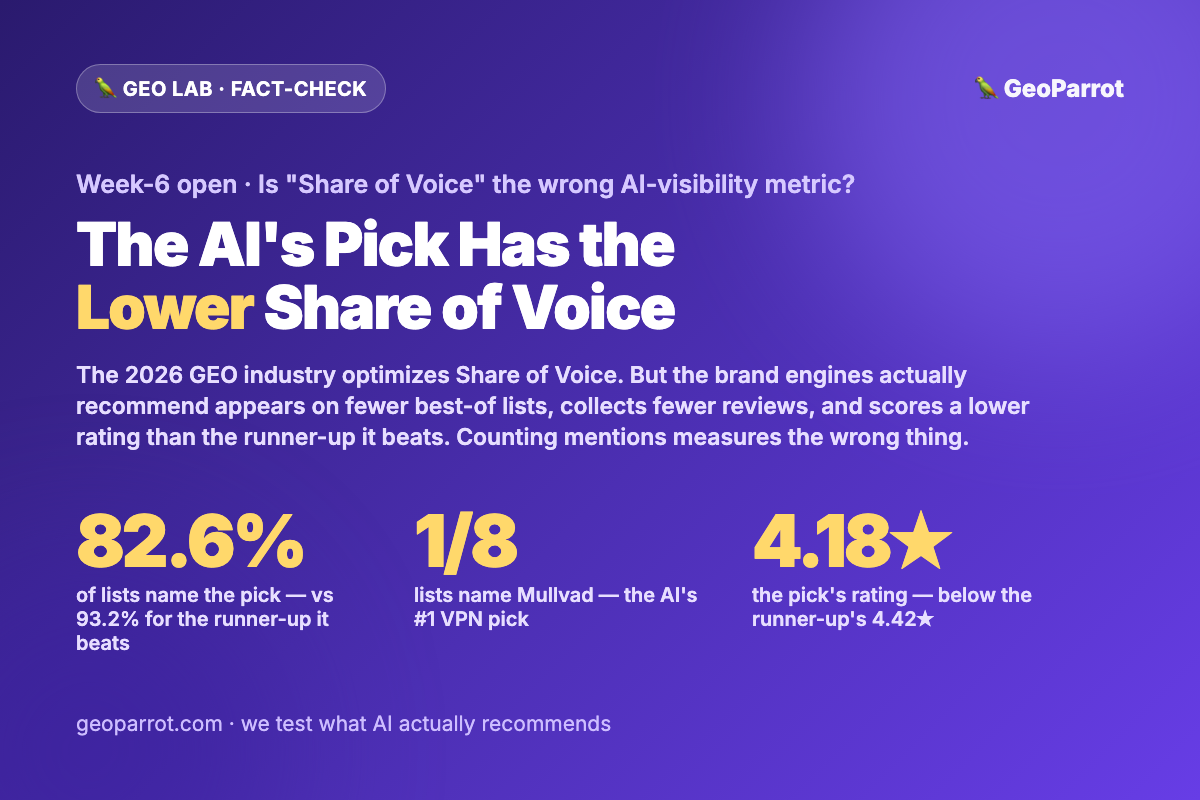
Is “Share of Voice” the Wrong Way to Measure AI Visibility? The Consensus Pick Appears on Fewer Lists Than the Runner-Up It Beats
The whole 2026 GEO tooling wave — Profound, AthenaHQ, Peec and a dozen others — is built on one metric: Share of Voice, your share of AI brand mentions. AthenaHQ’s State of AI Search 2026 pegs the average brand mention rate at 17.2%. But when we checked whether more Share of Voice actually predicts which…
-
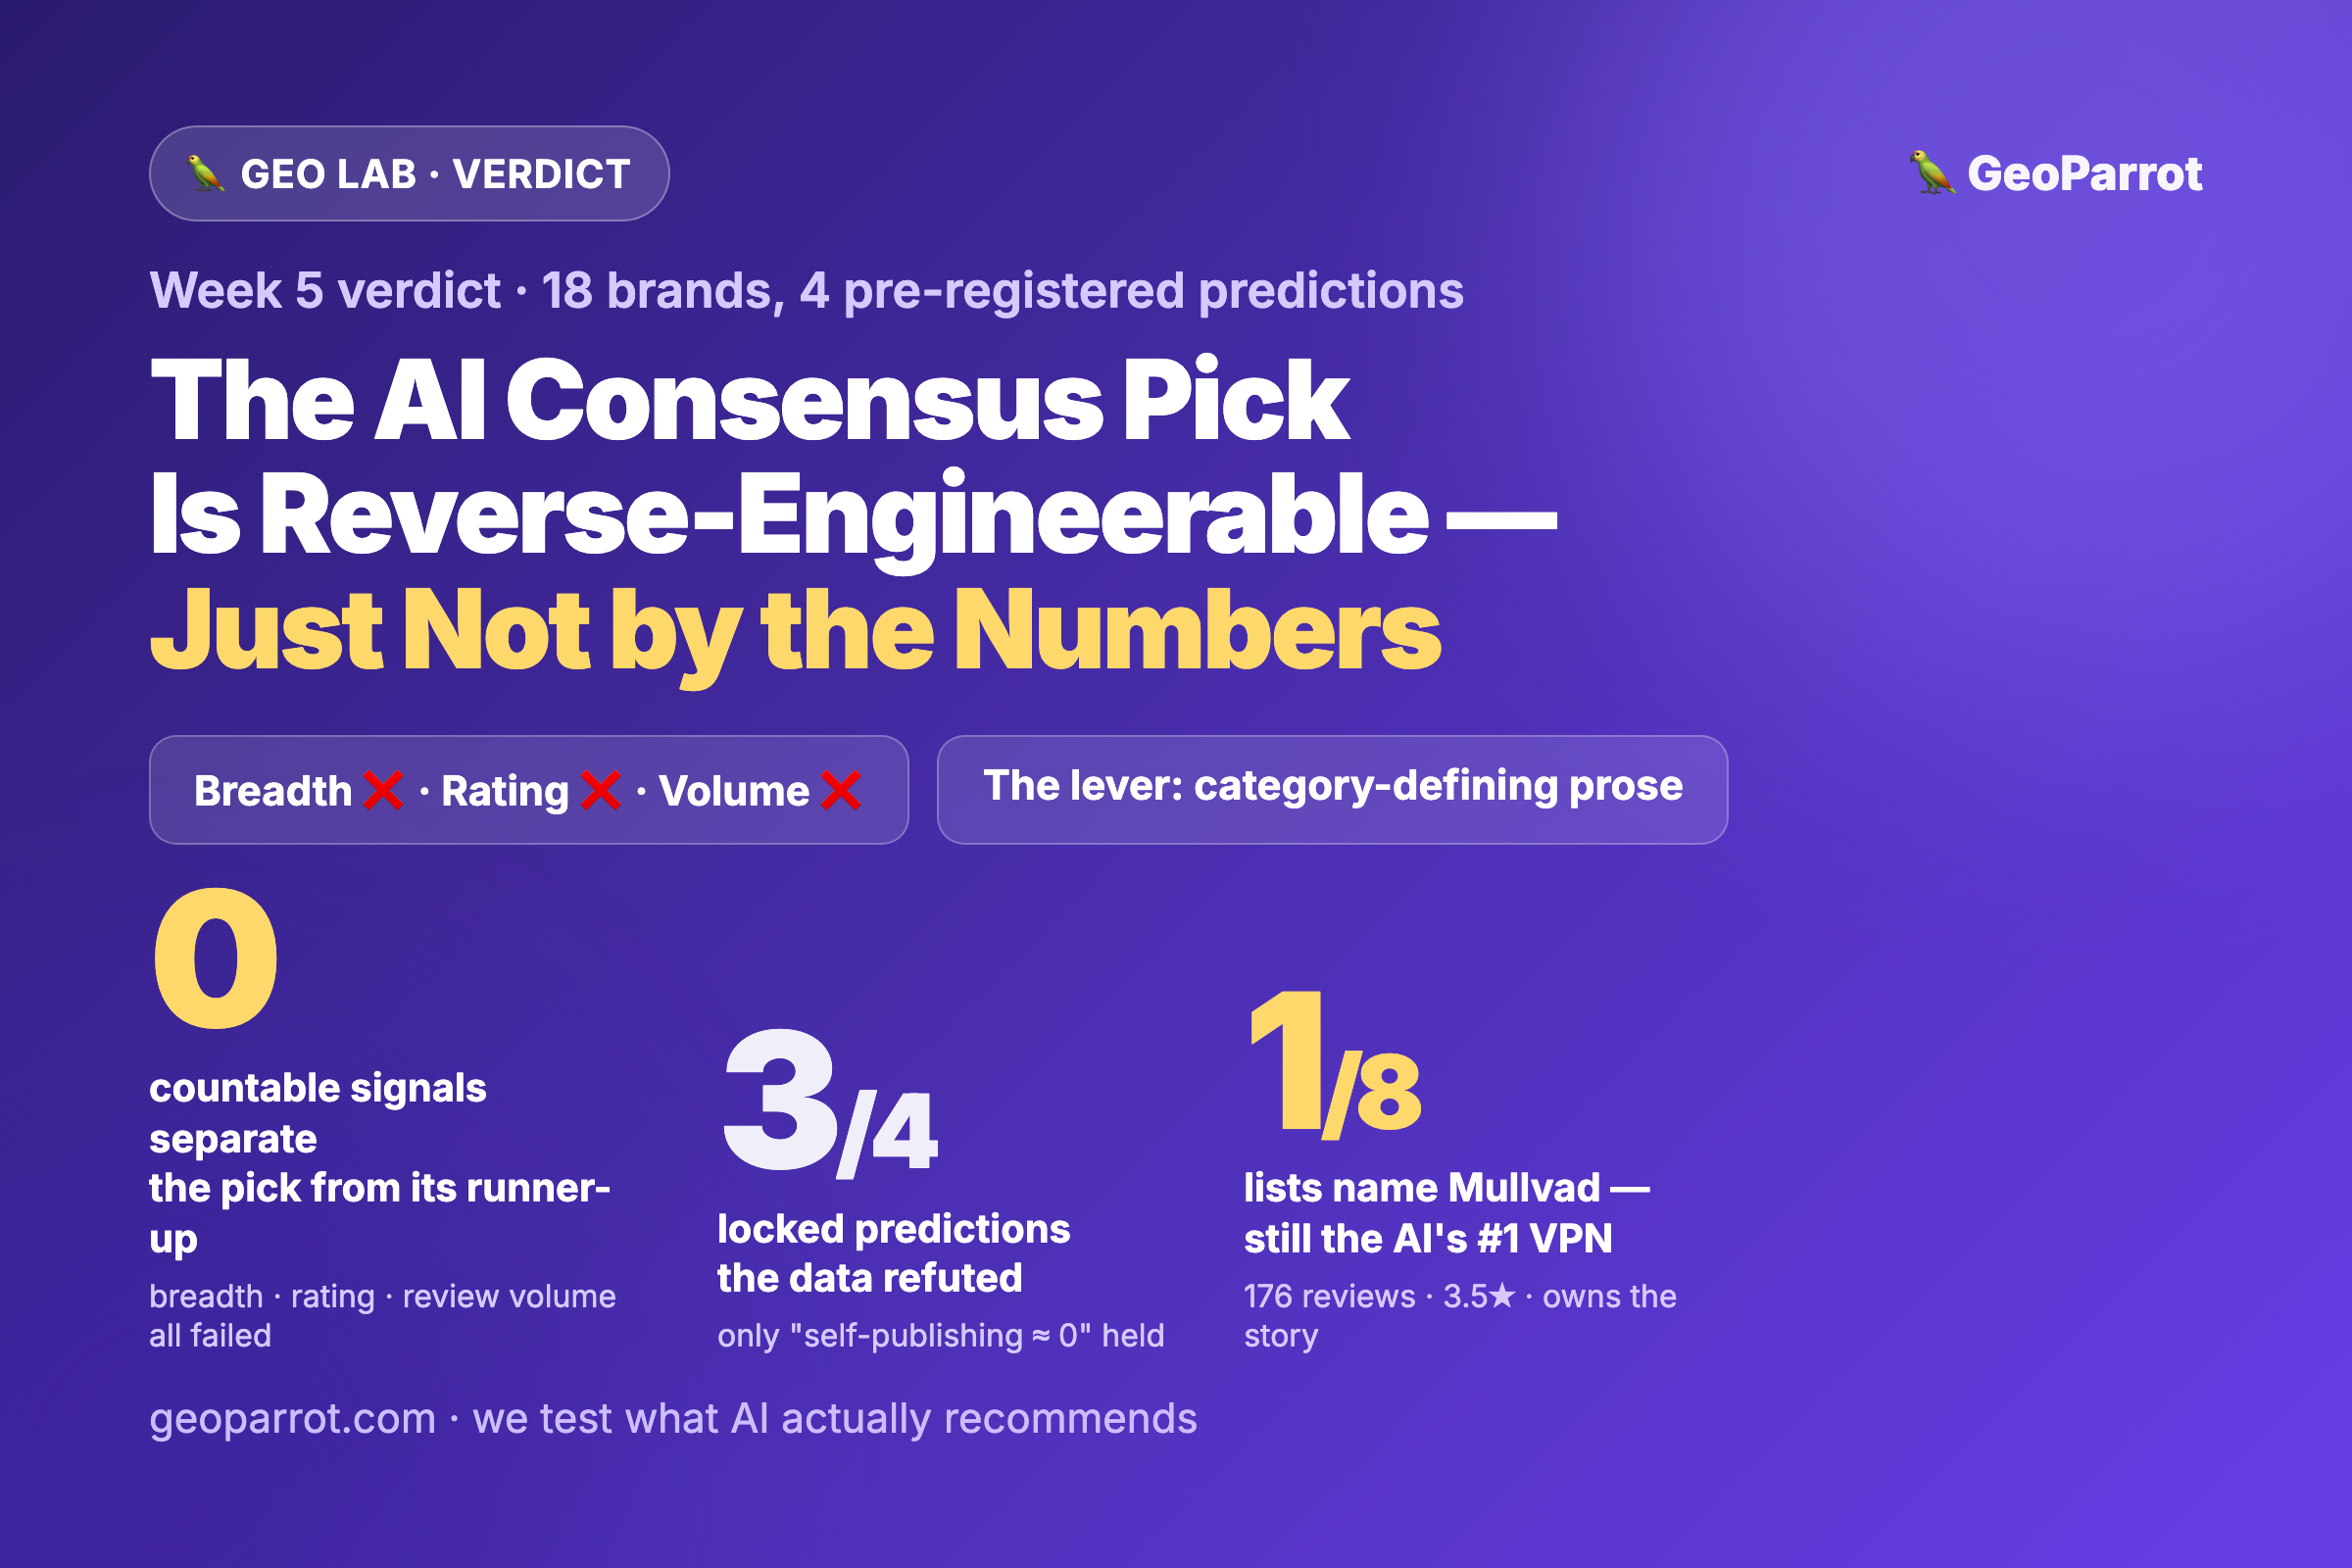
The Verdict: Can You Reverse-Engineer the AI Consensus Pick? Yes — Just Not With the Signals You’re Optimizing
This week we asked which reputation signal separates an AI “consensus” pick from an equally-good runner-up, pre-registered four predictions, and scored 18 brands. The verdict: three of four predictions failed. Best-of breadth doesn’t separate the pick (runner-ups matched or beat it in 5 of 6 categories), star rating is a 4.2–4.5★ floor everyone clears, and…