Author: GeoParrot Team
-
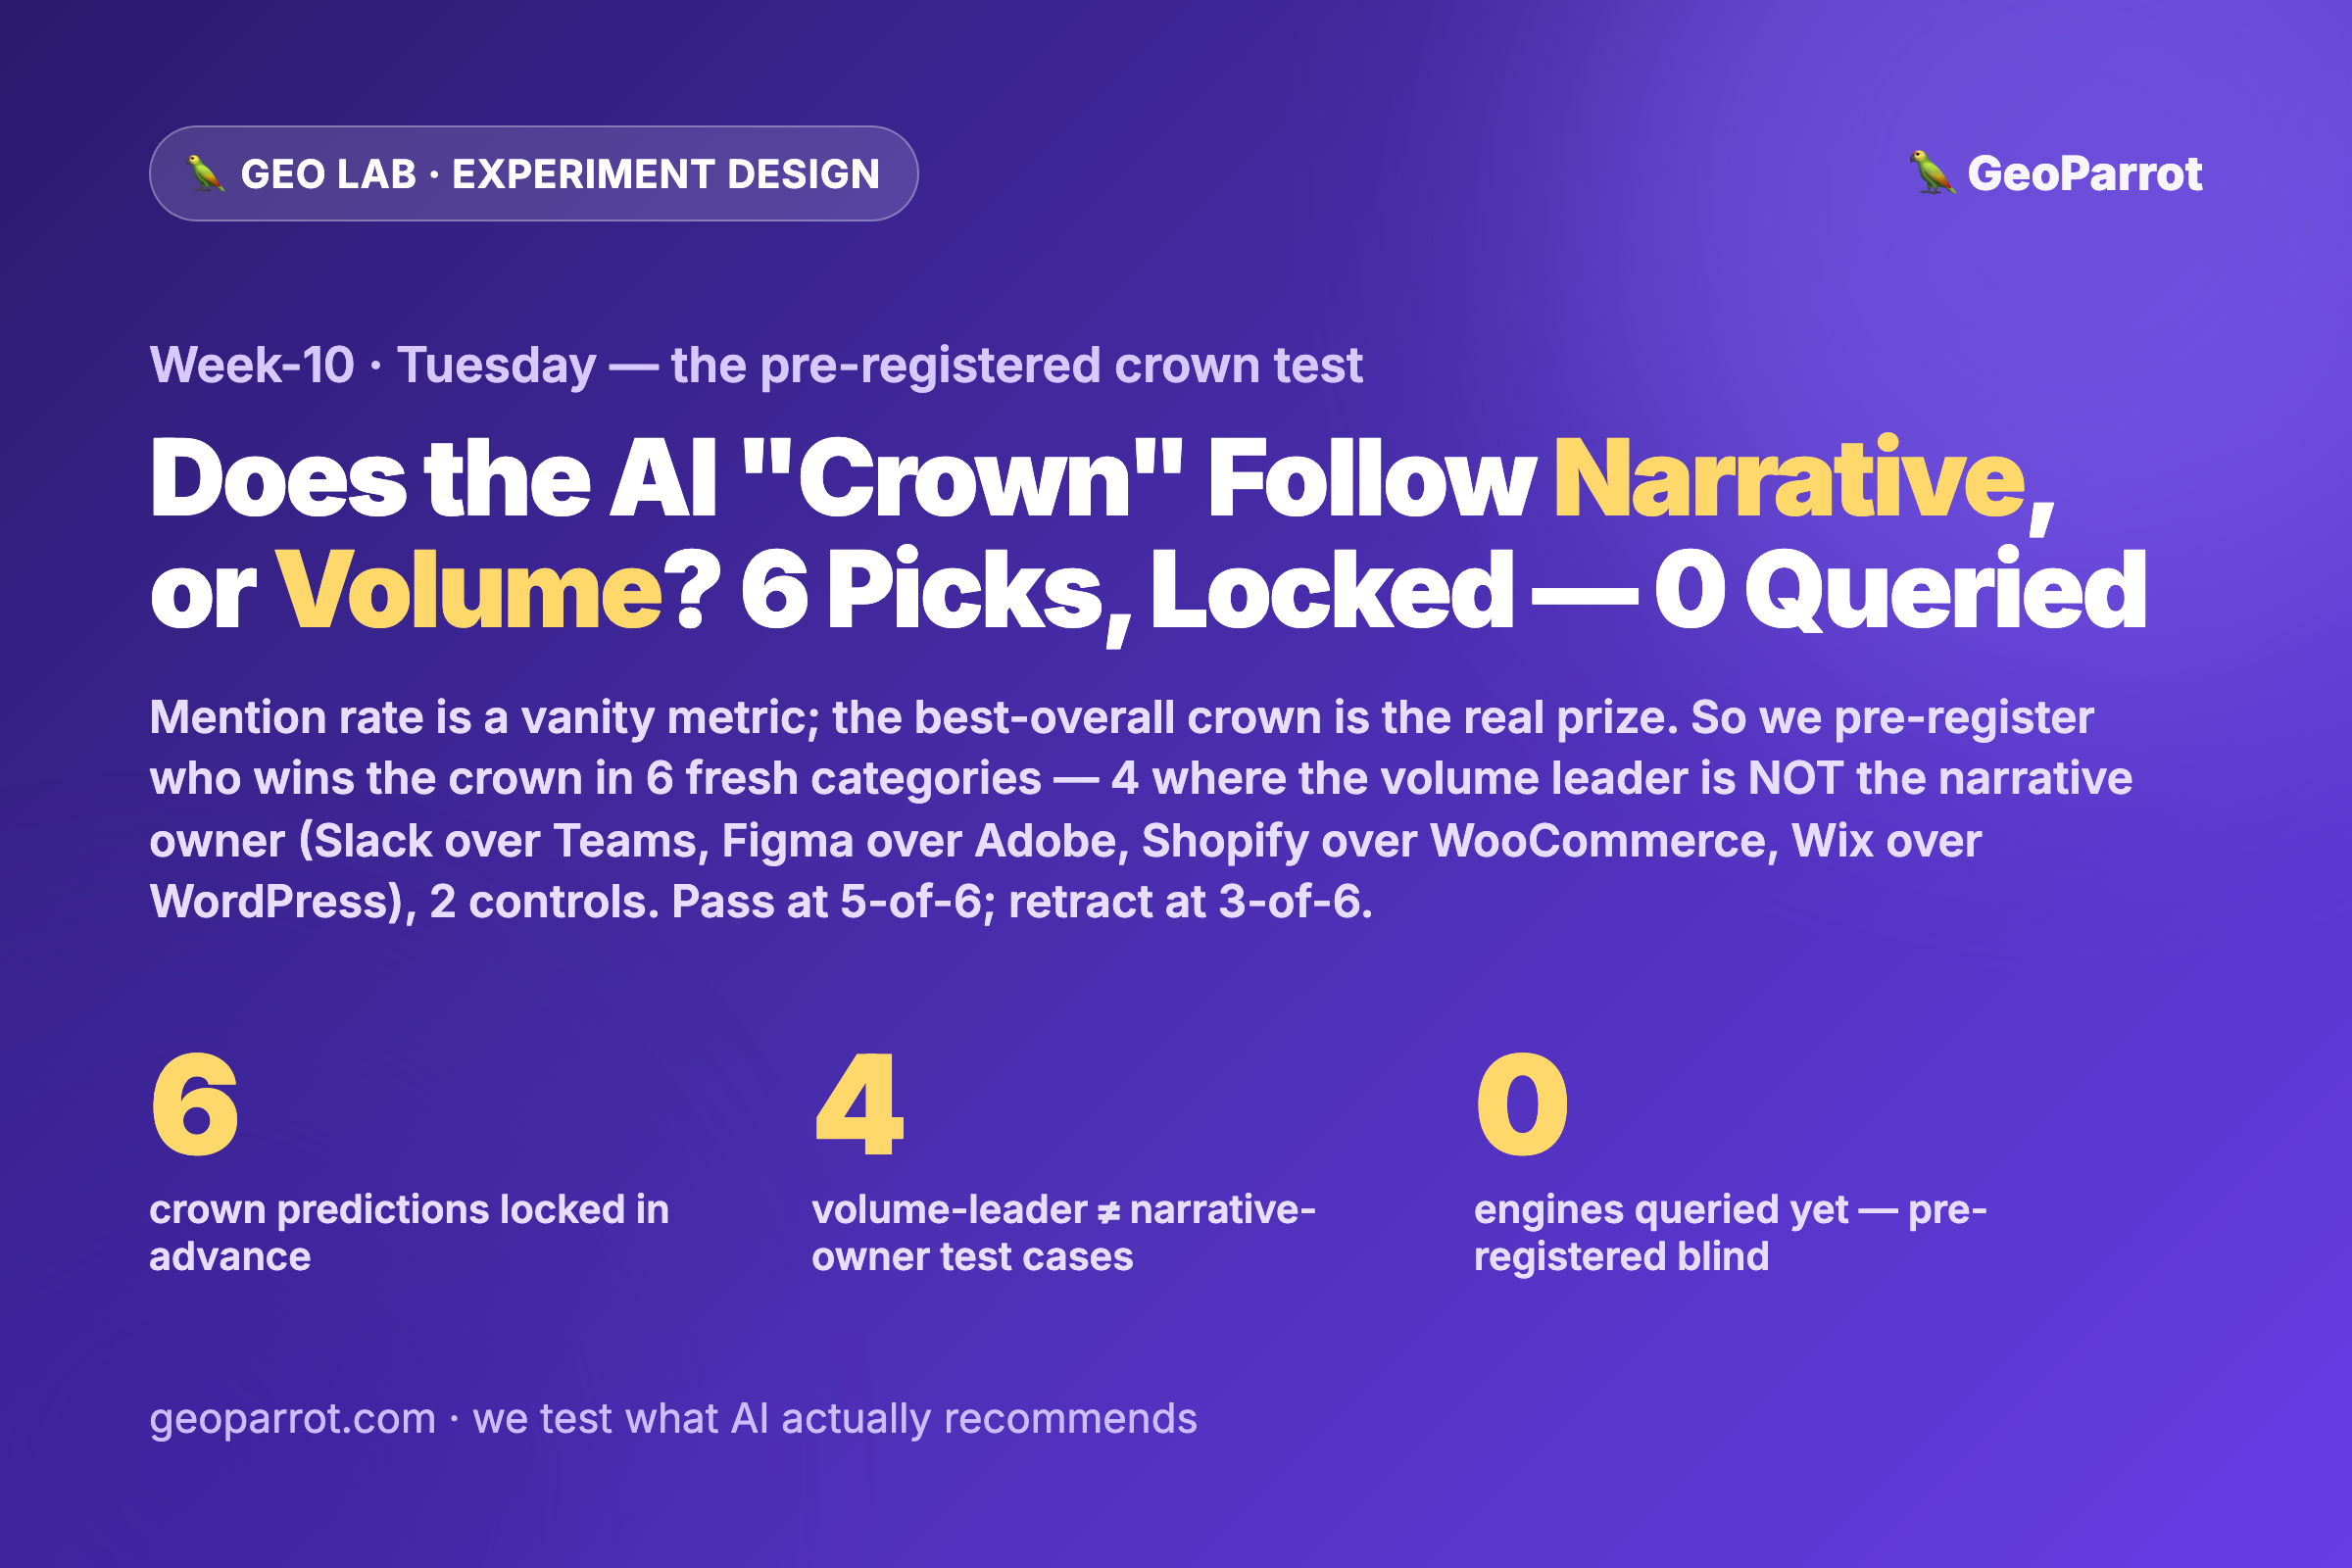
If the “Best-Overall Crown” Is the Only AI Metric That Sorts Winners, Can We Predict It Blind? We Bet the Crown Follows Narrative, Not Volume — 6 Predictions Locked Before a Single Query
Monday we argued that AI “share of voice” is a vanity metric — 2026 “best X” answers are segmented listicles that name nearly everyone — and that the only score that sorts winners is the best-overall crown. Today we put that to a blind, pre-registered test. Two rival models predict who gets crowned: the volume…
-
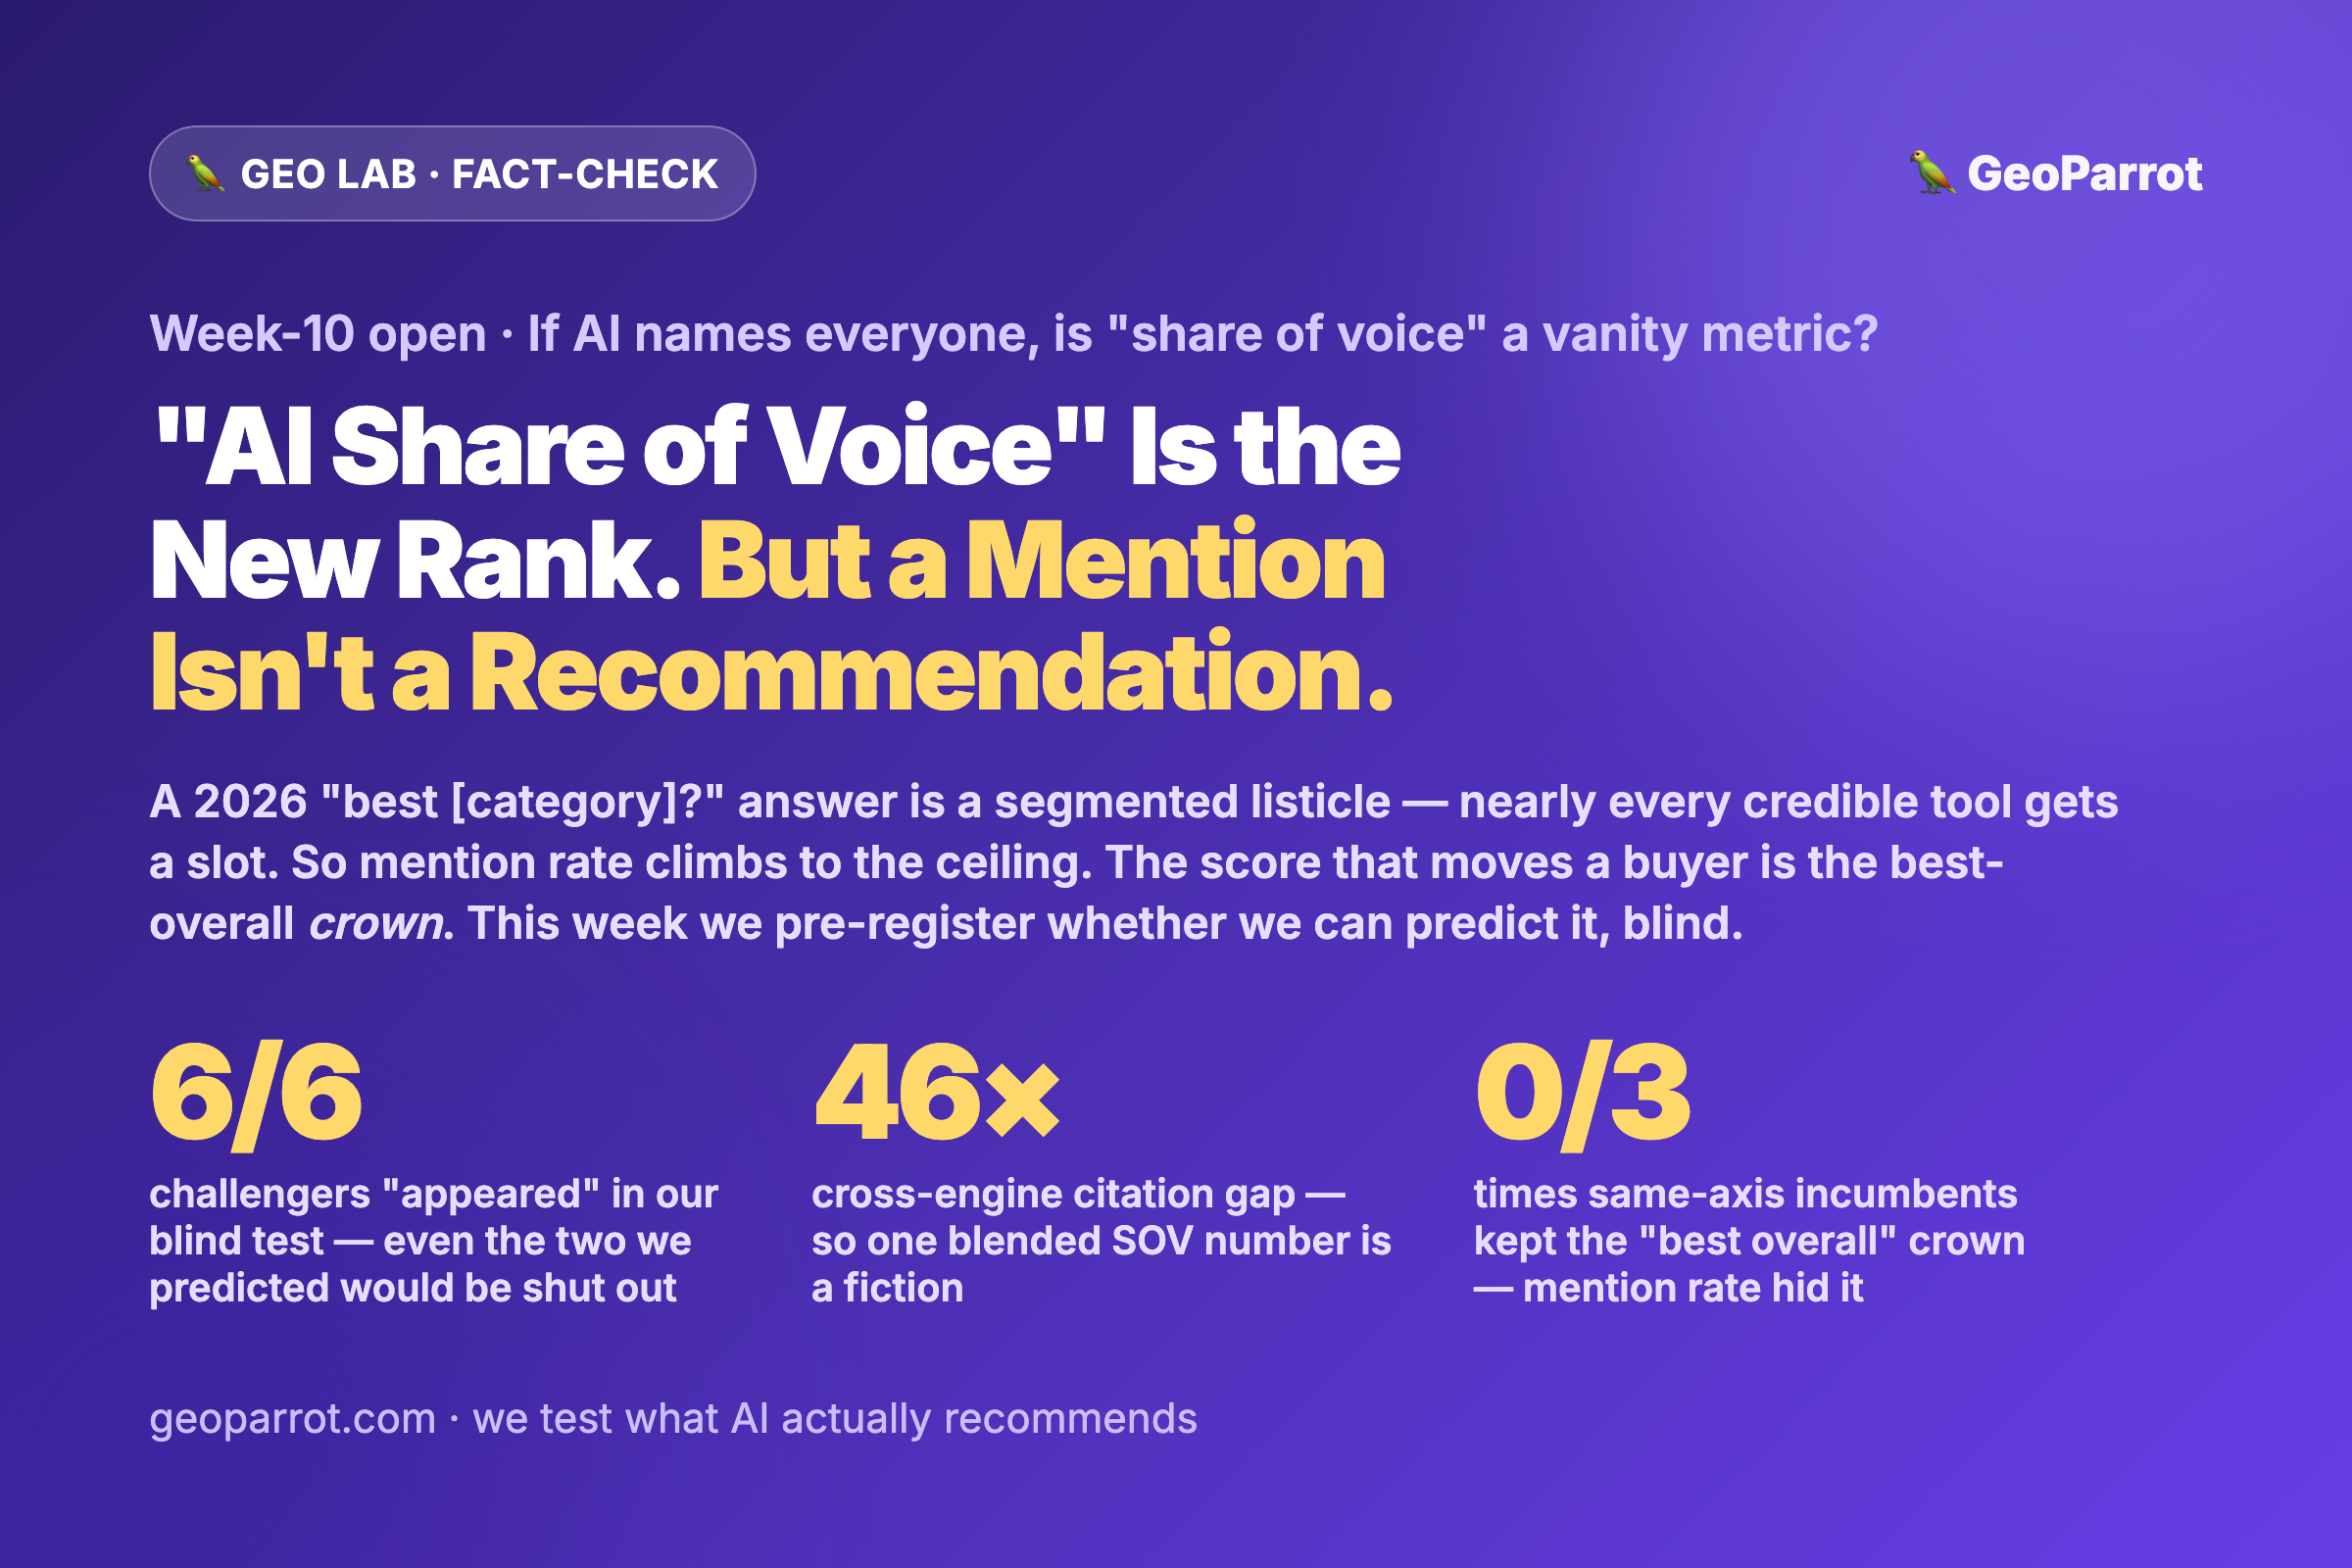
“AI Share of Voice” Is Being Sold as the New SEO Rank. Half True — When the AI Names Almost Everyone, Mention Rate Is a Vanity Metric, and the Only Score That Moves a Buyer Is the “Best-Overall Crown”
In 2026 a whole tool category is selling “AI Share of Voice” as the metric that replaces SEO rank — with benchmark tiers (below 8% is a citation gap, 15–25% competitive, above 40% category-dominant). Half of that is right: how often an engine names you has replaced blue-link position as the visibility signal. But there’s…
-
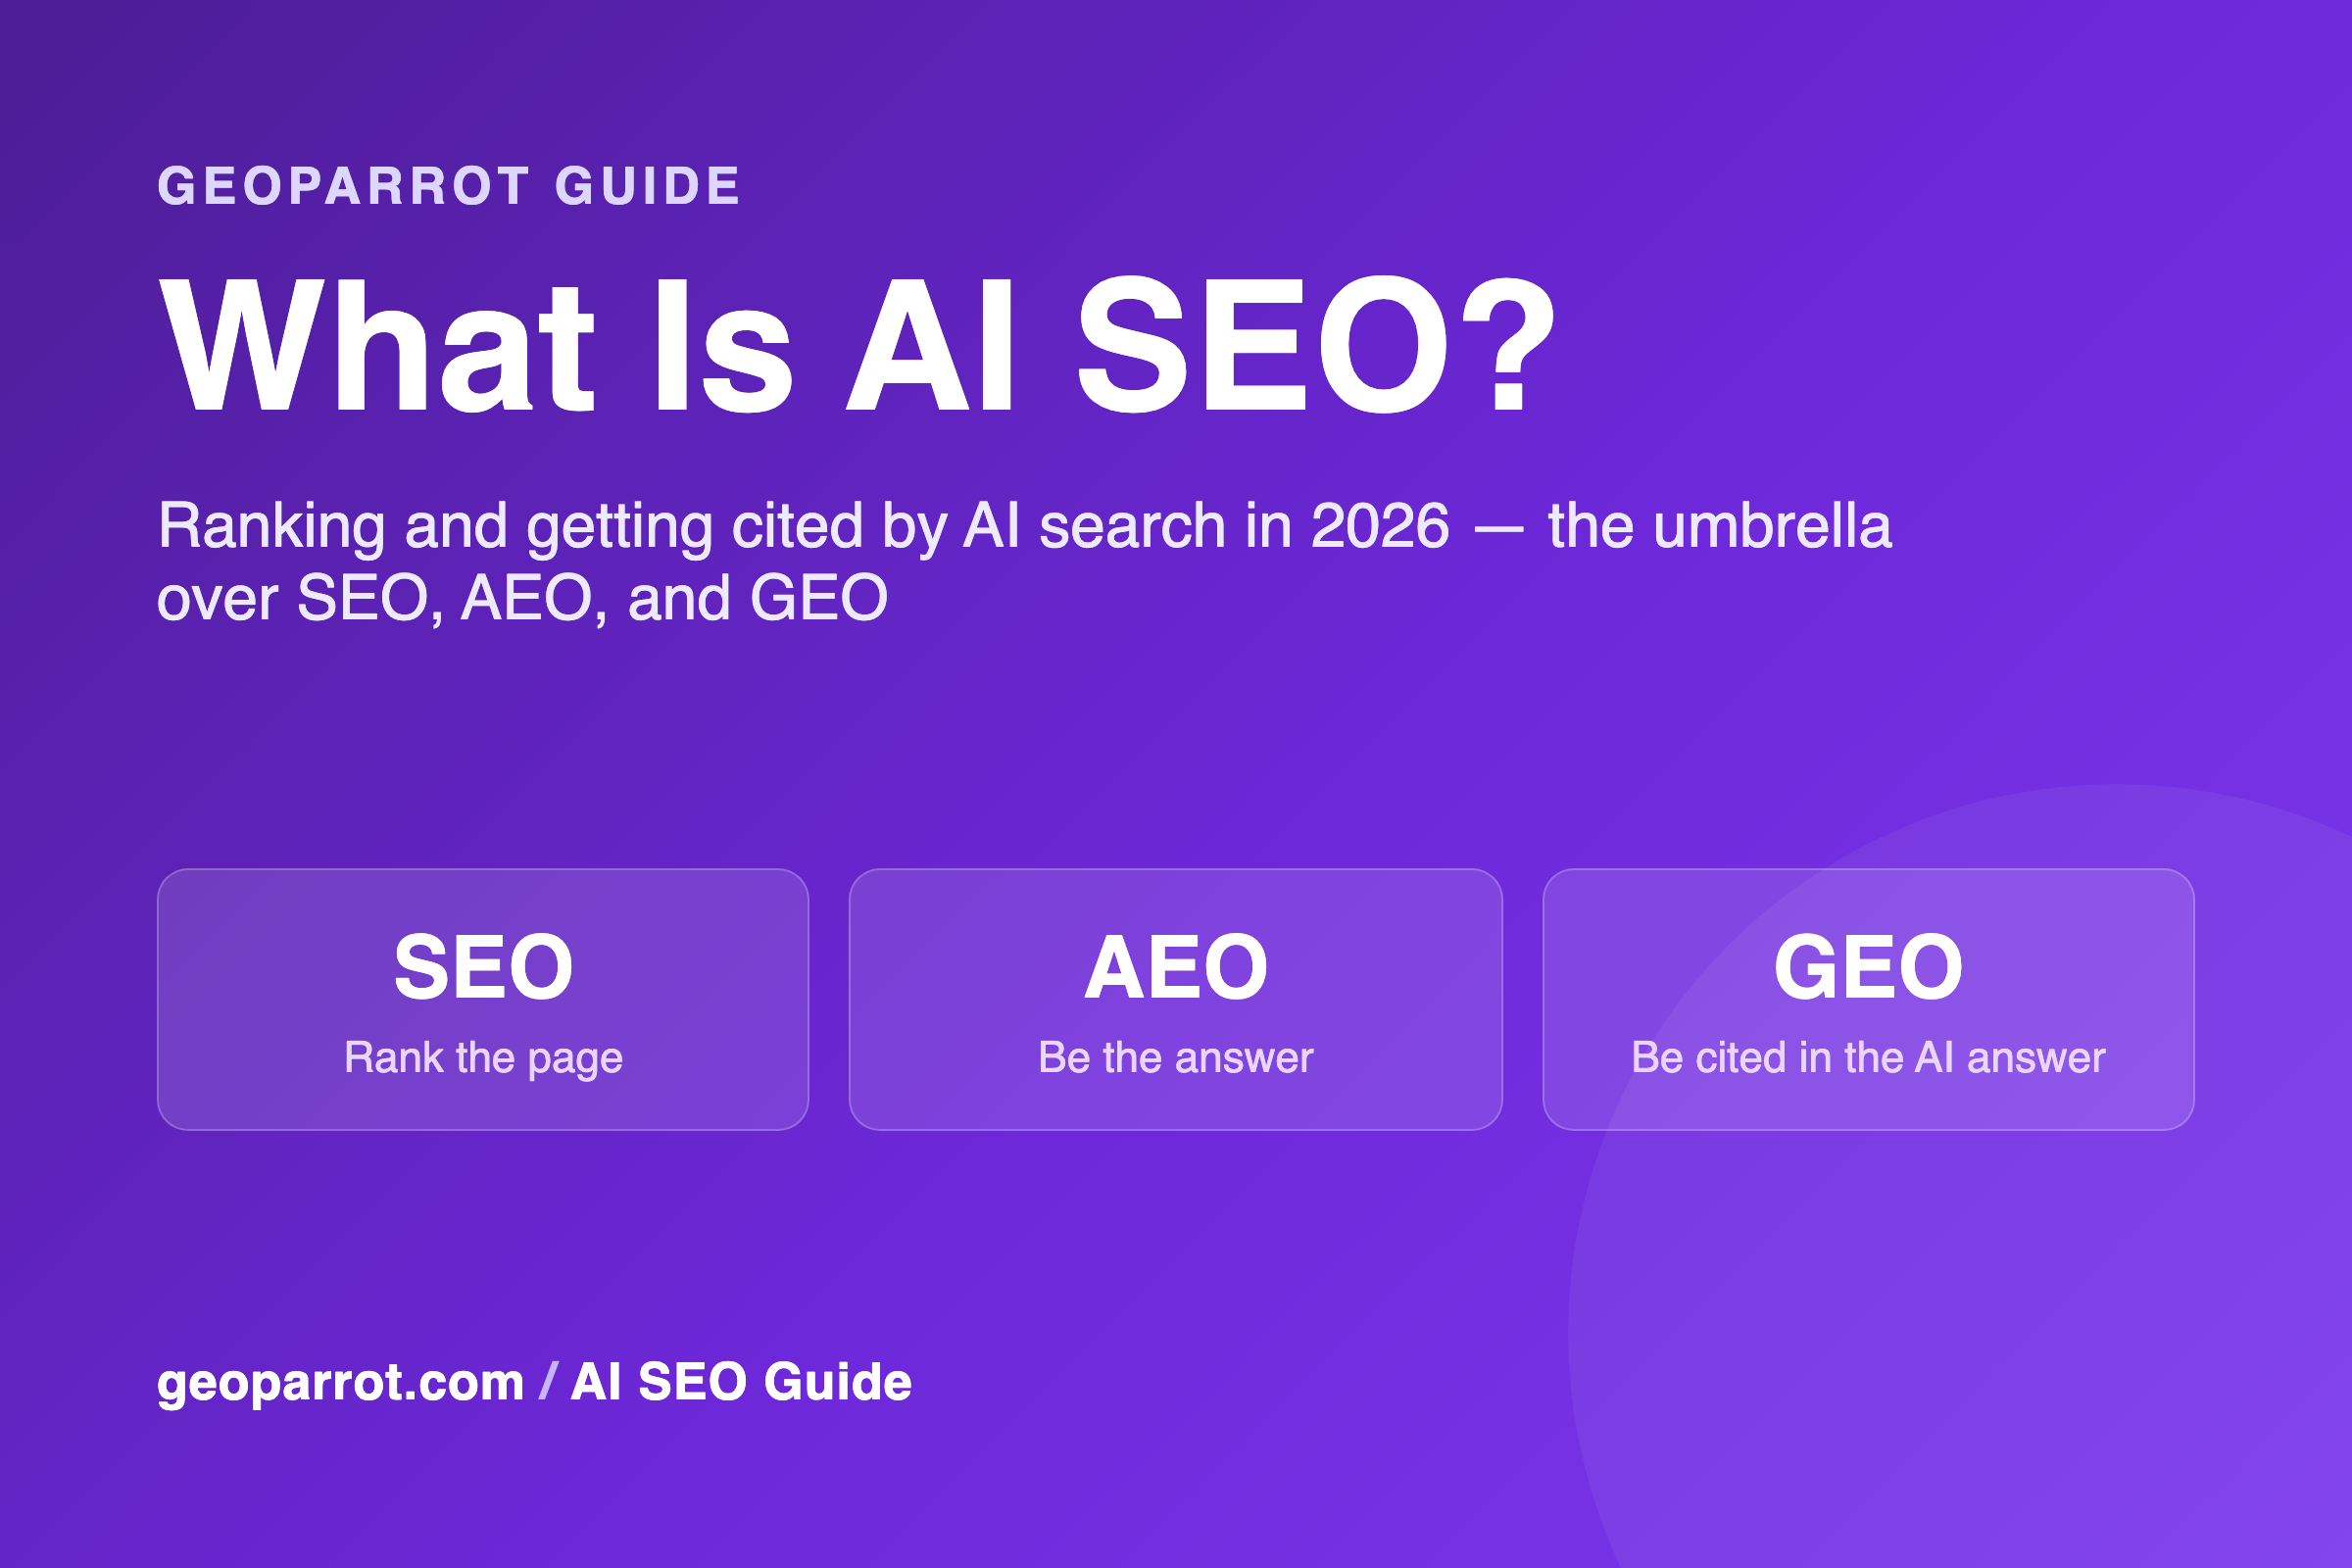
What Is AI SEO? The 2026 Guide to Ranking and Getting Cited by AI Search
AI SEO is optimizing your content so AI-powered search — ChatGPT, Perplexity, Gemini, Copilot, and Google AI Overviews — ranks, quotes, and cites you. It combines classic SEO, AEO, and GEO. Here is the 2026 playbook.
-
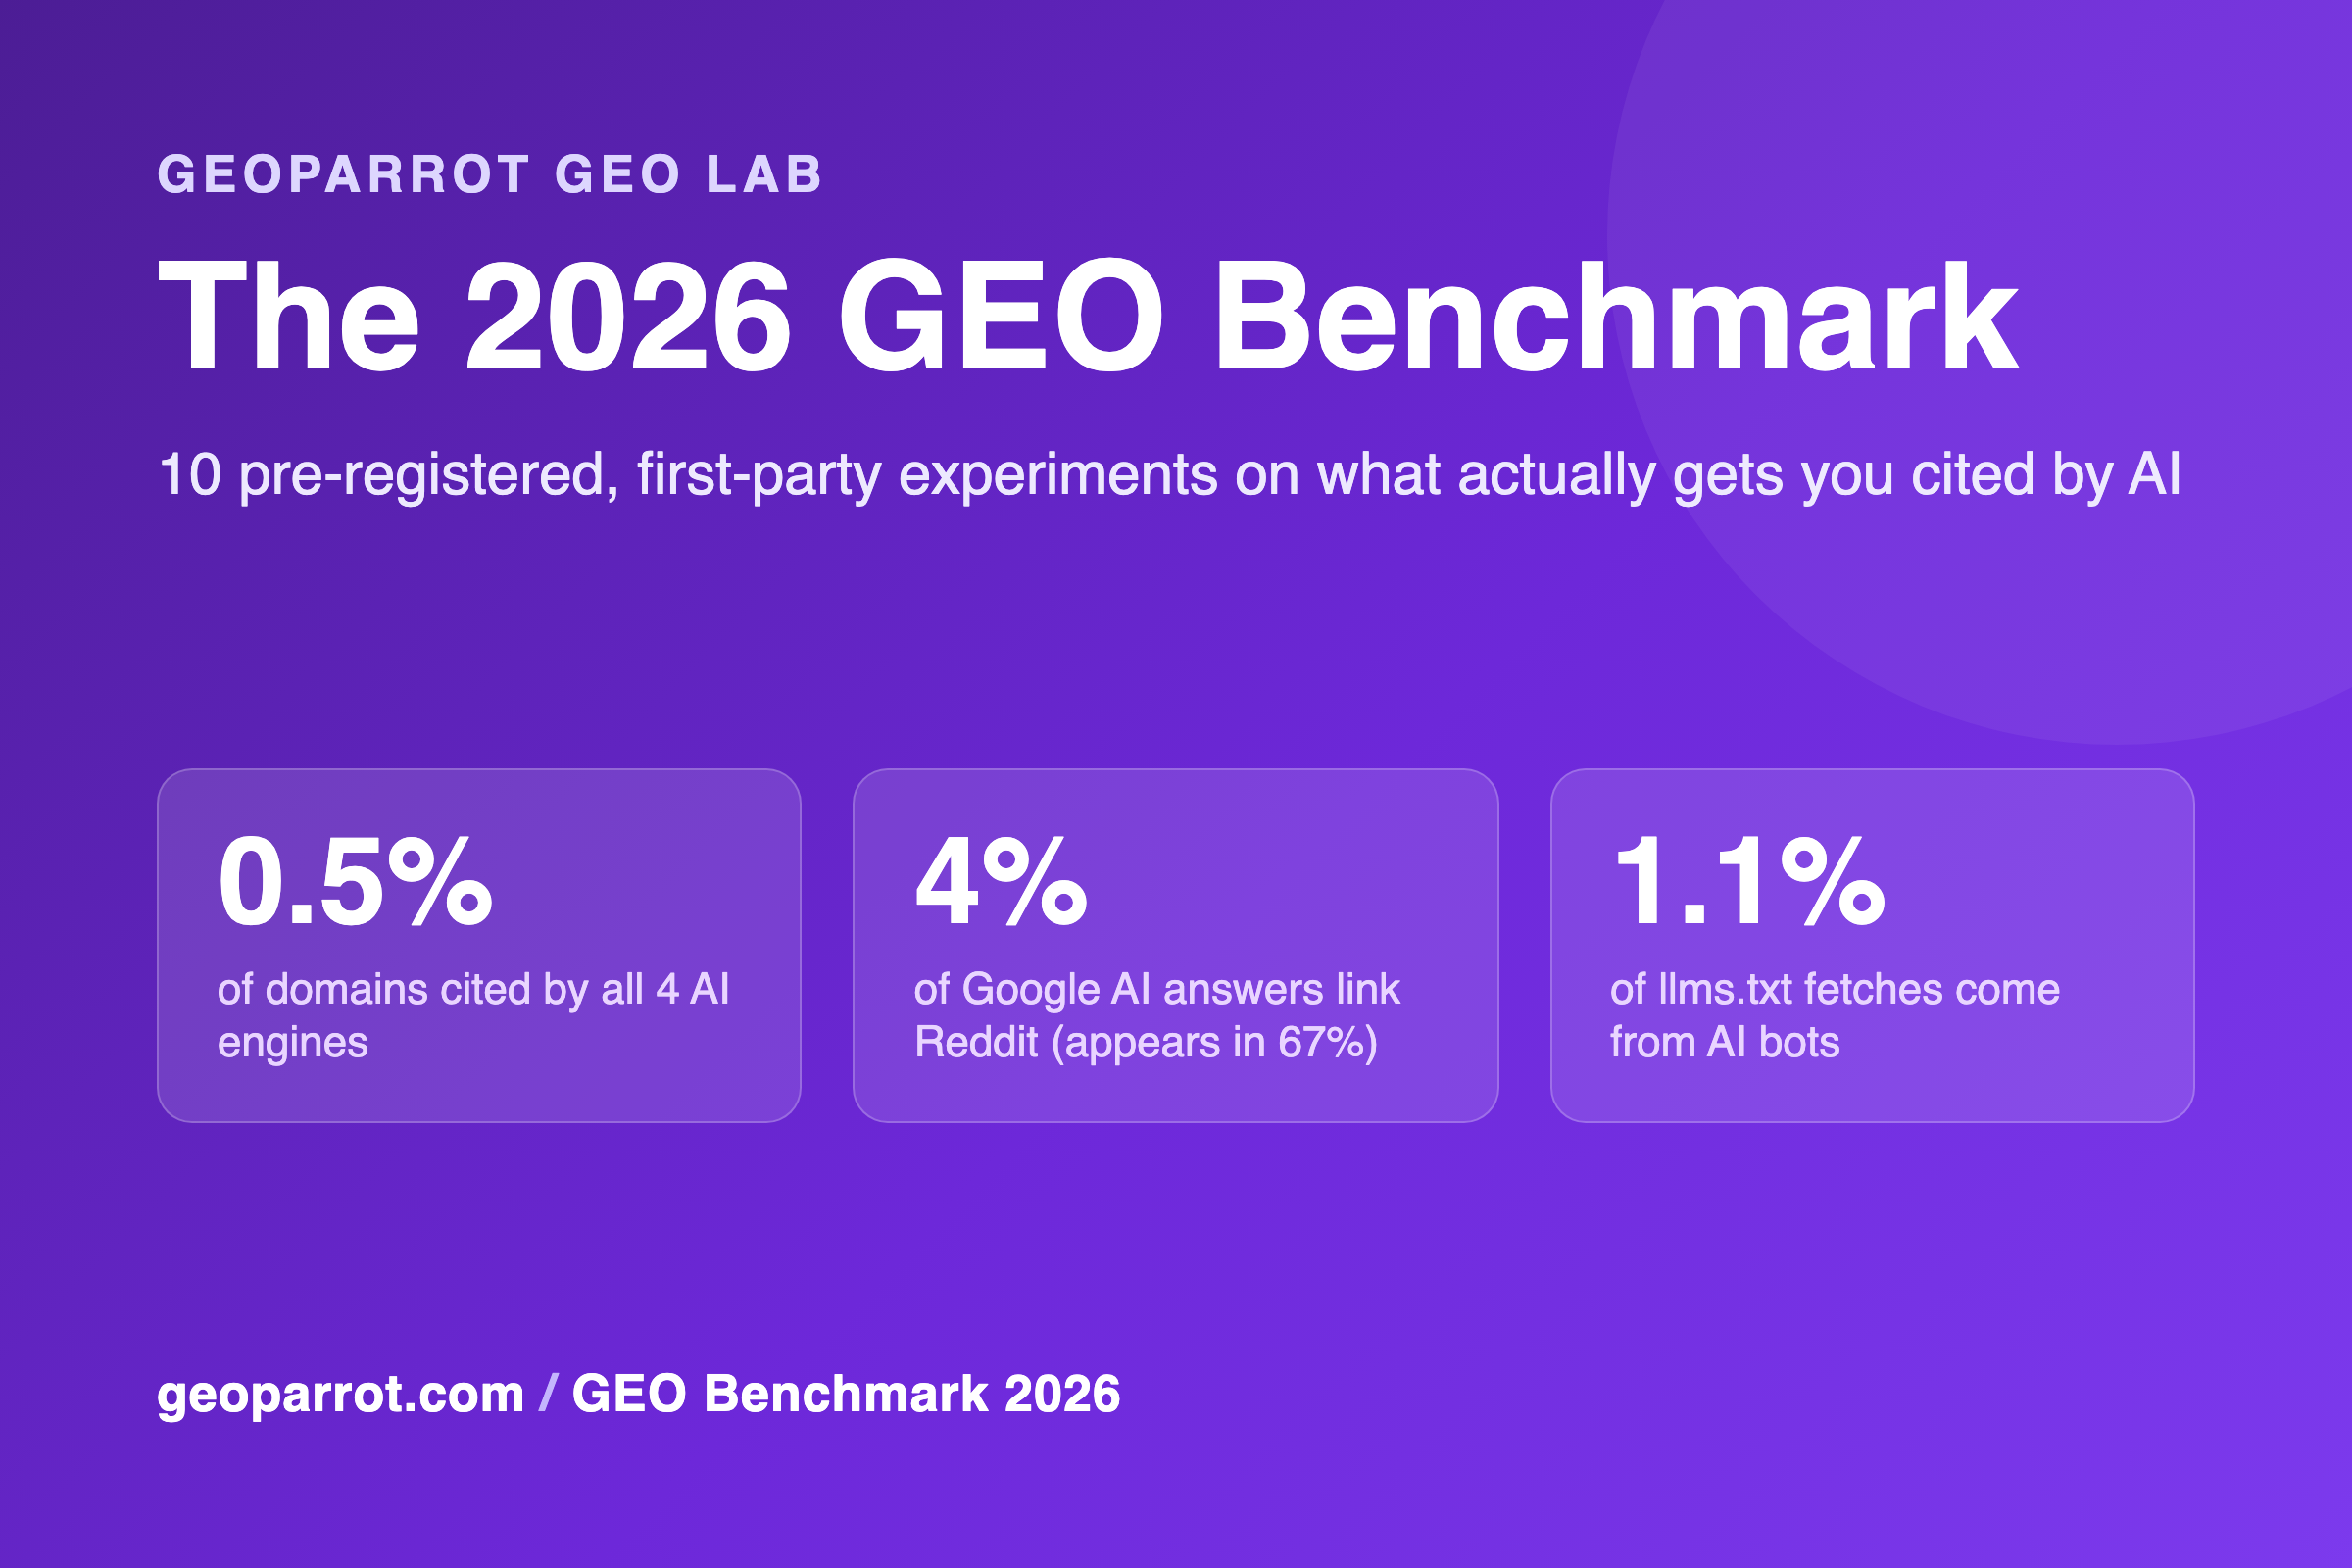
The 2026 GEO Benchmark: 10 First-Party Experiments on What Actually Gets You Cited by AI
The 2026 GEO Benchmark aggregates 10 pre-registered GeoParrot experiments into one citable dataset: cross-engine overlap of just 0.5%, Reddit cited 4% of the time, llms.txt fetched by AI bots 1.1% of the time, and more.
-
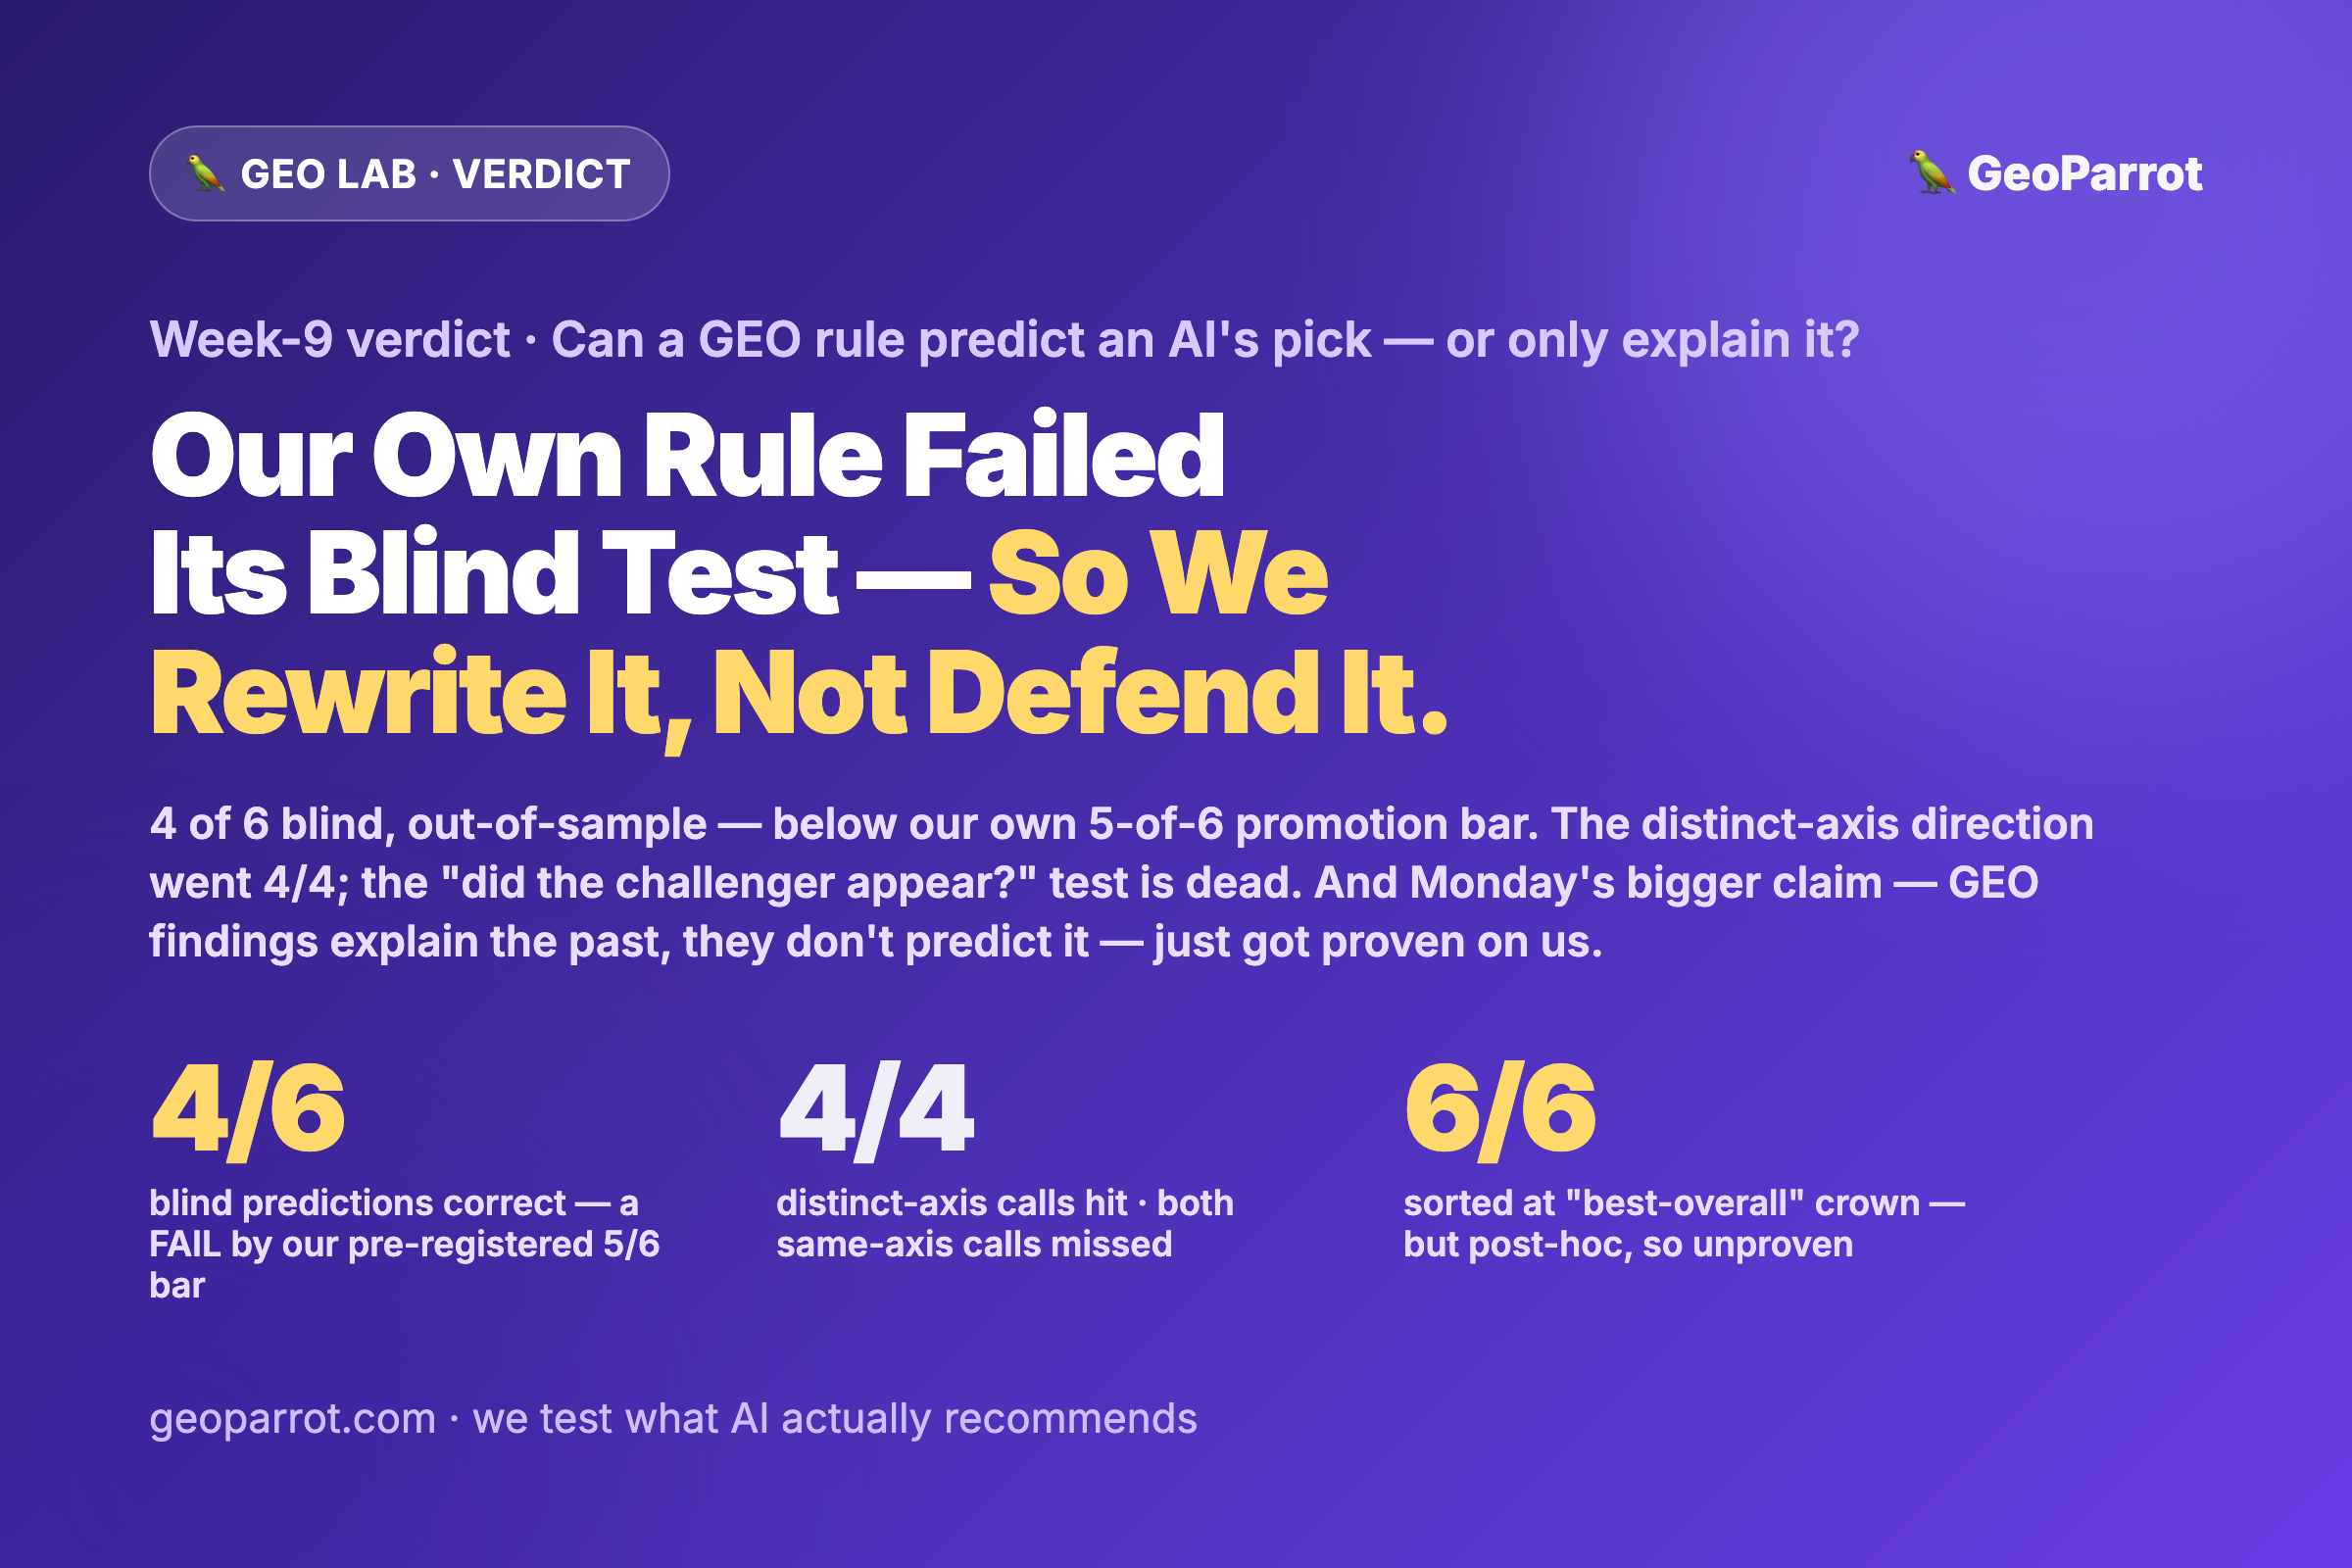
The Verdict: Our Geometry Rule Failed Its Own Blind Test at 4/6 — So We Rewrite It, Not Defend It. Monday’s Bigger Claim (GEO Findings Explain, They Don’t Predict) Just Got Proven on Us
All week we put our own geometry rule on the line: a challenger crosses the AI-search incumbency moat when it owns a distinct attribute axis, and stays held when it’s just a “better version” of the incumbent’s axis. We pre-registered 6 blind, out-of-sample predictions (4 CROSS, 2 HELD) with the pass line fixed in advance…
-
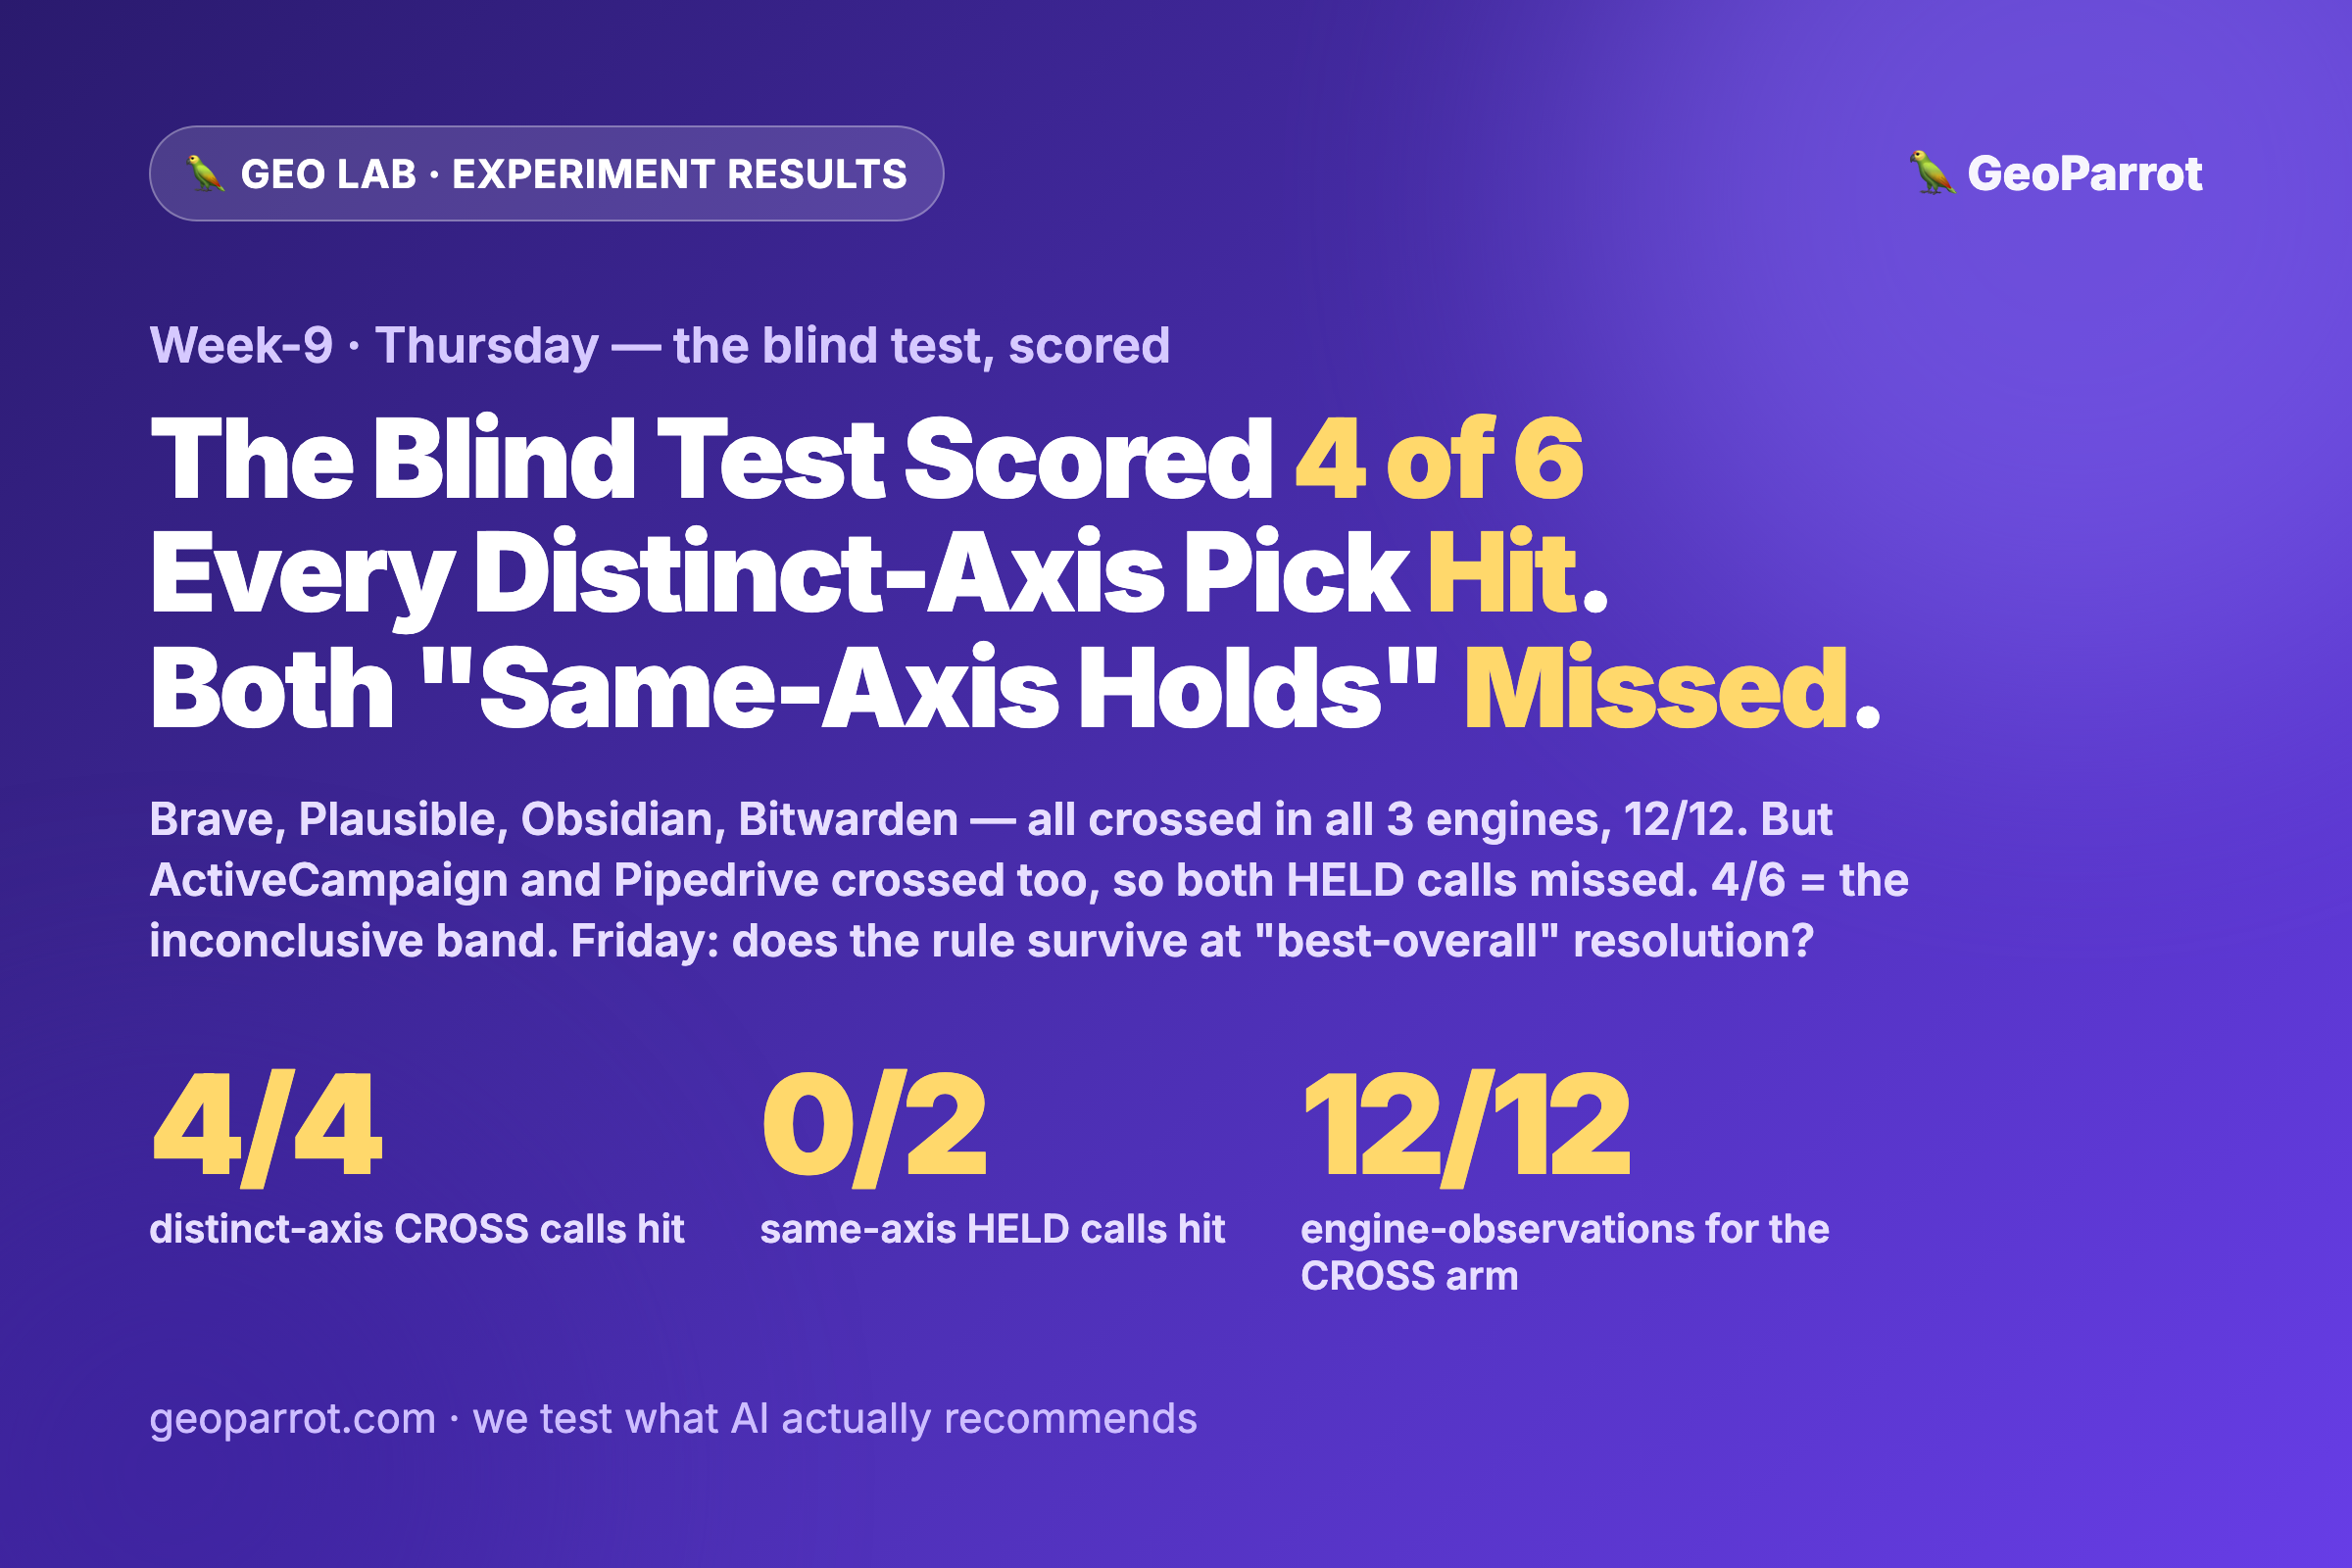
The Blind Test Scored 4 of 6: Our Geometry Rule Called Every Distinct-Axis Pick Correctly — and Missed Both “Same-Axis Holds” Because the Challenger Crossed Anyway
On Tuesday we locked 6 blind, out-of-sample predictions before querying a single engine: 4 said a distinct-axis challenger would cross into the AI’s recommendation set, 2 said a same-axis challenger would stay held. Today we queried ChatGPT, Perplexity, and Google AI Mode with a neutral “best [category] in 2026?” and scored against the frozen table.…
-
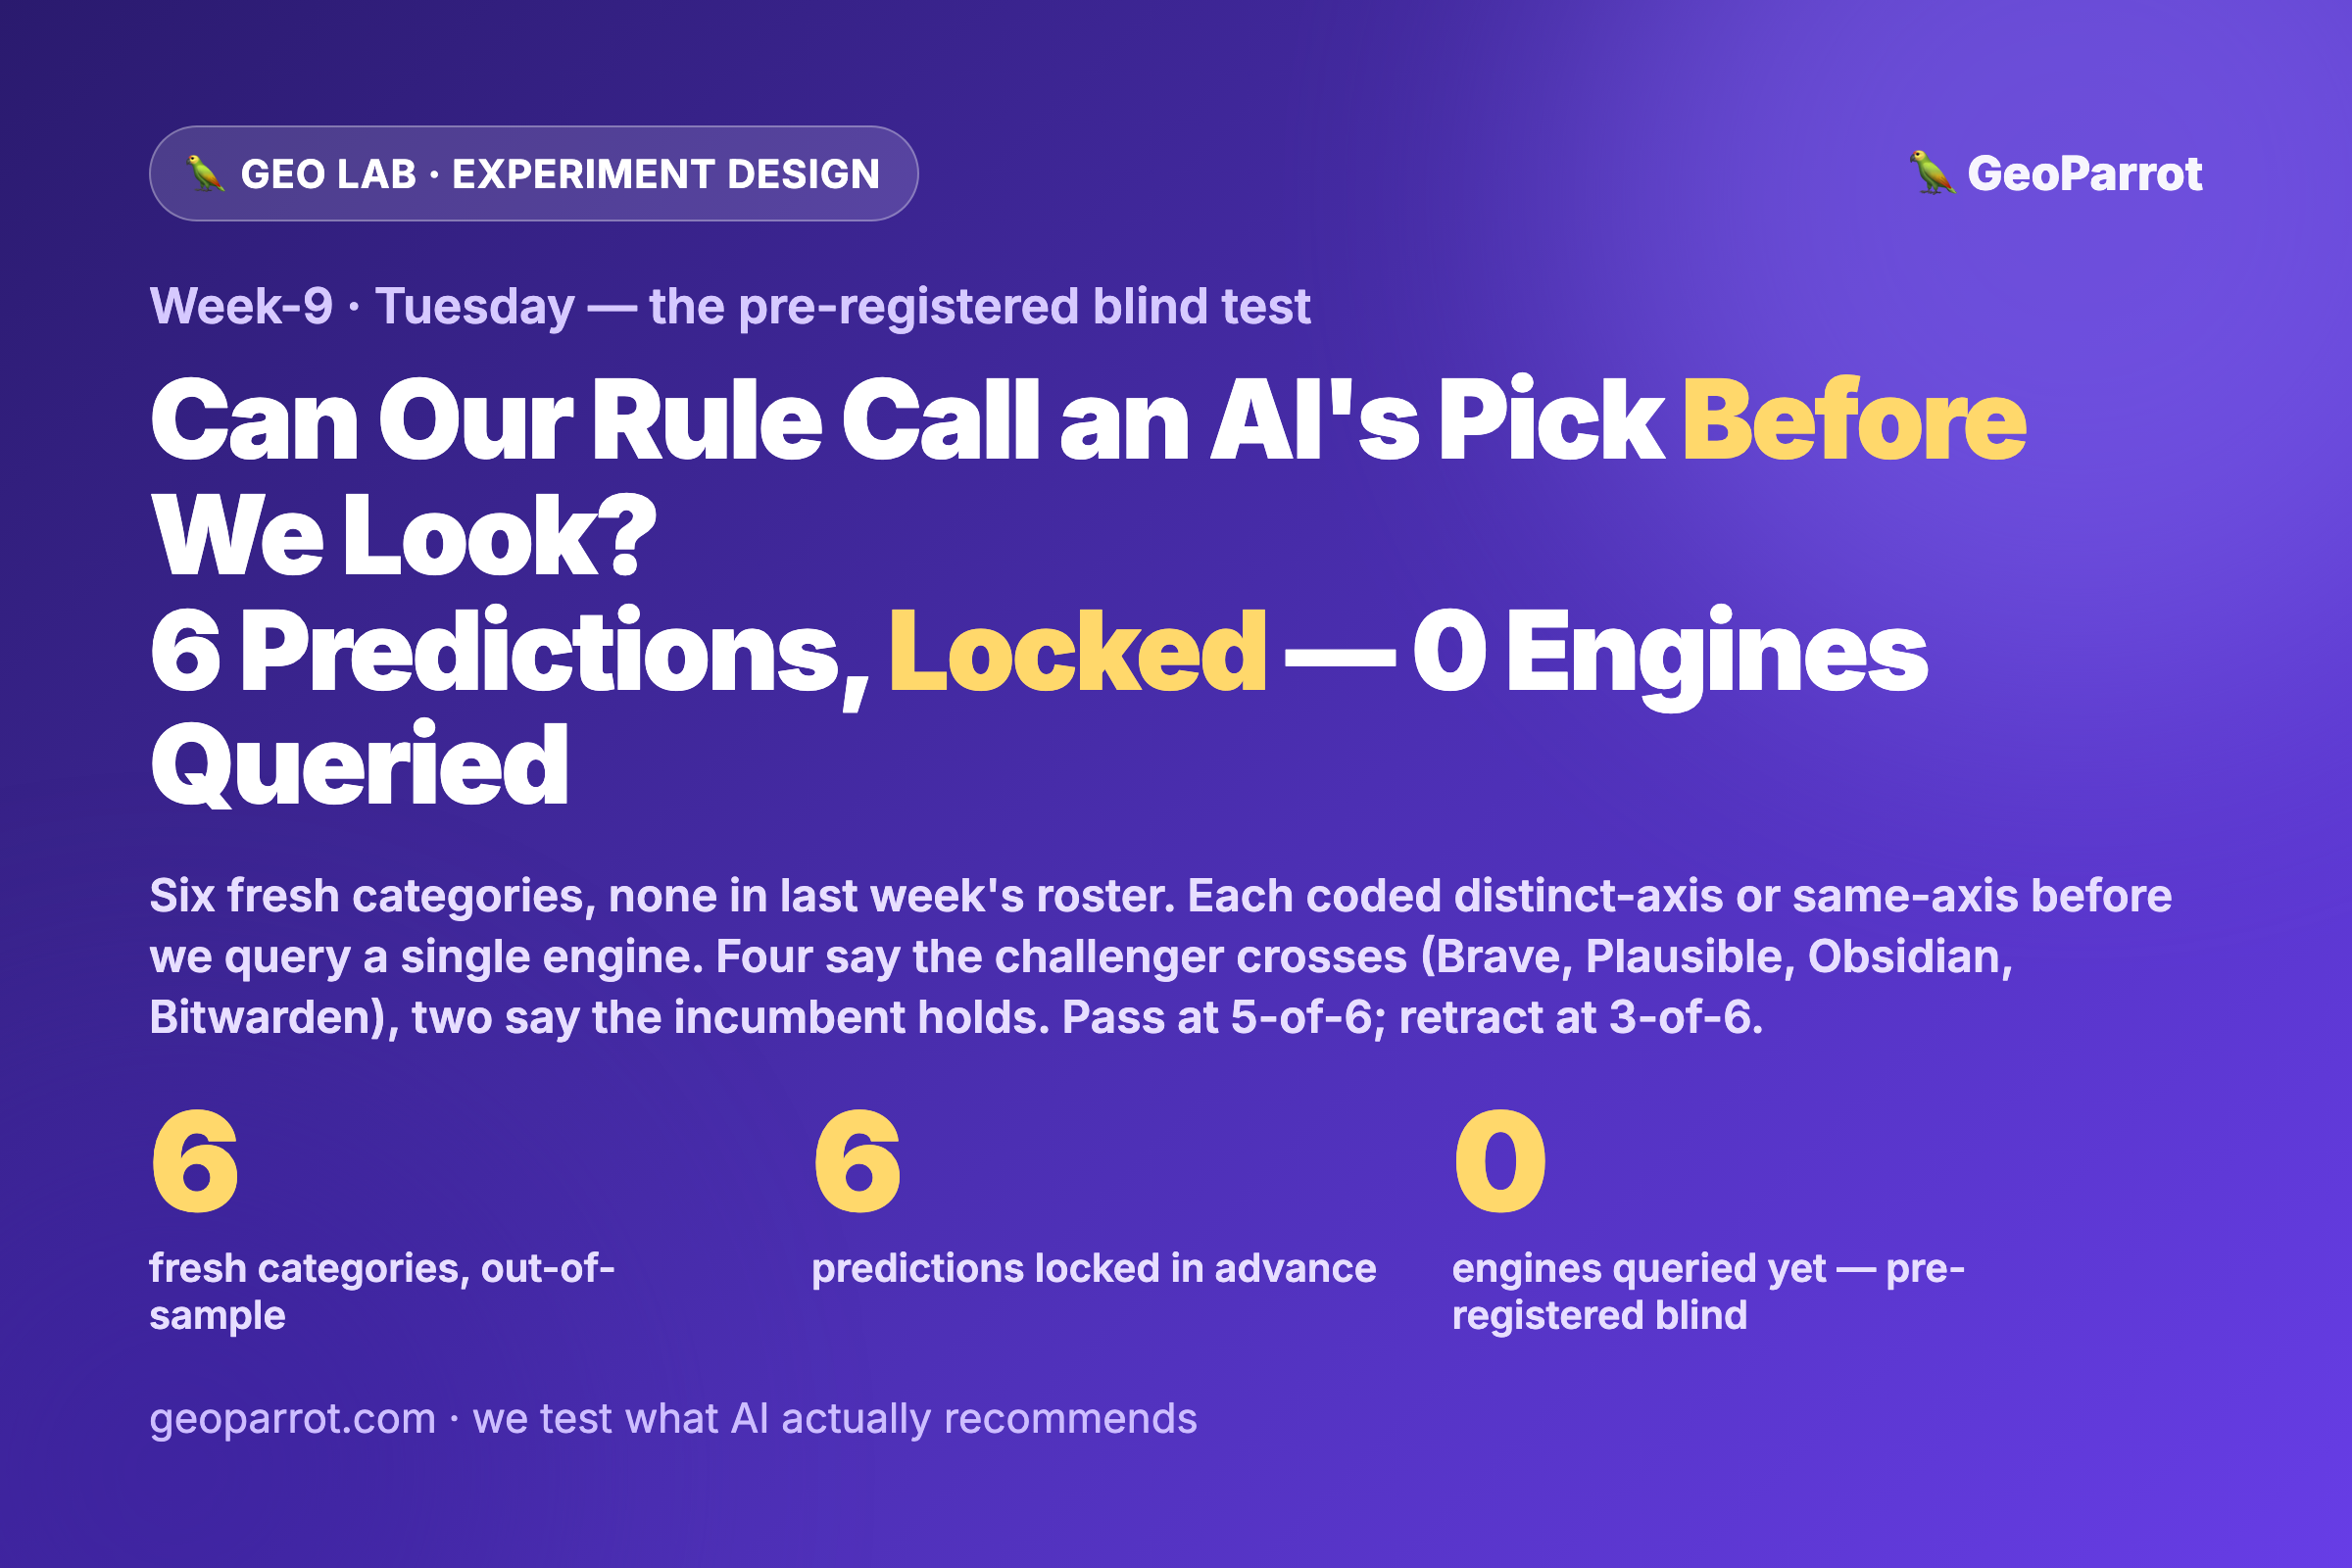
Can Our Geometry Rule Call an AI’s Pick Before We Look? We Pre-Register 6 Blind Predictions — Locked Here, Before a Single Engine Is Queried
Monday we admitted our own geometry-gate rule — a challenger crosses the AI-search incumbency moat when it owns a distinct attribute axis, and stays stuck when it’s a “better version” of the incumbent’s axis — fit last week’s data 6-for-6 only in hindsight: labels public, n=6, coded after we saw the picks. Today we put…
-
Most 2026 GEO “Findings” Explain the Past — They Don’t Predict. This Week We Test Whether Our Own Geometry Rule Can Call an AI’s Pick Before We Look
August 2026 produced a wave of impressive GEO studies — 680 million citations analyzed, a 46x brand-citation gap between ChatGPT (0.59%) and Perplexity (13.05%), 55+ data points on AI search behavior. All of it is real and useful, and almost all of it is retrodictive: it explains patterns in data already collected, correlationally, after the…
-
When Does an Earned Narrative Beat an Incumbent in AI Search? The Verdict: The Moat Is a Geometry Gate, Not a Size Threshold — Plus a Per-Category, Per-Engine Playbook
All week we hunted for the incumbency-moat threshold in AI search: how strong does an incumbent’s default have to be before a challenger’s earned narrative can’t cross it? The verdict on our frozen 6-category roster — zero engines re-queried — is that the threshold everyone looks for doesn’t exist. There is no size line. The…
-
The AI-Search Incumbency Moat Isn’t About the Incumbent’s Size — It’s the Challenger’s Narrative Axis. We Scored 6 Categories: Geometry 6-for-6, Magnitude Draws No Line
Tuesday we pre-registered two rival explanations for why a challenger crosses the AI-search incumbency moat in some categories and not others: the incumbent’s SIZE (magnitude) or the challenger’s NARRATIVE AXIS (geometry). We scored all 6 frozen categories with zero engine re-queries — and all four pre-registered predictions held. Magnitude drew no line: the biggest size…